On ConTEB, the preview has the highest average nDCG@10 of the models tested, though not on every task.
It also beats voyage-context-4 on chunk retrieval while using 8x less storage per vector: 1 KB (1024 dims, int8) vs 8 KB (2048, float32). https://t.co/PsyAwyU0Zo
pplx-embed-v2-context-9b-preview leads on Answer and Evidence retrieval at every cutoff.
Document retrieval is closer, with our context v1 4B slightly ahead at Document@3 and Document@5. https://t.co/9DrBG7sxPp
context-bench is a benchmark for context-aware retrieval, created and privately held by @turbopuffer. Its queries, documents and capabilities are inspired by conversations with turbopuffer customers.
It has 2,099 queries and 38,894 documents. We submitted for blind evaluation. h…
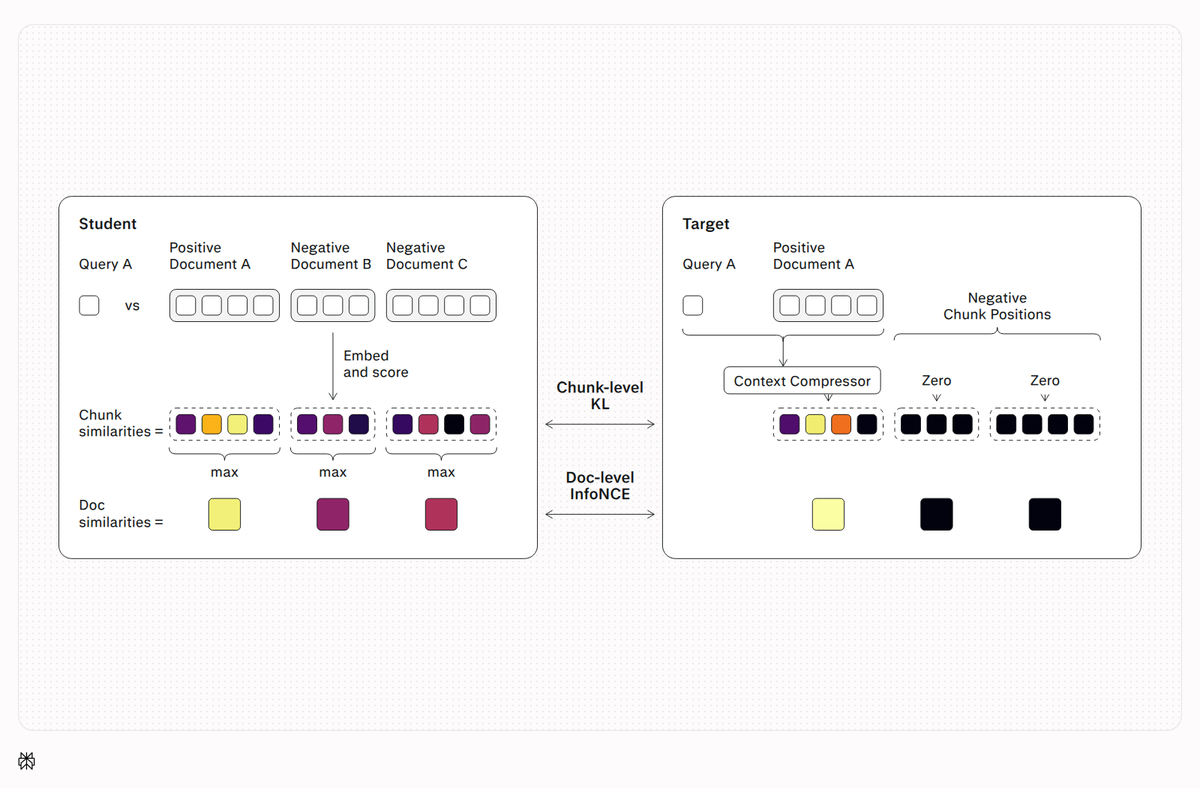
We overcome gold-chunk supervision limits by distilling relevance from our query-aware context compression model.
It scores every document token against the query. Aggregated into chunk-level targets, those scores train the embedder to retrieve answer and supporting chunks. http…
Retrieval systems often split long documents into chunks, but this strips away the surrounding context.
Contextual embedding models fix this by encoding the whole document once and pooling chunk vectors afterward.
They are usually trained on one gold chunk per query.
We built a new way to train contextual embedding models, which encode each chunk of a document with the whole document in view.
pplx-embed-v2-context-9b-preview sets a new state of the art on ConTEB and @turbopuffer's new, privately held context-bench.
https://t.co/tkBUEjWVio h…