PulseAugur
中
实时 17:43:24
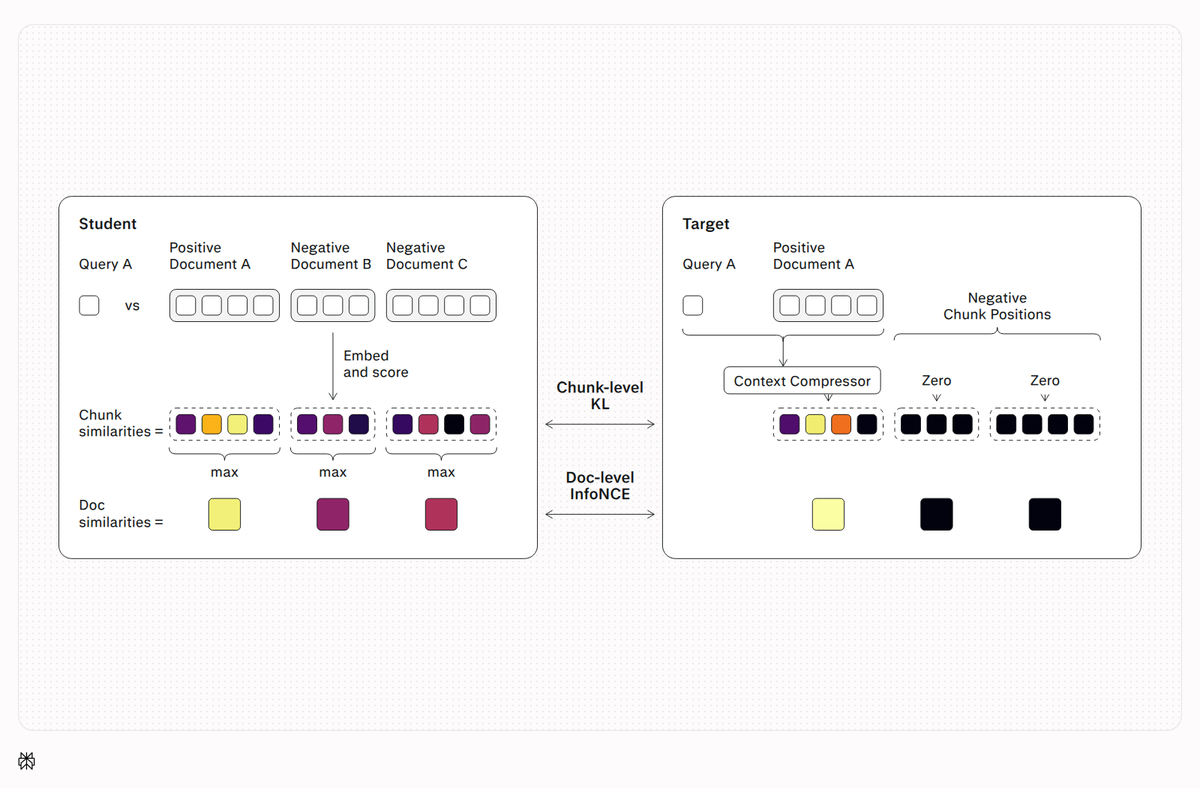
English(EN) We overcome gold-chunk supervision limits by distilling relevance from our query-aware context compression model.

Perplexity 发布新的上下文嵌入模型,在基准测试中达到 SOTA

Perplexity 推出了新的人工智能上下文嵌入模型 pplx-embed-v2-context-9b-preview,该模型在 ConTEB 和 context-bench 基准测试中设定了新的最先进水平。该模型在查看整个文档的情况下对每个文档块进行编码,解决了传统分块方法的局限性。它通过从查询感知的上下文压缩模型中提炼相关性来实现这一点,并提供比 voyage-context-4 等模型更节省空间的向量表示。 AI

影响 在检索基准测试中设定了新的 SOTA,可能改进 RAG 系统并提供更高效的向量存储。

排序理由 Frontier-lab 模型发布,附带系统卡。

在 X — Perplexity 阅读 →

AI 生成摘要 · Google Gemini · 来自 7 个来源。 我们如何撰写摘要 →

Perplexity 发布新的上下文嵌入模型,在基准测试中达到 SOTA

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Frontier Release
Frontier-lab 模型发布,附带系统卡。
Source corroboration
7 independent sources
Strong cross-source corroboration — multiple independent publishers covered this within the clustering window.
Topics
model release, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
7 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [7]

  1. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    在 Hugging Face 上查看 pplx-embed-v2-context-9b-preview:

    View pplx-embed-v2-context-9b-preview on Hugging Face: https://t.co/EeqI2xCFOl

  2. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    在 ConTEB 上,预览版在测试模型中拥有最高的平均 nDCG@10,尽管并非在所有任务上都如此。

    On ConTEB, the preview has the highest average nDCG@10 of the models tested, though not on every task. It also beats voyage-context-4 on chunk retrieval while using 8x less storage per vector: 1 KB (1024 dims, int8) vs 8 KB (2048, float32). https://t.co/PsyAwyU0Zo

  3. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    pplx-embed-v2-context-9b-preview 在每次截止时在答案和证据检索方面领先。

    pplx-embed-v2-context-9b-preview leads on Answer and Evidence retrieval at every cutoff. Document retrieval is closer, with our context v1 4B slightly ahead at Document@3 and Document@5. https://t.co/9DrBG7sxPp

  4. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    context-bench 是一个用于上下文感知检索的基准测试,由 @turbopuffer 创建并私有持有。其查询、文档和能力受到 co 的启发

    context-bench is a benchmark for context-aware retrieval, created and privately held by @turbopuffer. Its queries, documents and capabilities are inspired by conversations with turbopuffer customers. It has 2,099 queries and 38,894 documents. We submitted for blind evaluation. h…

  5. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    我们通过从查询感知上下文压缩模型中提炼相关性来克服黄金块监督的限制。

    We overcome gold-chunk supervision limits by distilling relevance from our query-aware context compression model. It scores every document token against the query. Aggregated into chunk-level targets, those scores train the embedder to retrieve answer and supporting chunks. http…

  6. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    检索系统通常将长文档分割成块,但这会剥离周围的上下文。

    Retrieval systems often split long documents into chunks, but this strips away the surrounding context. Contextual embedding models fix this by encoding the whole document once and pooling chunk vectors afterward. They are usually trained on one gold chunk per query.

  7. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    我们构建了一种训练上下文嵌入模型的新方法,该方法在查看整个文档的情况下对文档的每个块进行编码。

    We built a new way to train contextual embedding models, which encode each chunk of a document with the whole document in view. pplx-embed-v2-context-9b-preview sets a new state of the art on ConTEB and @turbopuffer's new, privately held context-bench. https://t.co/tkBUEjWVio h…