PulseAugur
中
实时 05:41:08
English(EN) Generate images and video with vLLM-Omni on SageMaker AI – Part 2

AWS SageMaker AI 支持文本到图像和视频生成

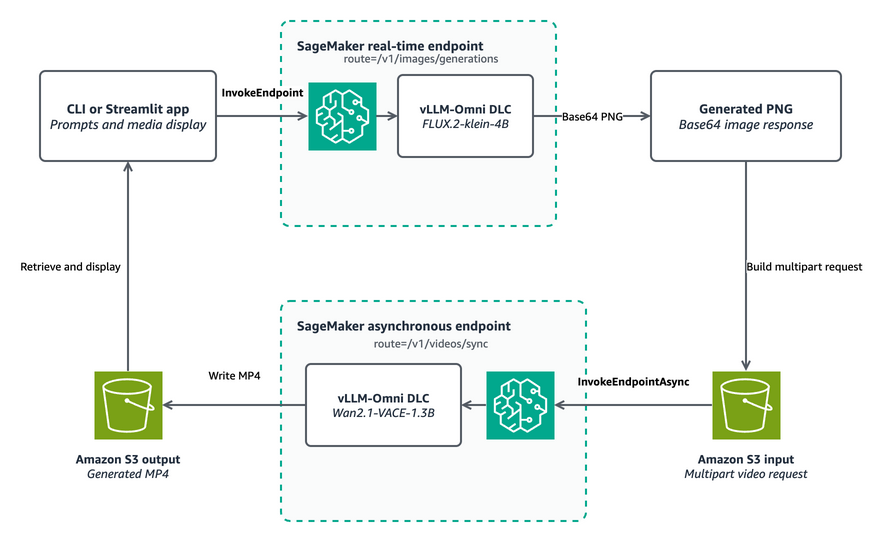
AWS 在 SageMaker AI 上推出了一项新功能,允许用户根据文本提示生成图像和视频。这是通过从同一个 AWS vLLM-Omni 深度学习容器部署两个不同的端点来实现的:一个使用 FLUX.2-klein-4B 进行实时图像生成,另一个使用 Wan2.1-VACE-1.3B 进行异步视频生成。该过程包括发送文本提示来创建图像,然后将该图像与运动提示一起用于生成视频,最终输出存储在 Amazon S3 中。 AI

影响 使用户能够直接在 AWS SageMaker AI 上生成图像和视频,从而简化了多模态内容创建工作流程。

排序理由 文章描述了在现有平台(SageMaker AI)上使用特定模型和容器的新功能和工作流程,而不是发布新模型或基础研究。

在 AWS Machine Learning Blog 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
AWS SageMaker AI 支持文本到图像和视频生成

本文如何被排名

Signal score
1 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
文章描述了在现有平台(SageMaker AI)上使用特定模型和容器的新功能和工作流程,而不是发布新模型或基础研究。
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
product, infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
1 days old
Coverage has settled into its steady-state source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. AWS Machine Learning Blog TIER_1 English(EN) · Yadan Wei ·

    使用 SageMaker AI 和 vLLM-Omni 生成图像和视频 – 第二部分

    Deploy two generative media models from one AWS vLLM-Omni Deep Learning Container on Amazon SageMaker AI. Generate an image with FLUX.2-klein through real-time inference, then animate it into video with Wan2.1-VACE through asynchronous inference, and retrieve the MP4 from Amazon …