PulseAugur
中
实时 15:56:59
English(EN) Scaling RAG to Production: Why 10 Million Documents Is a Different Sport

将 RAG 扩展到 1000 万份文档需要先进的摄取和检索技术

将检索增强生成(RAG)系统从几千份文档扩展到数百万份会带来重大挑战,这些挑战常常会破坏简单的实现。生产规模的 RAG 需要强大的摄取管道,能够使用 Apache Tika、Unstructured 和 Docling 等工具处理各种文件格式,以提取文本和结构元数据。有效的分块策略至关重要,优先考虑语义完整性和保留文档结构,而不是固定大小的分割,LlamaIndex 等工具提供了高级方法。在规模化方面,向量搜索依赖于 HNSW 等近似最近邻算法来提高速度,这需要元数据过滤和预先计算的块摘要来提高检索准确性。 AI

影响 强调了大规模构建生产就绪 RAG 系统的工程挑战和解决方案,影响了 AI 应用开发。

排序理由 文章讨论了扩展 RAG 系统的实际实现细节和工具,而不是新的模型发布或研究突破。

在 dev.to — LLM tag 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
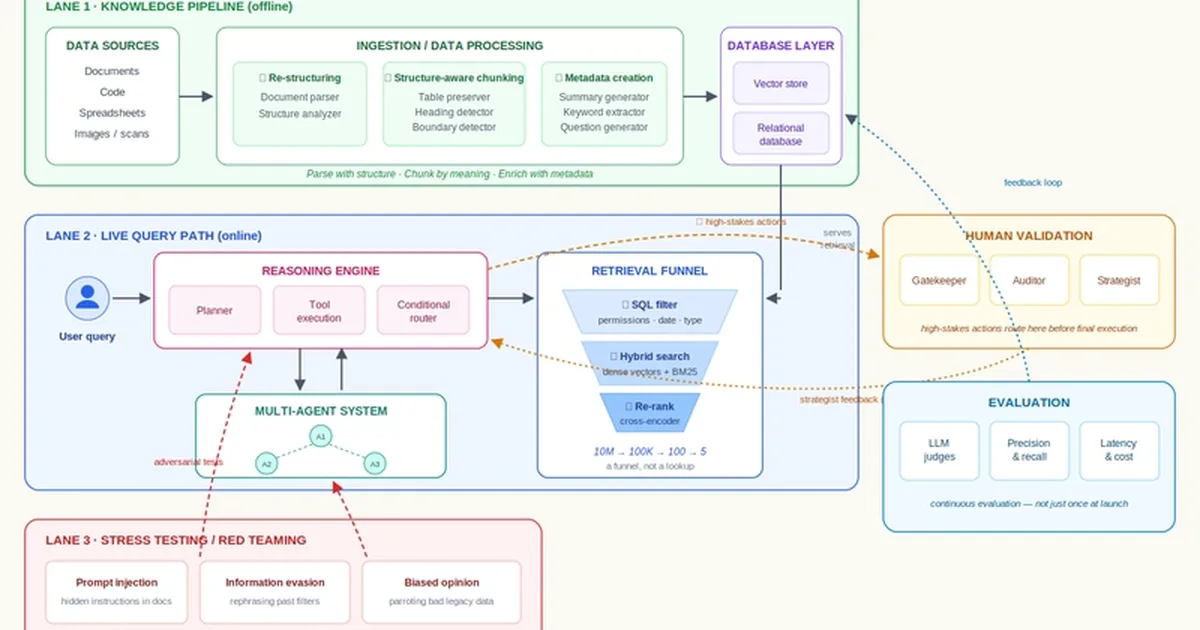
将 RAG 扩展到 1000 万份文档需要先进的摄取和检索技术

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
文章讨论了扩展 RAG 系统的实际实现细节和工具,而不是新的模型发布或研究突破。
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
90 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. dev.to — LLM tag TIER_1 English(EN) · manubolu umamahesh ·

    将 RAG 扩展到生产环境:为何 1000 万份文档是另一项挑战

    <p>Building a RAG chatbot for 1,000 clean PDFs takes an afternoon: one retriever, one vector store, about 20 lines of LangChain glue. I know, because I built and deployed one (<a href="https://mahesh-blue.vercel.app" rel="noopener noreferrer">mahesh-blue.vercel.app</a>) - documen…