PulseAugur
中
实时 01:54:48
English(EN) Qwen 3.5 vs Ornith 1.0 9B Models, Same Hardware, Same Quant as Coding Agents

Qwen 3.5 和 Ornith 1.0 模型作为代码代理失败

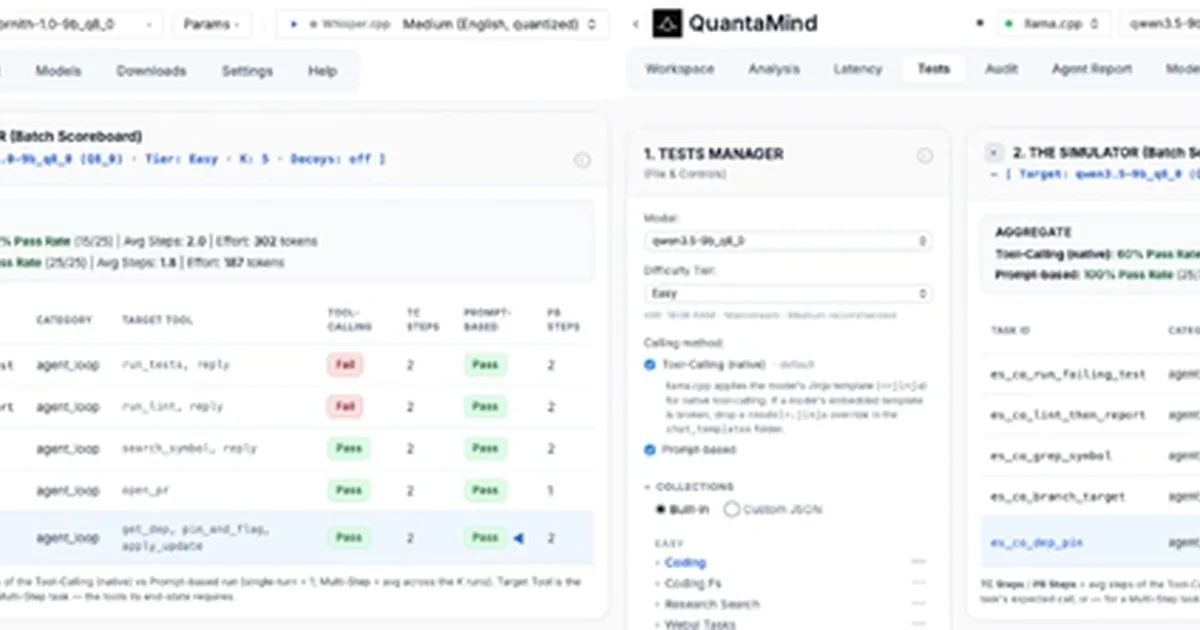
对 Qwen 3.5 9B 和 Ornith 1.0 9B 模型的比较显示,即使在标准硬件上,两者都未准备好用作代码代理。两个模型都未能通过最简单的代理任务级别,原生工具调用 API 的表现不如简单的提示。虽然两个模型都表现出危险的故障模式,例如幻觉式地完成任务或在更难的任务中进入无限循环,但 Qwen 3.5 9B 更容易输出散文而不是工具调用,而 Ornith 1.0 9B 更频繁地出现幻觉式完成。 AI

影响 强调了当前 9B 模型在代理任务方面的局限性,并质疑了原生工具调用 API 的有效性。

排序理由 对两个特定 LLM 模型在代理能力方面的比较。[lever_c_demoted from research: ic=1 ai=1.0]

在 dev.to — LLM tag 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
Qwen 3.5 和 Ornith 1.0 模型作为代码代理失败

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
对两个特定 LLM 模型在代理能力方面的比较。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
model release, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
93 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. dev.to — LLM tag TIER_1 English(EN) · Dhanush G ·

    Qwen 3.5 对比 Ornith 1.0 9B 模型,同硬件、同量化作为代码代理

    <p>I ran Qwen 3.5 9B and Ornith 1.0 9B, both at Q8, on the same 16GB Mac, through the same multi-step agent tests. Neither is agent-ready. But they're not ready in interesting, different ways — and the most surprising result is that the native tool-calling API made both of them w…