PulseAugur
中
实时 22:19:45
English(EN) Sakana Trained One AI to Command GPT-5.5,

Sakana AI模型在SWE-Bench Pro上超越Claude Opus和GPT-5.5

总部位于东京的Sakana实验室开发了一个能够指挥GPT-5.5的AI模型,在SWE-Bench Pro基准测试中取得了73.7分。这一成绩超过了Anthropic的Claude Opus 4.8(得分为69.2)和OpenAI的GPT-5.5(得分为58.6)。该开发突显了AI代理能力和基准测试性能的进步。 AI

影响 这一发展为AI代理在编码任务中的性能设定了新的基准,可能影响未来的模型开发和评估。

排序理由 该条目报道了一个AI模型的新基准分数,这是一个研究里程碑。[lever_c_demoted from research: ic=1 ai=1.0]

在 Towards AI 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
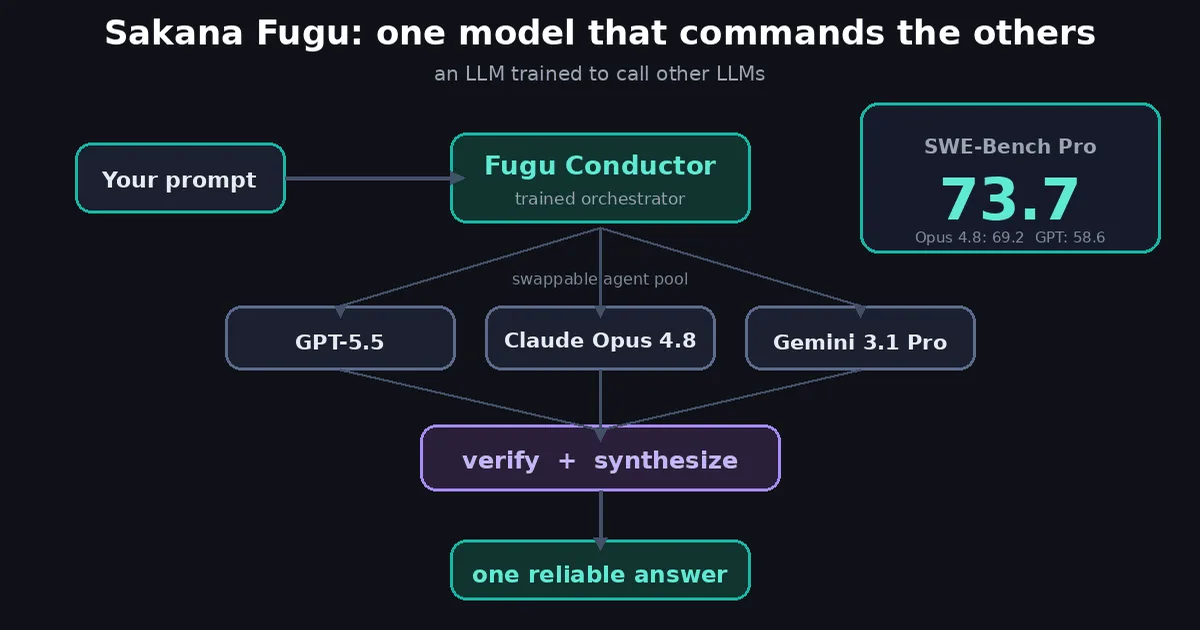
Sakana AI模型在SWE-Bench Pro上超越Claude Opus和GPT-5.5

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该条目报道了一个AI模型的新基准分数,这是一个研究里程碑。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
model release, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
97 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Towards AI TIER_1 English(EN) · Chew Loong Nian - AI ENGINEER ·

    Sakana训练了一个AI来指挥GPT-5.5。

    <div class="medium-feed-item"><p class="medium-feed-image"><a href="https://pub.towardsai.net/sakana-trained-one-ai-to-command-gpt-5-5-ed3725ba9187?source=rss----98111c9905da---4"><img src="https://cdn-images-1.medium.com/max/1200/1*5StdTHu9BxnSeFUGaBrPEw.png" width="1200" /></a>…