PulseAugur
中
实时 02:38:44

New benchmarks and evaluation methods for health LLMs emerge

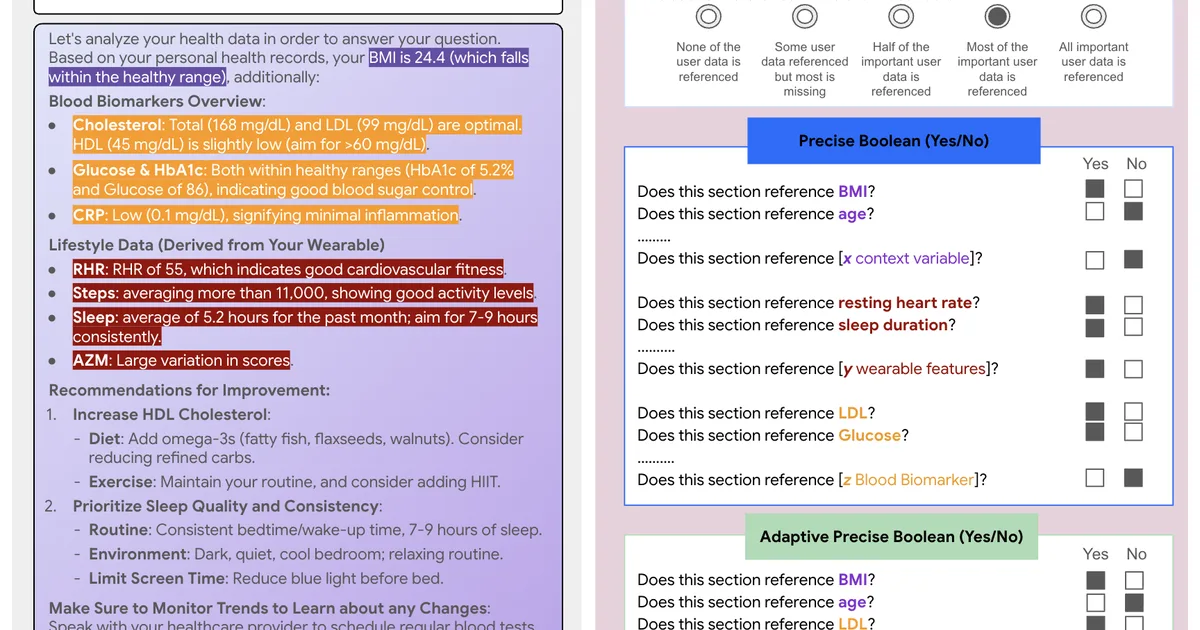
研究人员开发了AfriMed-QA,这是一个用于评估大型语言模型(LLMs)在非洲健康问答任务上表现的新基准数据集。该数据集与非洲组织合作创建,并得到了盖茨基金会的支持,包含了来自16个非洲国家的消费者查询和医学院考试问题。此外,还引入了一种新的自适应且精确的评分标准方法,以简化健康语言模型的评估,旨在提高可扩展性和评分者间一致性。另外,一项研究探讨了使用LLMs为公共卫生建模生成合成调查回复,发现虽然LLMs可以重现人口统计和行为模式,但合成数据仍然可识别,尚不能替代真实的调查数据。 AI

影响 这些在LLM评估和数据集创建方面的进展对于开发更公平、更有效的全球健康应用AI工具至关重要。

排序理由 该集群包含介绍健康领域LLM新数据集和评估方法的学术论文。

在 Google AI / Research 阅读 →

AI 生成摘要 · Google Gemini · 来自 3 个来源。 我们如何撰写摘要 →
New benchmarks and evaluation methods for health LLMs emerge

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
该集群包含介绍健康领域LLM新数据集和评估方法的学术论文。
Source corroboration
3 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
paper, product, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
411 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [3]

  1. Google AI / Research TIER_1 English(EN) ·

    AfriMed-QA:用于全球健康的语言大模型基准测试

    Generative AI

  2. Google AI / Research TIER_1 English(EN) ·

    一种可扩展的健康语言模型评估框架

    Generative AI

  3. arXiv cs.CL TIER_1 English(EN) · Raffaele Vardavas ·

    使用调查增强的大型语言模型生成公共卫生响应

    Epidemiological models often rely on survey data to represent how individuals make health-related decisions, such as whether to vaccinate or adopt protective behaviors. However, repeated large-scale surveys are costly, time-consuming, and limited in the range of scenarios they ca…