PulseAugur
中
实时 06:44:23
English(EN) Claude Opus 4.6 vs 4.7 vs 4.8: 12 Real API Tests Through Crazyrouter

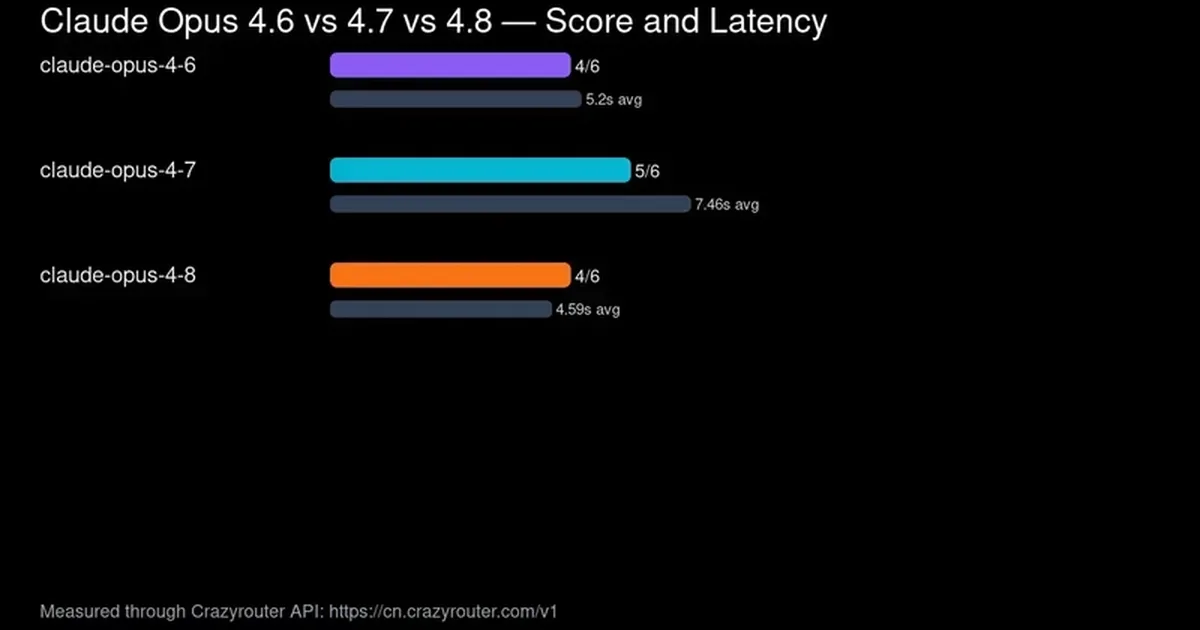
测试显示,Claude Opus 4.7在准确性方面领先,4.8在速度方面领先

近期对Anthropic的Claude Opus模型4.6、4.7和4.8的比较揭示了其独特的性能特征。Opus 4.7在各种实际开发者任务中表现出最高的成功率,而Opus 4.8提供了最快的平均响应时间。通过Crazyrouter进行的实时API调用进行的分析表明,特定任务的路由比简单地默认使用最新模型版本更有效。 AI

影响 Claude Opus模型的特定任务路由对于优化代理工作流程至关重要,能够在准确性和延迟需求之间取得平衡。

排序理由 该集群包含对现有AI模型不同版本的比较分析,详细说明了在特定任务上的性能指标。[lever_c_demoted from research: ic=1 ai=1.0]

在 dev.to — LLM tag 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
测试显示,Claude Opus 4.7在准确性方面领先,4.8在速度方面领先

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该集群包含对现有AI模型不同版本的比较分析,详细说明了在特定任务上的性能指标。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
model release, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
127 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. dev.to — LLM tag TIER_1 English(EN) · Jenny Met ·

    Claude Opus 4.6 vs 4.7 vs 4.8:通过 Crazyrouter 进行 12 项真实 API 测试

    <h1> Claude Opus 4.6 vs 4.7 vs 4.8: 12 Real API Tests Through Crazyrouter </h1> <p>Most Claude comparison posts repeat vendor claims. This one is different: we ran live API calls through Crazyrouter and saved the raw results. The goal was not to crown a universal winner; it was t…