PulseAugur
中
实时 08:10:08
English(EN) NVIDIA Drops a Model “LocateAnything”

NVIDIA 发布 LocateAnything 模型用于视觉定位

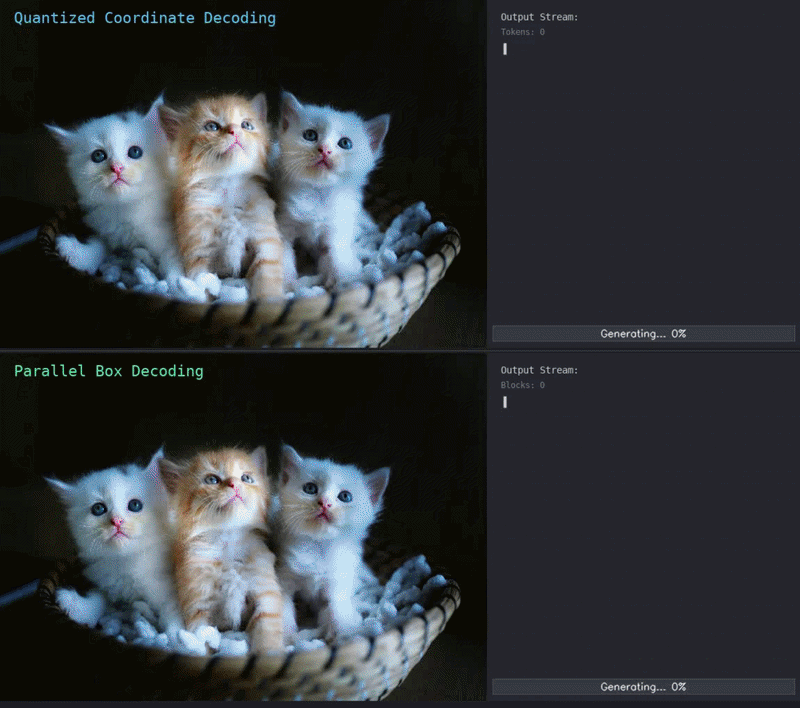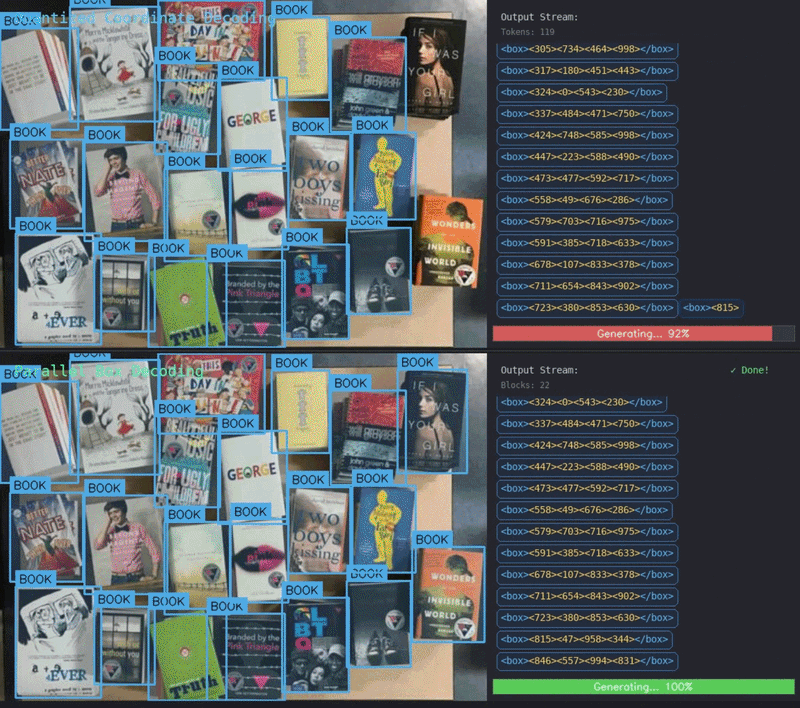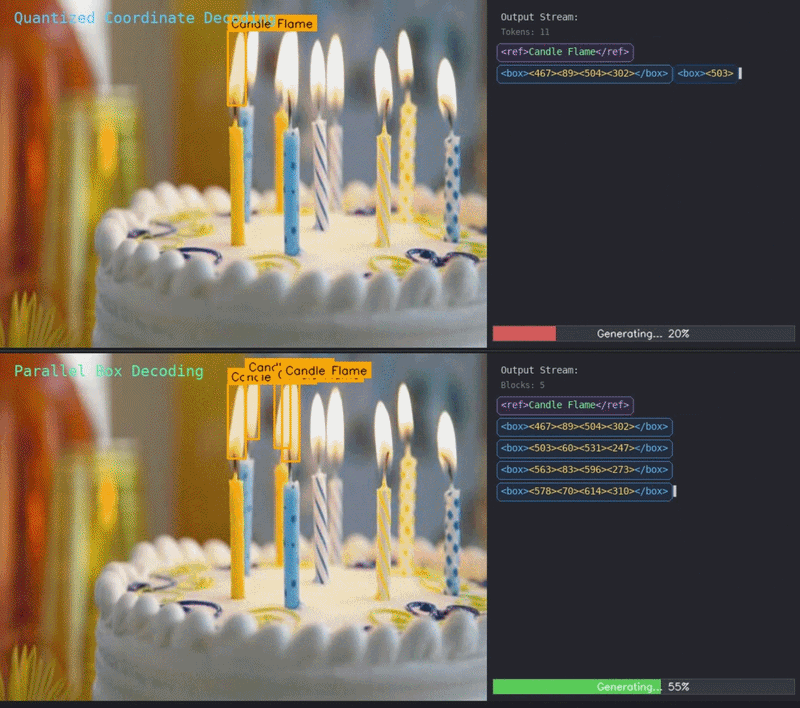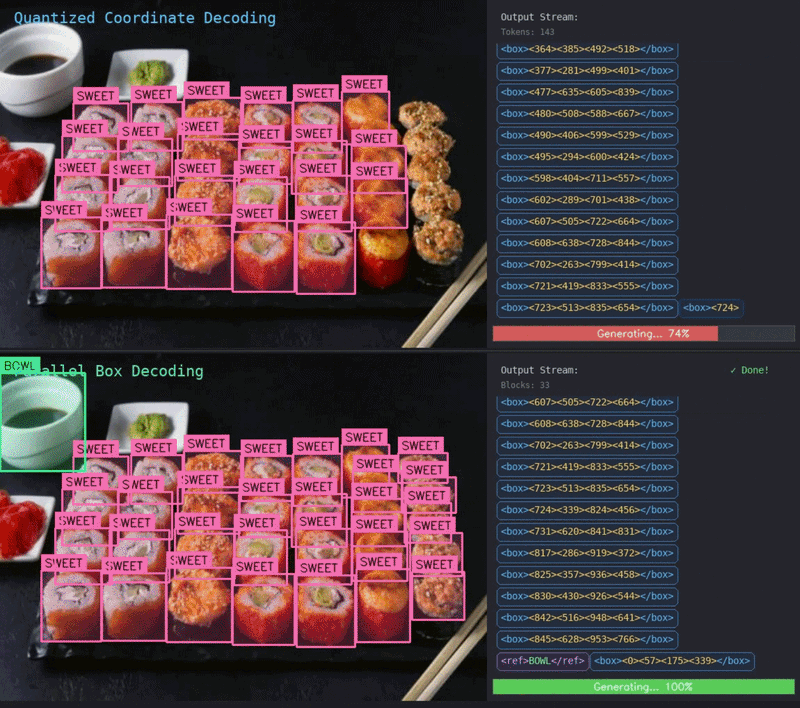
NVIDIA 推出了 LocateAnything,一个专为视觉定位任务设计的新模型。该模型利用并行盒解码将视觉定位转化为基础代理能力。此举旨在增强 AI 代理与视觉信息交互和理解的方式。 AI

影响 通过提供更强大的视觉定位方法来增强 AI 代理的能力。

排序理由 该集群描述了一家主要科技公司的新模型发布,属于研究或产品发布类别。[lever_c_demoted from research: ic=1 ai=1.0]

在 Towards AI 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
NVIDIA 发布 LocateAnything 模型用于视觉定位

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该集群描述了一家主要科技公司的新模型发布,属于研究或产品发布类别。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
model release, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
124 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Towards AI TIER_1 English(EN) · Mandar Karhade, MD. PhD. ·

    NVIDIA 发布模型“LocateAnything”

    <div class="medium-feed-item"><p class="medium-feed-image"><a href="https://pub.towardsai.net/nvidia-drops-a-model-locateanything-e0c50de7326d?source=rss----98111c9905da---4"><img src="https://cdn-images-1.medium.com/max/800/1*wxCzRjBkw6vQb0iNKSgDdA.gif" width="800" /></a></p><p …