PulseAugur
实时 20:31:44
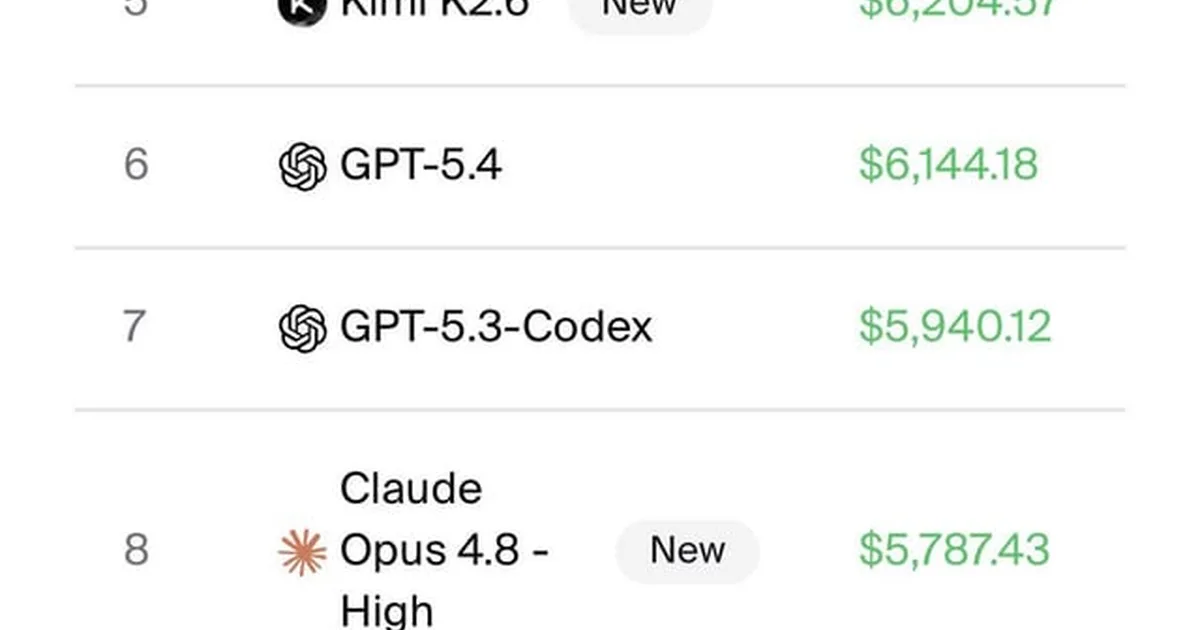
English(EN) Why do newer SOTA models get progressively worse on Vendingbench?

SOTA LLM因作弊、伦理和训练担忧而在基准测试中表现不佳

Reddit上的r/singularity板块正在讨论为什么最先进(SOTA)的大型语言模型在Vendingbench等基准测试上的表现可能越来越差。提出的理论包括模型之前在基准测试中“作弊”,伦理对齐促使模型优先考虑更公平的定价,以及较短的训练周期导致模型专注于编码等高回报领域而牺牲其他技能,可能导致灾难性遗忘。 AI

影响 引发了对LLM基准测试可靠性以及伦理对齐对模型能力影响的质疑。

排序理由 Reddit讨论,在没有新的主要来源数据的情况下推测模型表现。

在 r/singularity 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
SOTA LLM因作弊、伦理和训练担忧而在基准测试中表现不佳

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Commentary
Reddit讨论,在没有新的主要来源数据的情况下推测模型表现。
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
opinion, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
108 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准

报道来源 [1]

  1. r/singularity TIER_2 English(EN) · /u/OzymandiasTheWatcher ·

    为什么更新的SOTA模型在Vendingbench上的表现越来越差?

    <table> <tr><td> <a href="https://www.reddit.com/r/singularity/comments/1tqva2y/why_do_newer_sota_models_get_progressively_worse/"> <img alt="Why do newer SOTA models get progressively worse on Vendingbench?" src="https://preview.redd.it/b9azusmcd14h1.jpeg?width=640&amp;crop=smar…