PulseAugur
中
实时 16:03:00
English(EN) How to Generate and Use Synthetic Data for Finetuning

AI模型现在可以使用合成数据进行微调,降低成本和隐私风险

合成数据,由模型或模拟而非真实世界来源生成,为微调AI模型提供了比人工标注更快、更具成本效益的替代方案。这种方法可以提高模型性能和泛化能力,同时减轻隐私和版权问题。生成合成数据的两种主要方法包括从更强大的模型进行蒸馏以及模型自身改进其输出的自改进技术。这些方法可应用于预训练、指令微调和偏好微调,以增强模型能力的各个方面。 AI

排序理由 文章讨论了用于AI模型微调的合成数据生成的研究论文和技术。

在 Eugene Yan 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
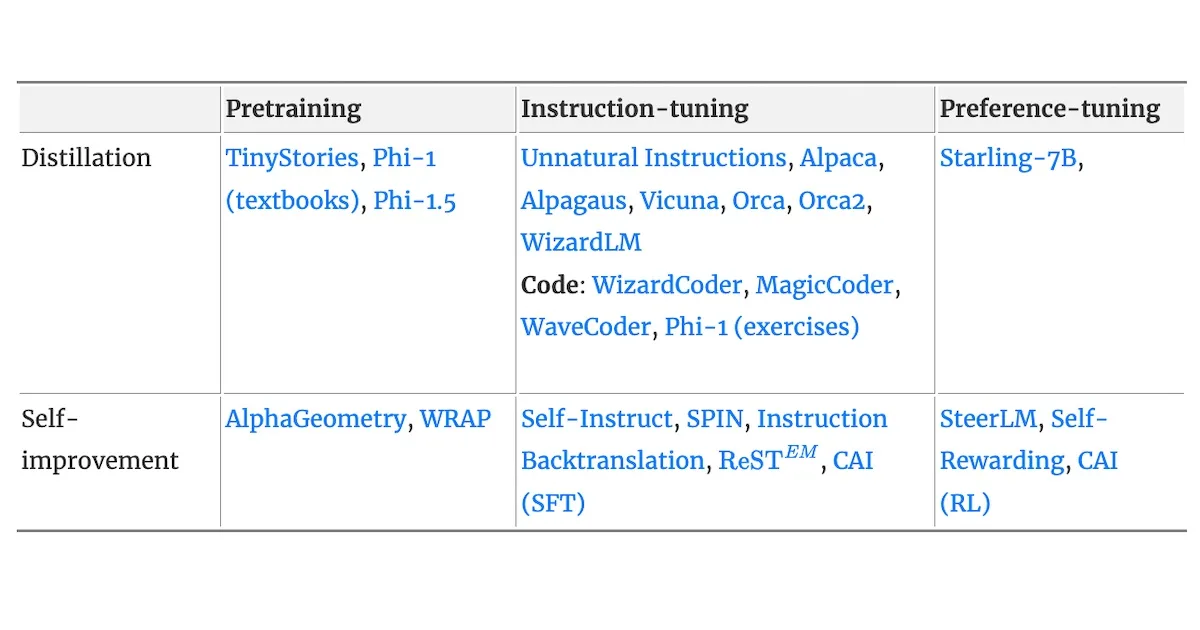
AI模型现在可以使用合成数据进行微调,降低成本和隐私风险

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
文章讨论了用于AI模型微调的合成数据生成的研究论文和技术。
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, model release
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
968 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Eugene Yan TIER_1 English(EN) ·

    如何生成和使用合成数据进行微调

    Overcoming the bottleneck of human annotations in instruction-tuning, preference-tuning, and pretraining.