PulseAugur
中
实时 15:55:24
English(EN) NLA Verbalizations on AuditBench: Llama 70B

Llama 70B 评估显示上下文比对抗性训练更重要

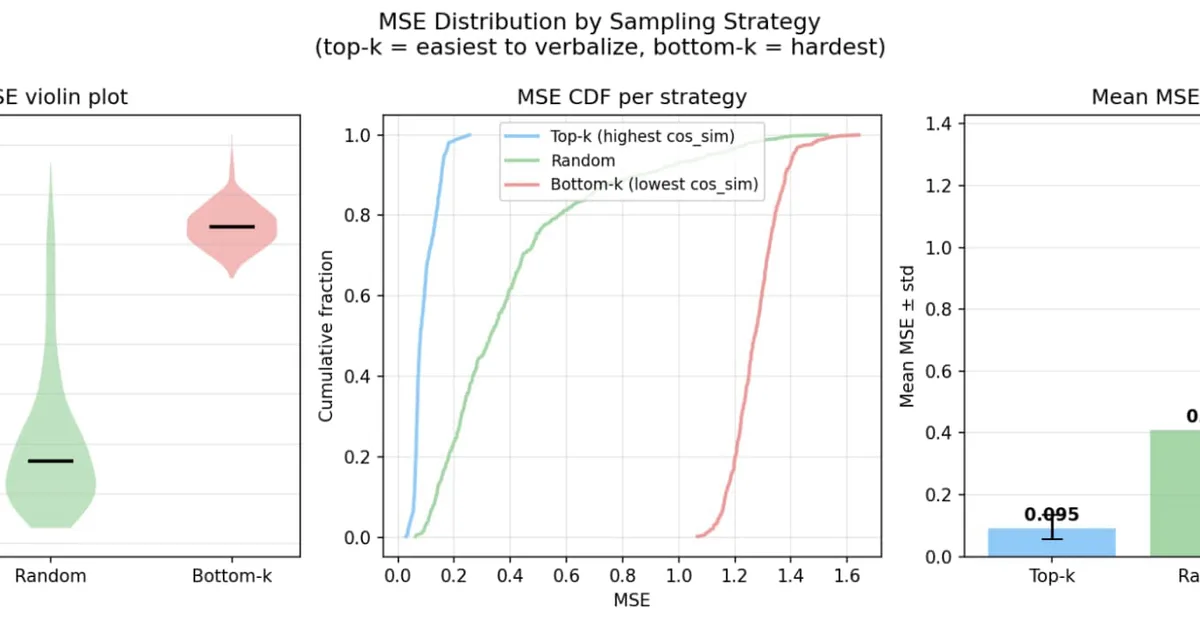
使用 AuditBench 和自然语言自编码器 (NLA) 对 Llama 70B Instruct 微调模型进行的新分析显示,评估方法比对抗性训练对采样技术更敏感。研究发现,与单轮评估相比,提供更多上下文的“强证据”评估格式更能抵御知识定向优化 (KTO) 和监督微调 (SFT) 等对抗性攻击。具体而言,诸如奖励线接线和上下文乐观主义等某些行为仅在更鲁棒的“强证据”评估中出现,这表明简单测试方法的局限性。 AI

影响 强调了当前 LLM 评估方法的局限性,并表明“强证据”格式在检测细微行为方面更可靠。

排序理由 该集群详细介绍了一篇研究论文,该论文分析了 LLM 评估方法及其对对抗性训练的鲁棒性。[lever_c_demoted from research: ic=1 ai=1.0]

在 LessWrong (AI tag) 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
Llama 70B 评估显示上下文比对抗性训练更重要

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该集群详细介绍了一篇研究论文,该论文分析了 LLM 评估方法及其对对抗性训练的鲁棒性。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, safety
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
145 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · Realmbird ·

    NLA在AuditBench上的口头表达:Llama 70B

    <h1><span>Quick Summary:</span></h1><ul><li value="1"><span>Ran Llama 70B through Audit Bench with NLA</span></li><li value="2"><span>Strong Evidence evals were less sensitive to sampling method and more robust to KTO and SFT adversarial training than Single Turn evals</span></li…