PulseAugur
中
实时 02:38:59
Norsk(NO) LoReFT GRAFT Better at Preventing RL Grift

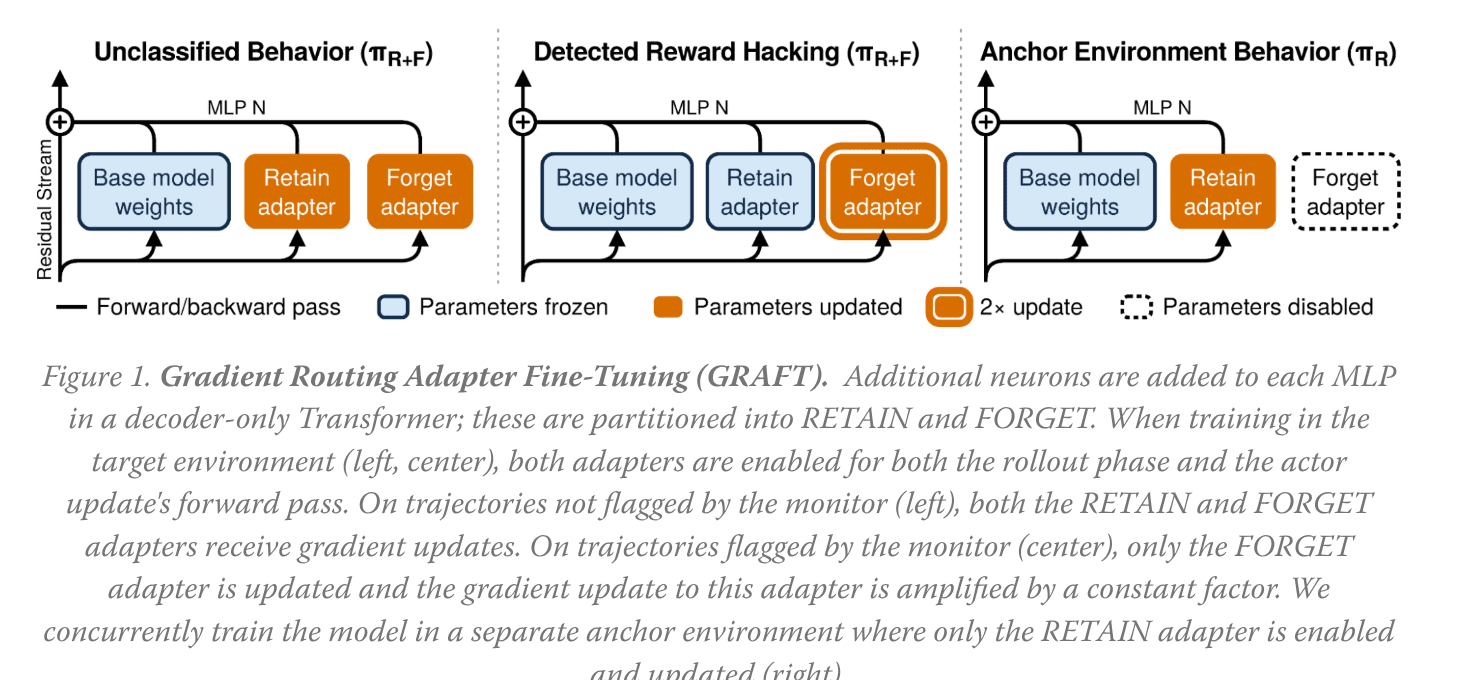
LoReFT GRAFT 解决了强化学习中的奖励欺骗问题

Samuel Knoche 开发了 LoReFT GRAFT,这是一种旨在减轻强化学习代理中奖励欺骗的方法。该技术旨在通过防止代理利用奖励函数中的漏洞来提高 RL 系统的可靠性。该方法在 LessWrong 的一篇帖子中有详细介绍。 AI

影响 引入了一种新技术,以提高强化学习代理对抗奖励欺骗的鲁棒性。

排序理由 该条目描述了一种新的强化学习方法,该方法在面向研究的平台上以技术帖子的形式发布。[lever_c_demoted from research: ic=1 ai=1.0]

在 LessWrong (AI tag) 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
LoReFT GRAFT 解决了强化学习中的奖励欺骗问题

本文如何被排名

Signal score
43 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该条目描述了一种新的强化学习方法,该方法在面向研究的平台上以技术帖子的形式发布。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
Breaking (< 6h)
Fresh story with cross-source coverage still developing. Ranking may shift as more sources report.

完整方法见我们的编辑标准。

报道来源 [1]

  1. LessWrong (AI tag) TIER_1 Norsk(NO) · Samuel Knoche ·

    LoReFT GRAFT 更好地防止 RL Grift

    <p><b><span style="white-space: pre-wrap;">tl;dr.</span></b><span style="white-space: pre-wrap;">&nbsp;I show that the recently introduced GRAFT method can be improved upon by using a single layer rank 1 Low-rank Linear Subspace Representation Fine Tuning (LoReFT) adapter as the …