PulseAugur
中
实时 12:43:37
Italiano(IT) 🧠 LPT, di Cornell e IBM Research, condivide la KV cache tra ricorsioni: il primo passaggio costruisce la memoria, i successivi affinano la previsione. Nei test

康奈尔大学和 IBM Research 在递归之间共享 KV 缓存

来自康奈尔大学和 IBM Research 的研究人员开发了一种在语言模型的递归调用之间共享 KV 缓存的方法。该技术允许初始递归步骤建立记忆,后续步骤在此基础上进行优化以提高预测能力。该方法已通过测试并显示出增强模型性能的潜力。 AI

影响 这项技术可能带来更高效、更具潜力的递归语言模型。

排序理由 该条目描述了一篇技术研究论文,详细介绍了一种新的语言模型推理方法。[lever_c_demoted from research: ic=1 ai=1.0]

在 Mastodon — mastodon.social 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
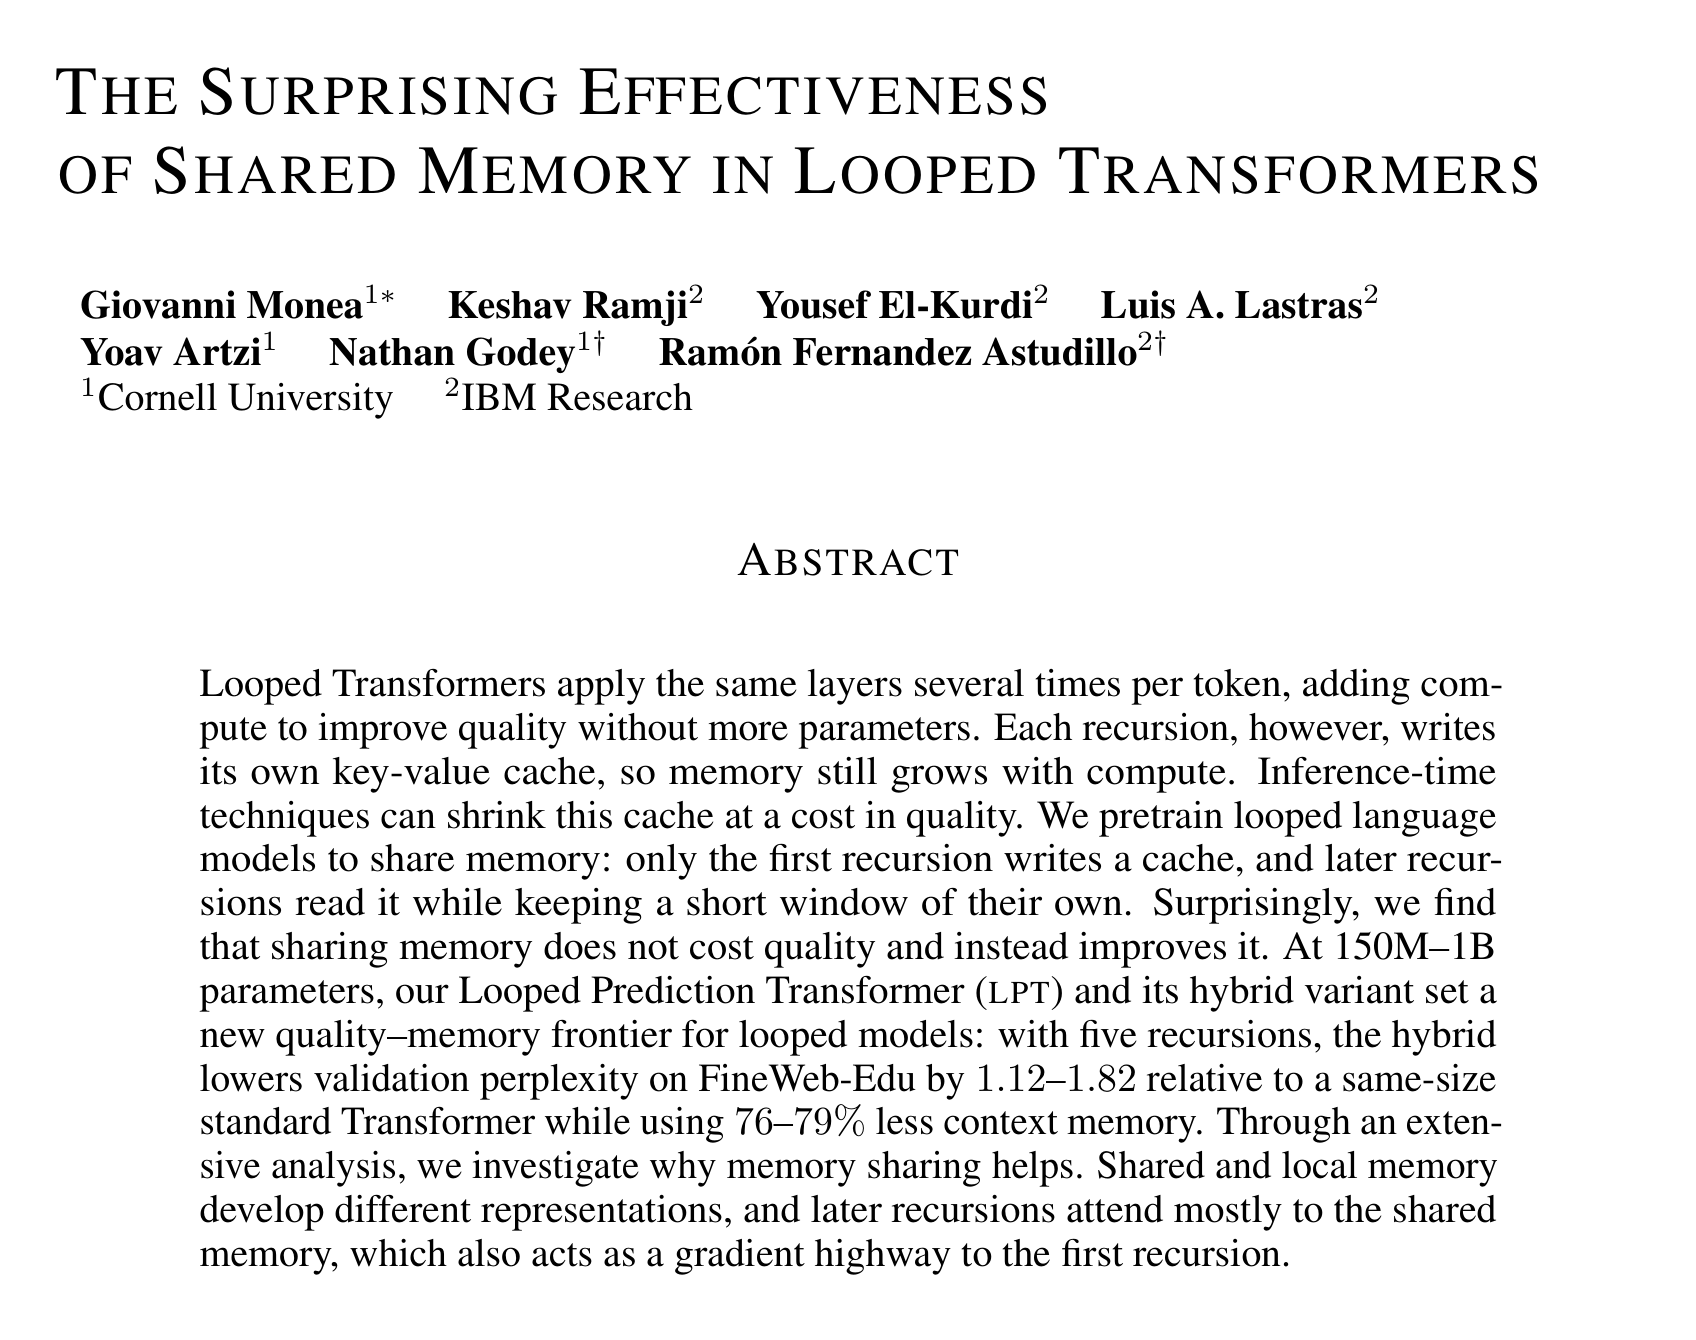
康奈尔大学和 IBM Research 在递归之间共享 KV 缓存

本文如何被排名

Signal score
10 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该条目描述了一篇技术研究论文,详细介绍了一种新的语言模型推理方法。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
Breaking (< 6h)
Fresh story with cross-source coverage still developing. Ranking may shift as more sources report.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Mastodon — mastodon.social TIER_1 Italiano(IT) · [email protected] ·

    🧠 LPT,来自康奈尔大学和 IBM Research,在递归之间共享 KV 缓存:首次传递建立记忆,后续传递优化预测。在测试中

    🧠 LPT, di Cornell e IBM Research, condivide la KV cache tra ricorsioni: il primo passaggio costruisce la memoria, i successivi affinano la previsione. Nei test migliora qualità ed efficienza della memoria. 👉 I dettagli: https:// lnkd.in/p/dpPHFa6R ___ ✉️ 𝗦𝗲 𝘃𝘂𝗼𝗶 𝗿𝗶𝗺𝗮𝗻𝗲𝗿𝗲 𝗮𝗴𝗴𝗶𝗼𝗿𝗻𝗮…