PulseAugur
中
实时 14:05:08
English(EN) The article explains how to cut coding agent costs by 90 percent by using secure LLM serving with Ray and vLLM on Anyscale. Source: Anyscale https:// anyscale.c

Anyscale 详解通过自托管 LLM 将编码代理成本降低 90%

Anyscale 发布了一份指南,详细介绍了如何将运行编码代理的相关成本大幅降低高达 90%。该方法涉及使用其平台自托管大型语言模型 (LLM),该平台集成了 Ray Serve 和 vLLM,而不是依赖按 token 收费的 API 定价。这种方法不仅能节省大量成本,还能提供增强的数据隐私和性能改进,例如更快的编译时间和更高的请求吞吐量。 AI

影响 使组织能够显著降低 AI 驱动的编码代理的运营成本,并获得对数据隐私的更大控制权。

排序理由 该文章提供了优化 LLM 服务基础设施的指南和技术细节,这是一个面向工具的主题,而不是核心模型发布或研究突破。

在 Mastodon — mastodon.social 阅读 →

AI 生成摘要 · Google Gemini · 来自 2 个来源。 我们如何撰写摘要 →
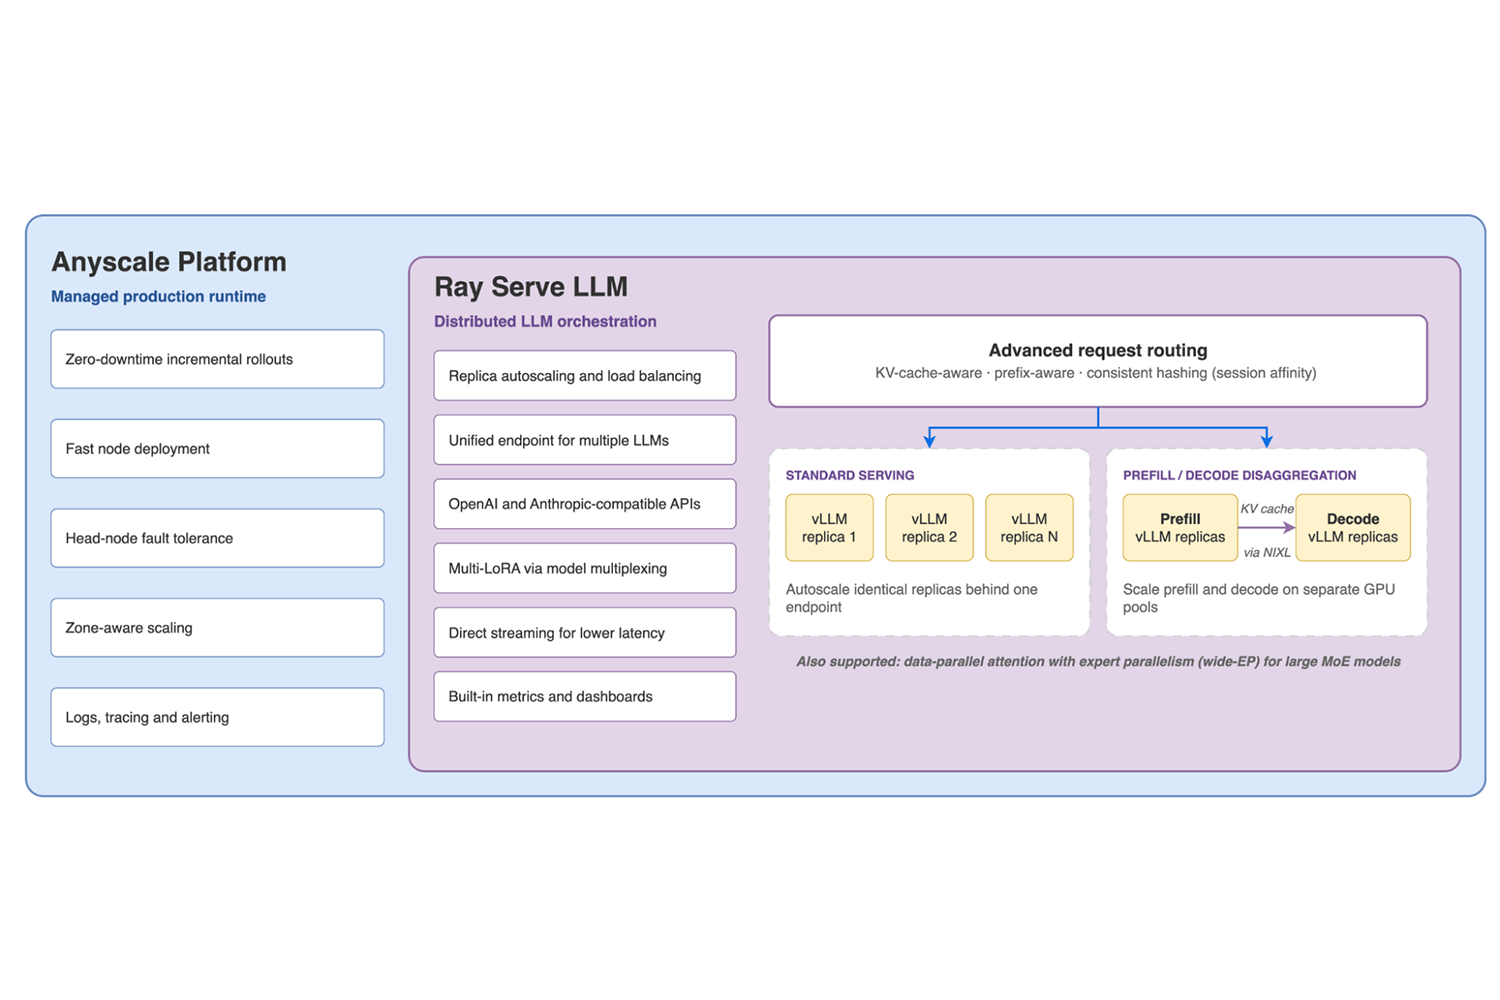
Anyscale 详解通过自托管 LLM 将编码代理成本降低 90%

本文如何被排名

Signal score
1 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该文章提供了优化 LLM 服务基础设施的指南和技术细节,这是一个面向工具的主题,而不是核心模型发布或研究突破。
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
1 days old
Coverage has settled into its steady-state source set.

完整方法见我们的编辑标准。

报道来源 [2]

  1. Anyscale blog TIER_1 English(EN) ·

    将编码代理成本降低 90%:使用 Anyscale 上的 Ray + vLLM 安全地提供 LLM 服务

    Serve coding agents on your own GPUs. A guide to Ray Serve and vLLM on Anyscale, from engine tuning to cache-aware routing, with measured results.

  2. Mastodon — mastodon.social TIER_1 English(EN) · sipirtu ·

    文章介绍如何通过在 Anyscale 上使用 Ray 和 vLLM 进行安全 LLM 服务,将编码代理成本降低 90%。来源:Anyscale https:// anyscale.c

    The article explains how to cut coding agent costs by 90 percent by using secure LLM serving with Ray and vLLM on Anyscale. Source: Anyscale https:// anyscale.com/blog/run-coding-a gents-on-your-own-gpus # AI