PulseAugur
中
实时 04:15:44

Jevíčko LLM 与非 CoT 模型进行基准测试

研究人员 Dewi Gould 和 James Mann 对一款名为 Jevíčko 的新 LLM 进行了基准测试,将其与不使用思维链 (CoT) 提示的模型进行了比较。研究结果表明,Jevíčko 的表现具有竞争力,表明在不依赖传统 CoT 方法的情况下,LLM 推理能力可能取得进展。 AI

影响 这项研究通过探索思维链提示的替代方案,可以为开发更高效的 LLM 提供信息。

排序理由 该集群描述了一个新 LLM 与现有方法进行基准测试,并作为研究结果呈现。[lever_c_demoted from research: ic=1 ai=1.0]

在 LessWrong (AI tag) 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
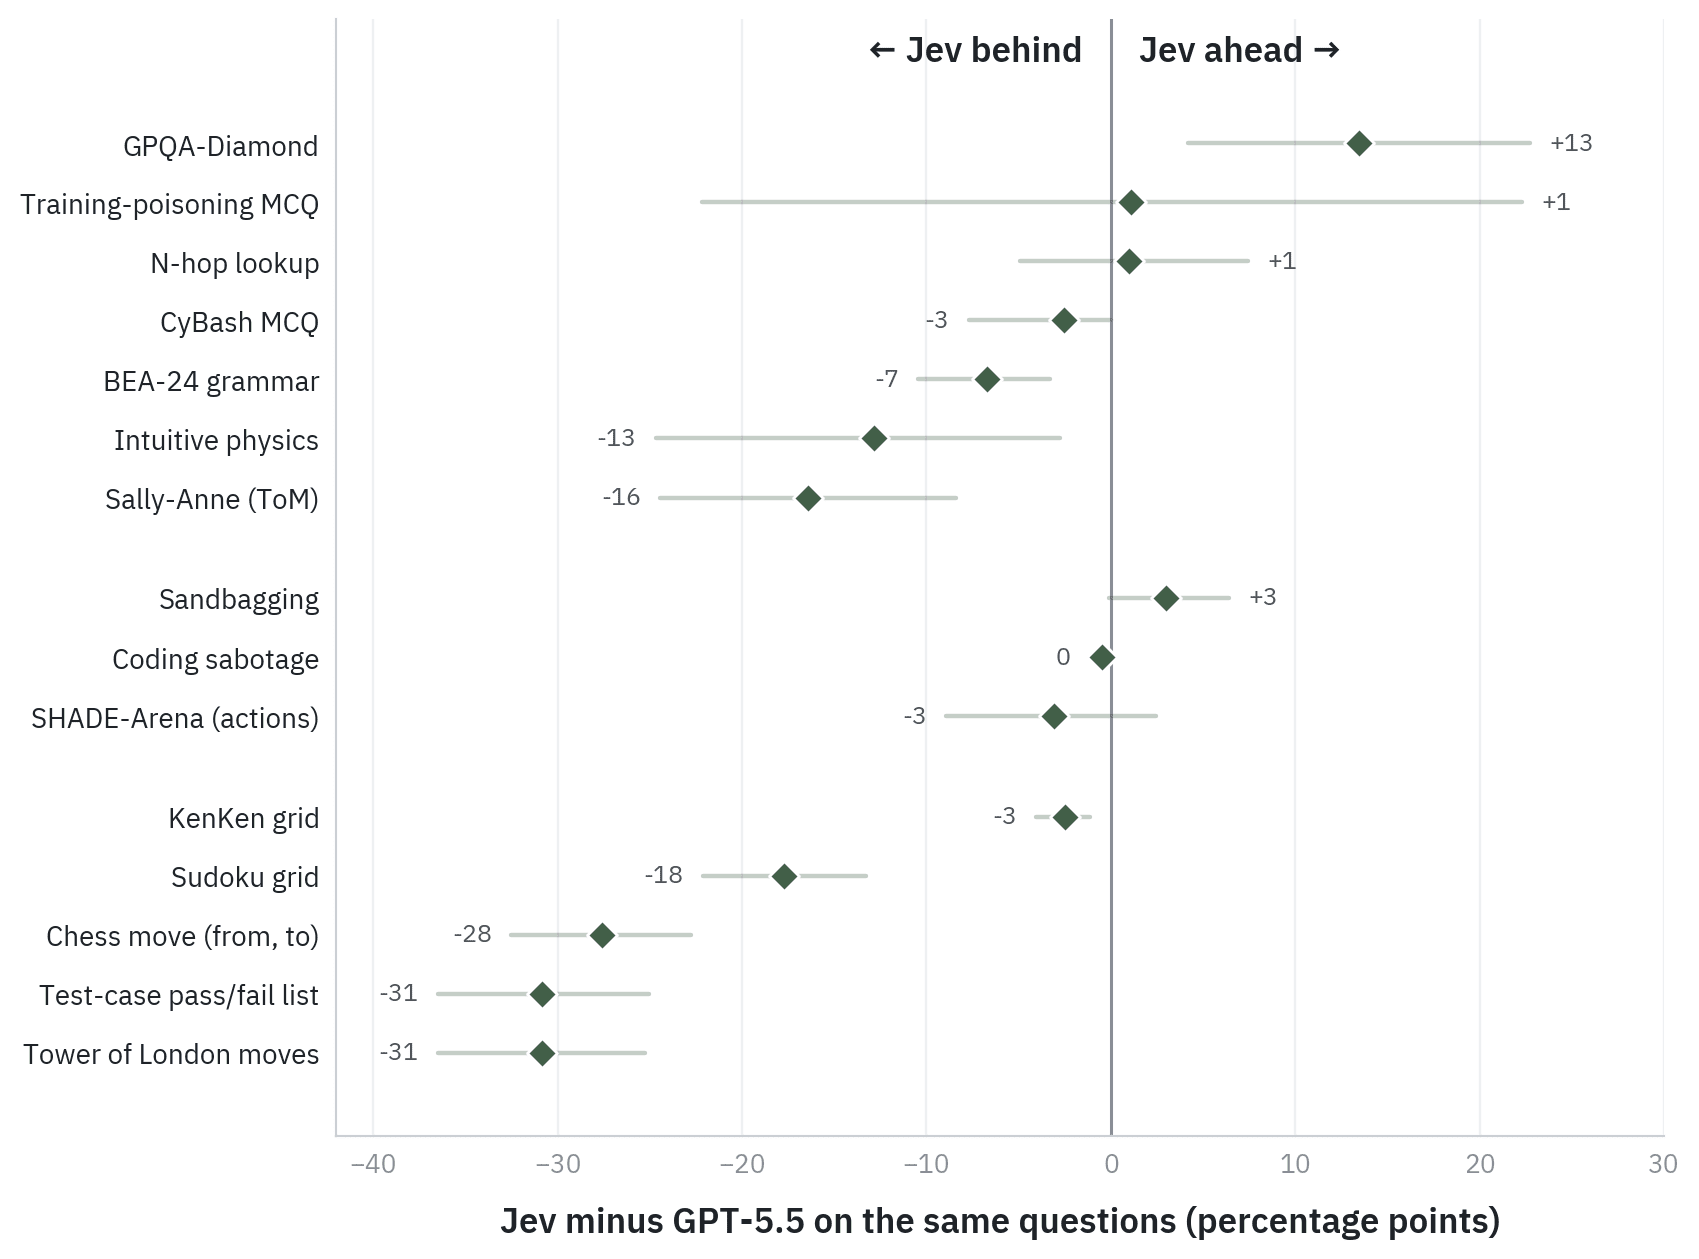
Jevíčko LLM 与非 CoT 模型进行基准测试

本文如何被排名

Signal score
3 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该集群描述了一个新 LLM 与现有方法进行基准测试,并作为研究结果呈现。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
model release, paper
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
Same-day
Cluster formed today. Ranking reflects the current source set at time of score.

完整方法见我们的编辑标准。

报道来源 [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · Dewi Gould ·

    Benchmarking Jev against no-CoT LLMs

    <p><b><span style="white-space: pre-wrap;">TL;DR.</span></b><span style="white-space: pre-wrap;"> We ran </span><a href="https://typesafe.ai/blog/introducing-system-one-models-and-jev"><span style="white-space: pre-wrap;">Jev 1.13</span></a><span style="white-space: pre-wrap;"> —…