PulseAugur
中
实时 20:18:13
Italiano(IT) Ho provato Strata con il modello Coder su una RTX 3060 da 12 GB: circa 30 token al secondo, contesto ampio e una cache efficace. Una prima esperienza con OpenCo

Strata 项目可在消费级 GPU 上运行大型本地 LLM

Strata 项目可在包括 12GB 显存的 GPU 在内的消费级硬件上本地运行 Qwen3.8-Flash-Next 等大型语言模型。它通过将模型的负载分配到 GPU、CPU、RAM 和 SSD,并利用专家混合(Mixture of Experts)架构,仅激活每个 token 所需的组件来实现。在 RTX 3060 上的初步测试显示,生成速度约为每秒 30 个 token,缓存利用率高,使其成为本地编码任务的可行选项。 AI

影响 使得大型模型能在消费级硬件上本地运行,可能减少对云端推理进行编码任务的依赖。

排序理由 文章描述了一个可在消费级硬件上运行现有 LLM 的项目,而非新的模型发布或重大的行业转变。

在 Mastodon — mastodon.social 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
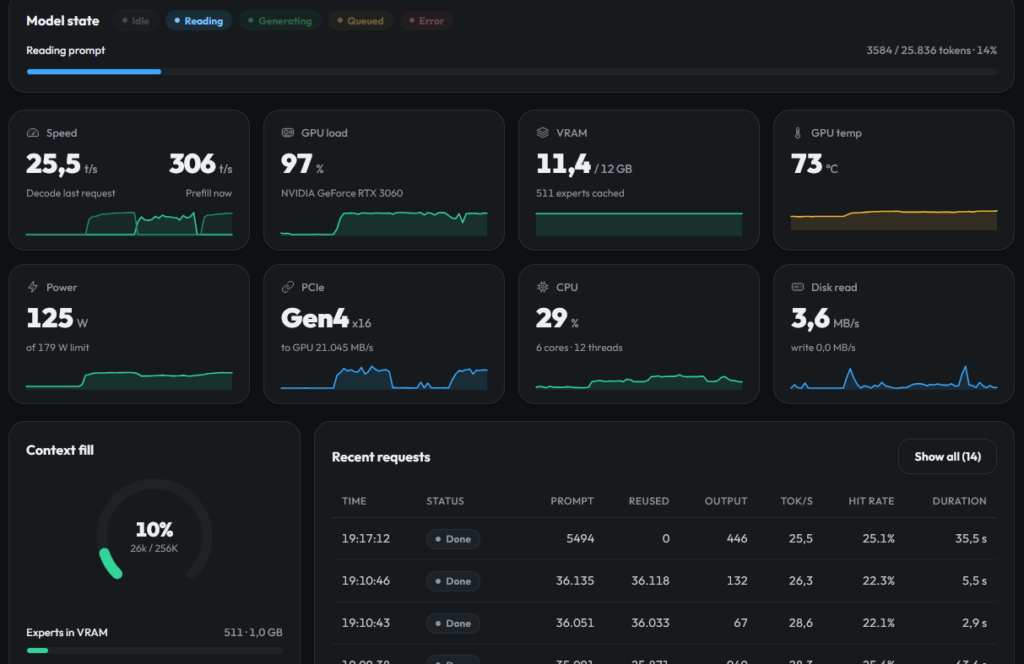
Strata 项目可在消费级 GPU 上运行大型本地 LLM

本文如何被排名

Signal score
9 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
文章描述了一个可在消费级硬件上运行现有 LLM 的项目,而非新的模型发布或重大的行业转变。
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, model release
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
Breaking (< 6h)
Fresh story with cross-source coverage still developing. Ranking may shift as more sources report.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Mastodon — mastodon.social TIER_1 Italiano(IT) · [email protected] ·

    我在 12GB RTX 3060 上试用了带 Coder 模型的 Strata:每秒约 30 个 token,大上下文和有效缓存。OpenCo 的初体验

    Ho provato Strata con il modello Coder su una RTX 3060 da 12 GB: circa 30 token al secondo, contesto ampio e una cache efficace. Una prima esperienza con OpenCode che, pur con qualche compromesso nella qualità, rende il coding locale molto più convincente. #ai #AILocale #llm #Ope…