PulseAugur
中
实时 18:38:32
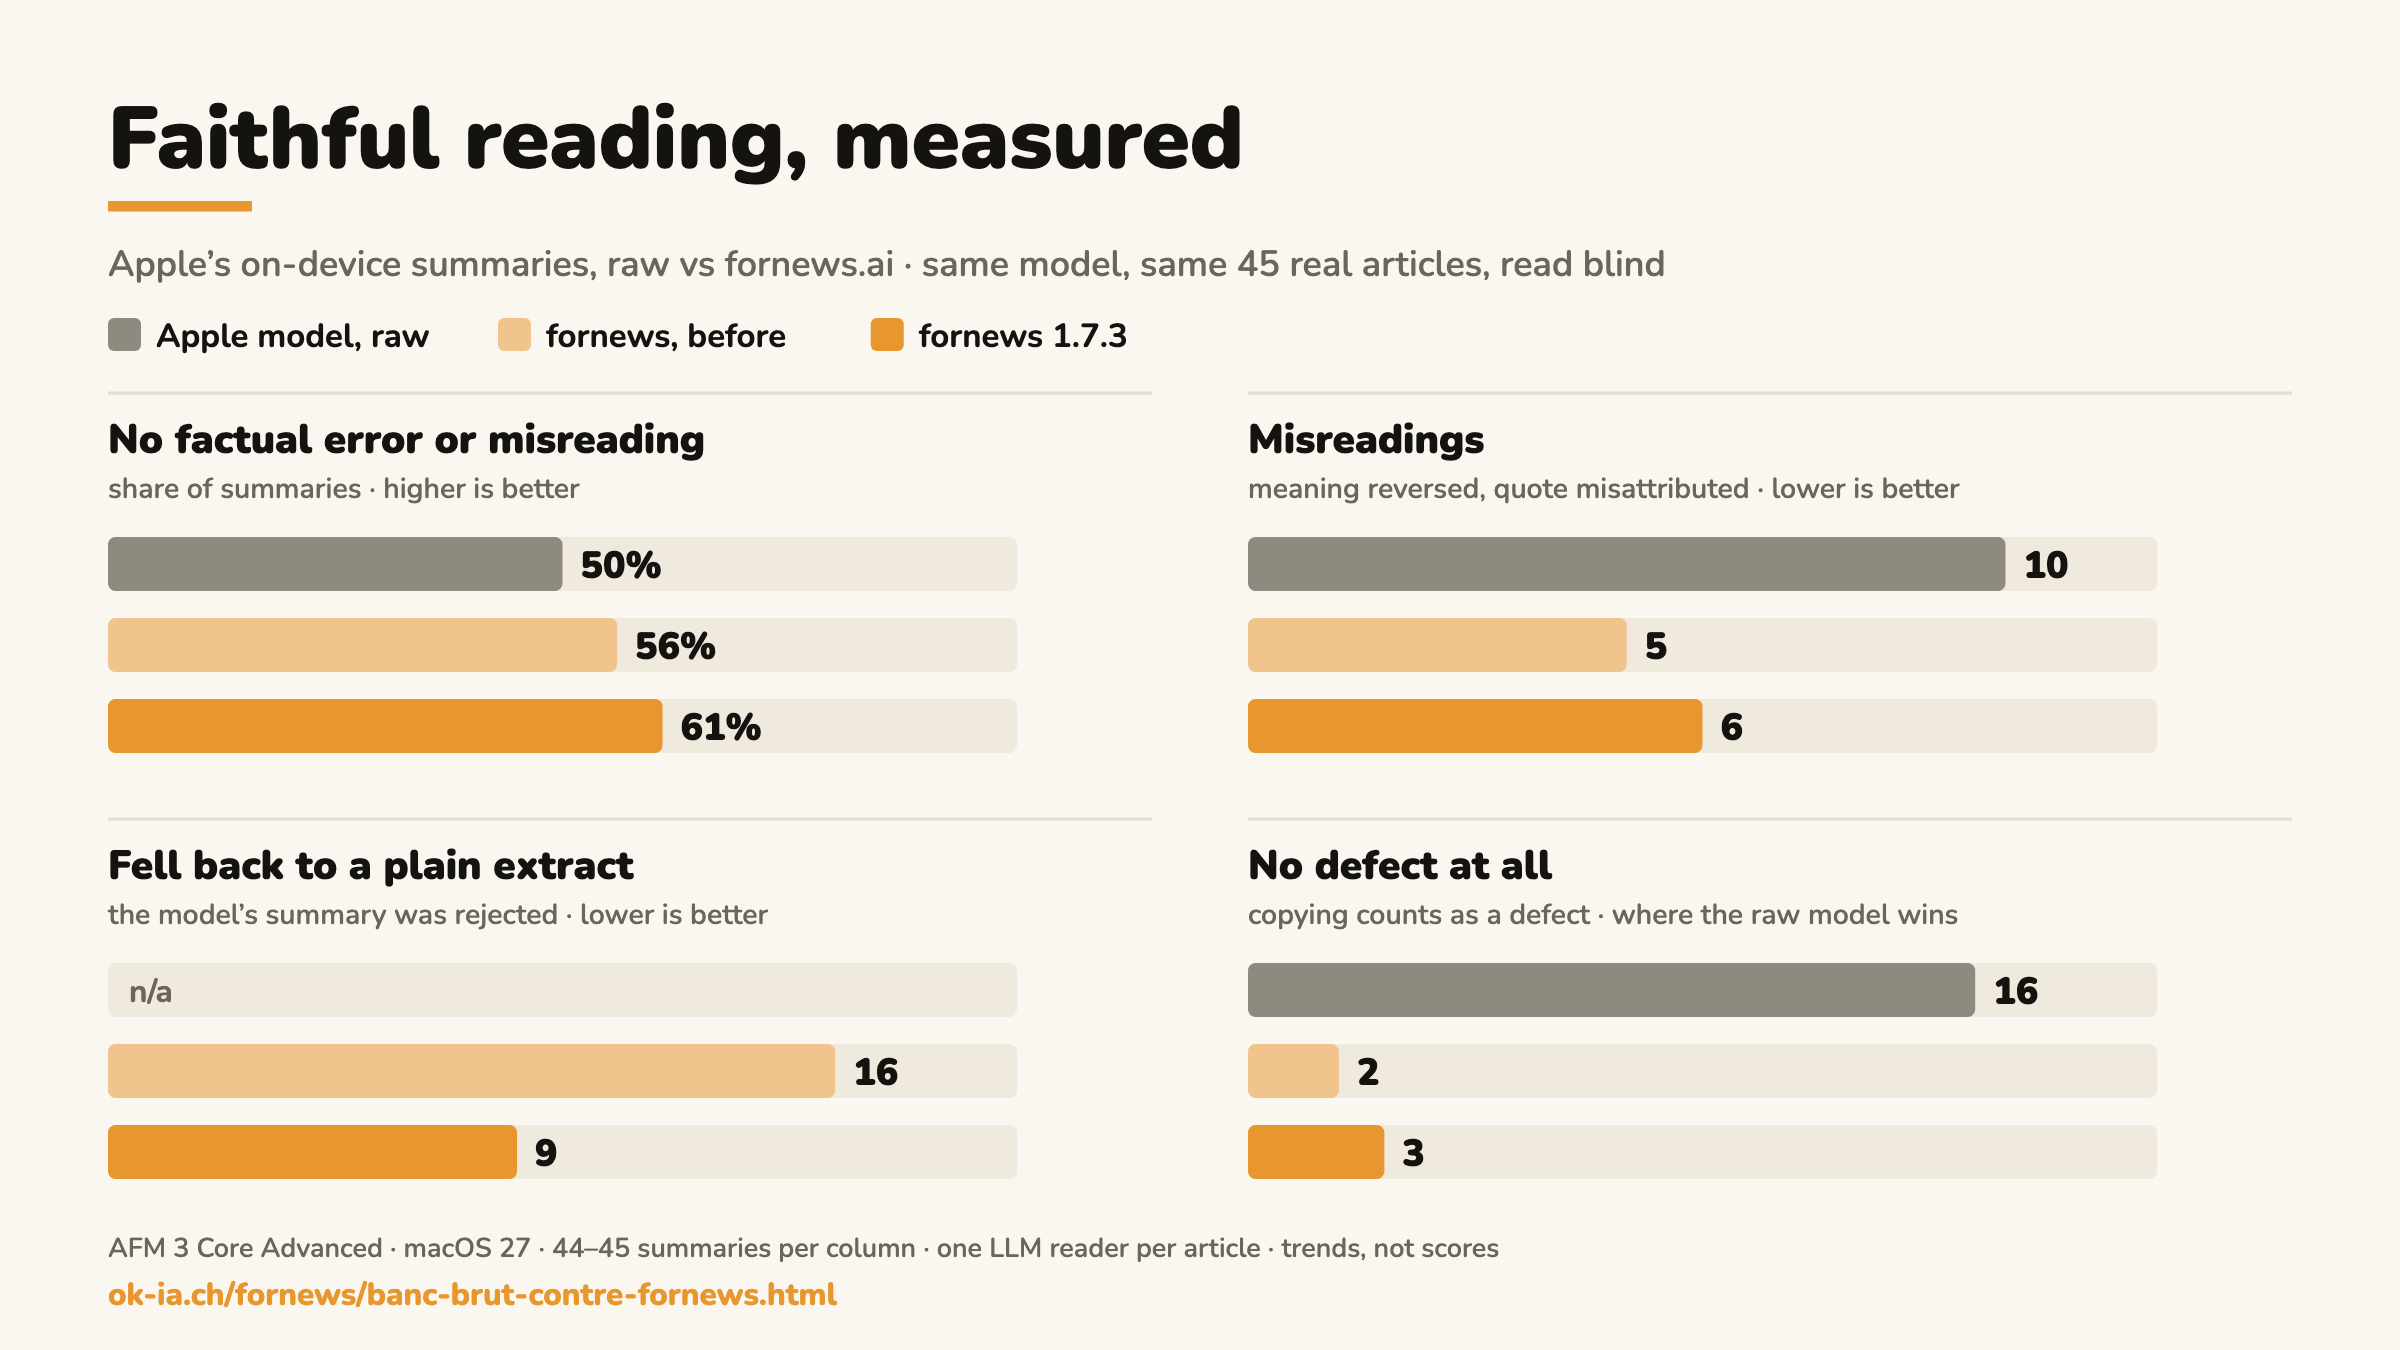
English(EN) Faithful reading, measured 📏 How reliable are on-device AI news summaries? We benchmarked fornews.ai against Apple's model used raw: same model, 45 real article

AI新闻摘要基准测试显示 fornews.ai 优于 Apple 模型

一项新的基准研究评估了设备端AI新闻摘要的可靠性,将 fornews.ai 工具与 Apple 的集成模型进行了比较。在五种语言的45篇真实文章中,fornews.ai 工具表现更优,事实错误更少,无缺陷摘要的百分比更高。研究指出,改写摘要会使误读率加倍,因此决定保留直接文章复制。 AI

影响 凸显了设备端AI摘要质量的潜在差异,影响用户体验和对AI生成内容的信任度。

排序理由 该条目描述了两个AI摘要工具的基准比较,评估了它们在新闻文章上的表现。

在 Mastodon — mastodon.social 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
AI新闻摘要基准测试显示 fornews.ai 优于 Apple 模型

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该条目描述了两个AI摘要工具的基准比较,评估了它们在新闻文章上的表现。
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
product, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
1 days old
Coverage has settled into its steady-state source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Mastodon — mastodon.social TIER_1 English(EN) · [email protected] ·

    忠实阅读,审慎衡量 📏 设备端AI新闻摘要的可靠性如何?我们对fornews.ai进行了基准测试,并使用了Apple的原始模型:同一模型,45篇真实文章

    Faithful reading, measured 📏 How reliable are on-device AI news summaries? We benchmarked fornews.ai against Apple's model used raw: same model, 45 real articles in 5 languages, read blind. ✅ Fewer misreadings: 6 vs 10 ✅ 61% of summaries with no factual error (raw: 50%) ❌ Fewer d…