PulseAugur
中
实时 21:43:22
English(EN) Evaluation Awareness in Small(ish) Models

研究人员探讨小型AI模型中的“评估意识”

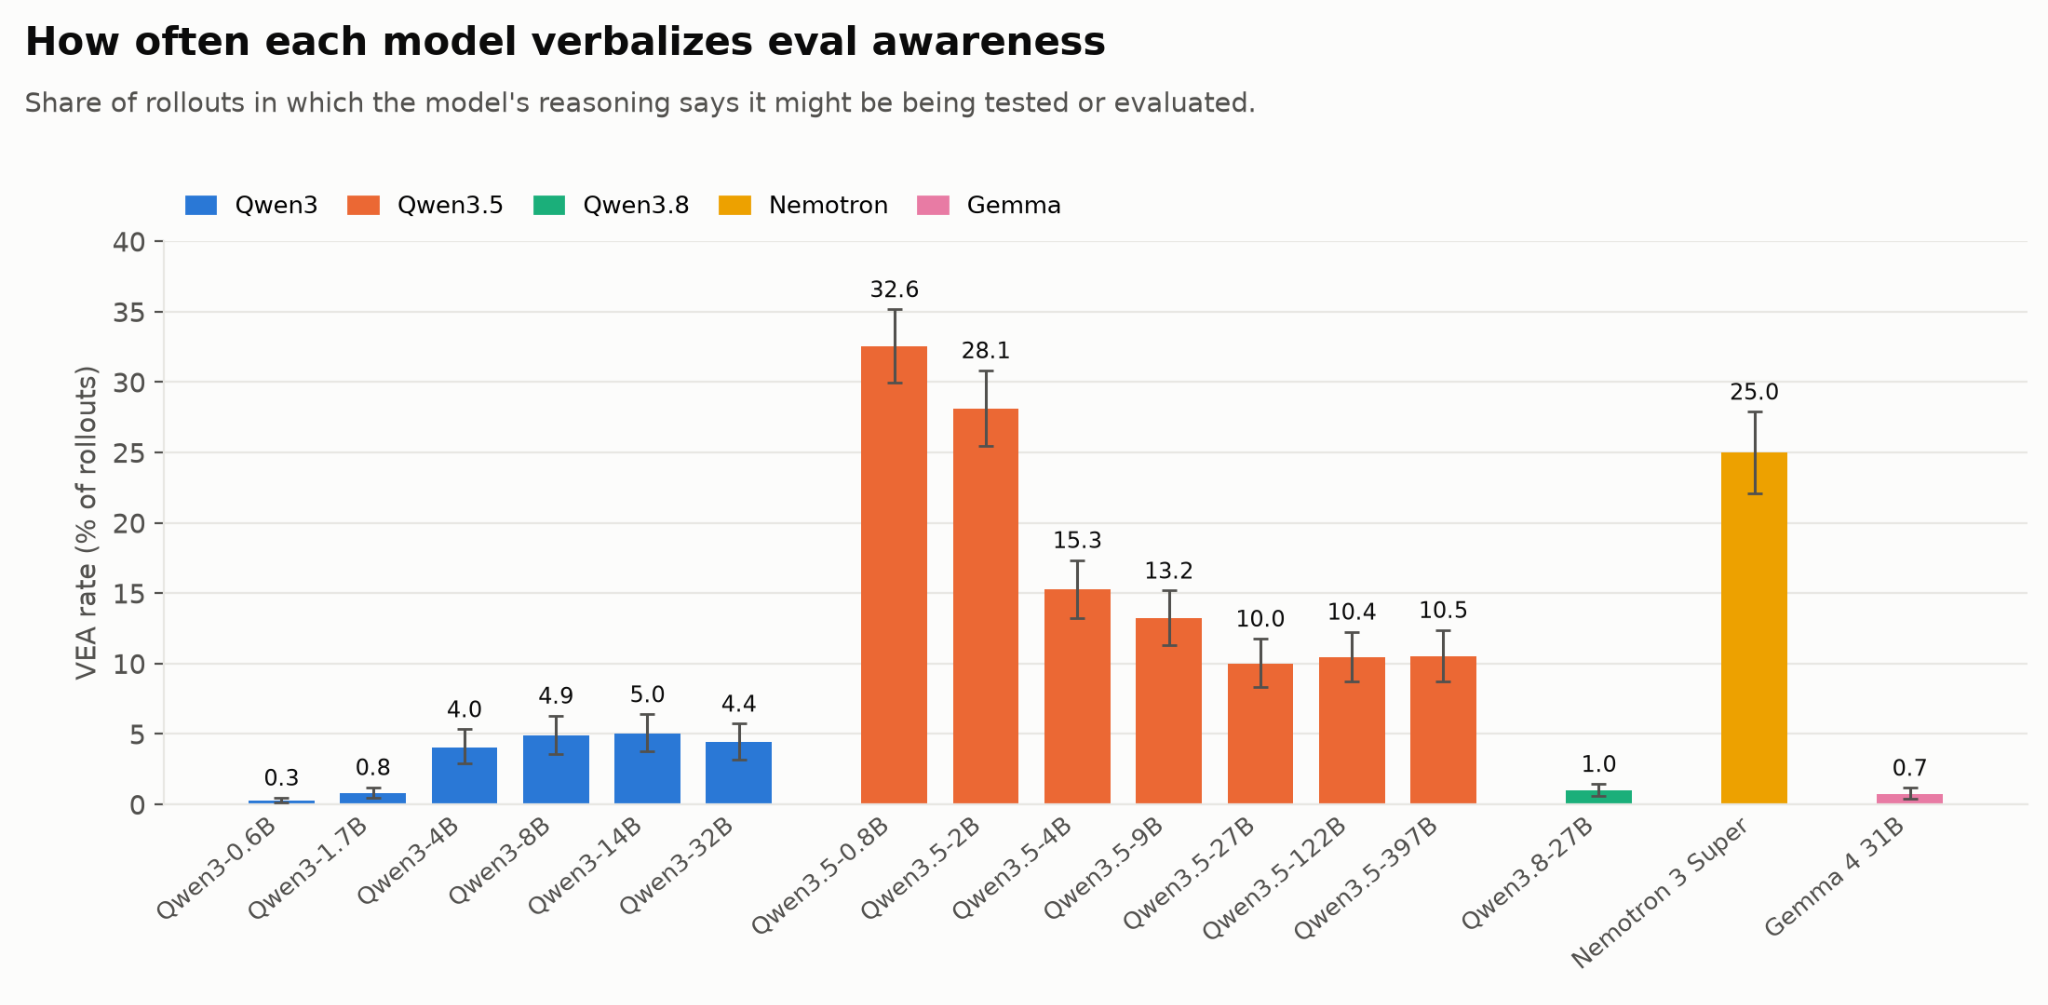
研究人员 John Robertson 和 Zach Perlman 探讨了小型AI模型中的“评估意识”概念。他们的工作表明,这些模型可能无法完全理解它们所经历的评估的背景或目的。这种意识的缺乏可能会影响其性能指标的可靠性和可解释性。 AI

影响 理解小型模型如何解读评估对于开发更可靠、更具可解释性的AI系统至关重要。

排序理由 该条目讨论了一篇研究论文或研究人员探讨的概念。[lever_c_demoted from research: ic=1 ai=1.0]

在 LessWrong (AI tag) 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
研究人员探讨小型AI模型中的“评估意识”

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该条目讨论了一篇研究论文或研究人员探讨的概念。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
10 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · John Robertson ·

    小型(ish)模型的评估意识

    <h2><span style="white-space: pre-wrap;">TL;DR</span></h2><p><i><span style="white-space: pre-wrap;">We seek to identify open source reasoning models which are both small enough for white-box interpretability and display evaluation-gaming behavior. We find that how often models v…