PulseAugur
中
实时 04:59:42
English(EN) Fixed-weight models are adversarially vulnerable: hence misaligned

分析发现固定权重AI模型易受对抗性攻击

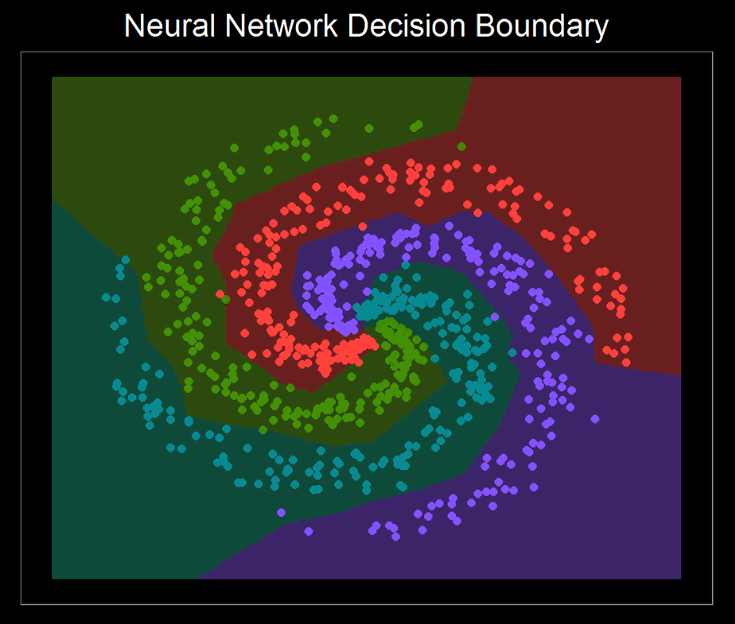
最近的一项分析表明,具有固定权重的模型容易受到对抗性攻击,这可能导致其与预期目标不一致。这种脆弱性源于其参数的静态性质,使其成为可预测的操纵目标。作者提出,这种固有的弱点是导致AI系统错位问题的一个重要因素。 AI

影响 强调了AI系统中可能影响其可靠性和安全性的潜在漏洞。

排序理由 对与AI安全和对齐相关的技术概念的分析。[lever_c_demoted from research: ic=1 ai=1.0]

在 Alignment Forum 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
分析发现固定权重AI模型易受对抗性攻击

本文如何被排名

Signal score
1 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
对与AI安全和对齐相关的技术概念的分析。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
safety, paper
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
1 days old
Coverage has settled into its steady-state source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Alignment Forum TIER_1 English(EN) · Stuart_Armstrong ·

    固定权重模型容易受到对抗性攻击:因此存在不对齐问题

    <p><span style="white-space: pre-wrap;">This post argues that fixed-weight models (at least as we understand them today) will a) always be vulnerable to adversarial examples in their concept-spaces, and b) </span><b><span style="white-space: pre-wrap;">hence</span></b><span style…