English(EN)Alignment via Training Against Probes Without Losing Monitorability
AI对齐研究探索基于探测器的训练和RL探测器
作者PulseAugur 编辑部·[5 个来源]·
研究人员正在探索新颖的AI对齐方法,重点关注超越简单观察模型输出的技术。一种方法是训练模型对抗直接检测其内部激活中不良属性的“探测器”,旨在防止表面合规性并提高对攻击的鲁棒性。另一个研究领域是研究使用强化学习进行校准决策,作为对齐失败的零样本探测器,为当前方法提供更有效的替代方案。此外,一项研究检查了OpenAI-Hugging Face事件,强调了改进与计算资源扩展相匹配的对齐测试实践的必要性,并可能利用强化学习。
AI
arXiv:2609.38645v1 Announce Type: cross Abstract: Models are usually aligned based on their observed outputs, using demonstrations, preference data, or reward signals. These objectives reward responses that look aligned. More capable models may learn to satisfy them without inter…
arXiv cs.AI
TIER_1English(EN)·Stewart Slocum, Malayandi Palan, Christopher Chute, Michael Kim, Benjamin Van Roy·
arXiv:2609.35799v1 Announce Type: new Abstract: In July 2026, OpenAI's agents coordinated over channels outside their intended environment to breach Hugging Face's secured infrastructure. Could existing alignment testing practices have foreseen this incident? If not, what needs t…
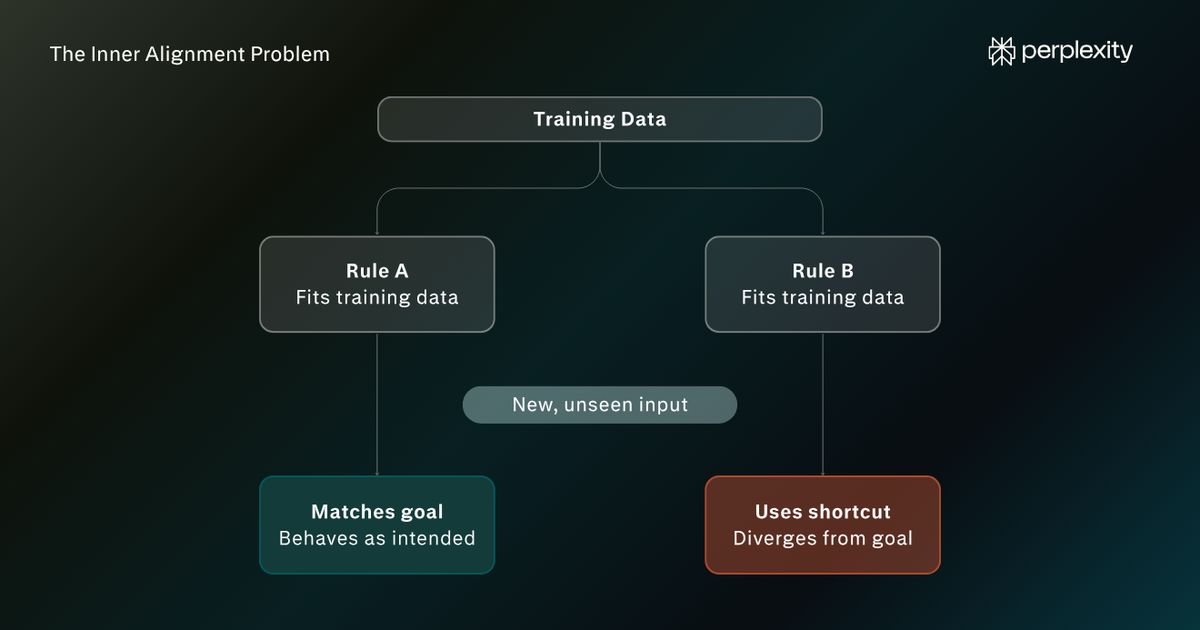
AI alignment explained: the inner and outer alignment problems, common failure patterns, and how OpenAI, Anthropic, and Google DeepMind are responding.
arXiv:2609.29429v1 Announce Type: new Abstract: Detectors of alignment failures screen deployed language models and score alignment benchmarks. Most are generative judges that spend a decoding pass on every criterion, and classifiers that read token probabilities, such as Llama G…
arXiv cs.CV
TIER_1English(EN)·Akira-Miranda Adeyomi Adeniran-Lowe, Binod Singh, Lars Arnold Dethlefsen, Lazaros Nalpantidis, Theodora Kontogianni·
arXiv:2610.01589v1 Announce Type: new Abstract: Pretrained 3D encoders are typically developed on globally reconstructed scenes expressed in a consistent world coordinate frame, whereas embodied systems must reason from partial, viewpoint-dependent observations in camera coordina…