PulseAugur
中
实时 03:53:13
English(EN) AI Memory Down From 42GB to 7GB. Here’s What Google’s TurboQuant Actually Did.

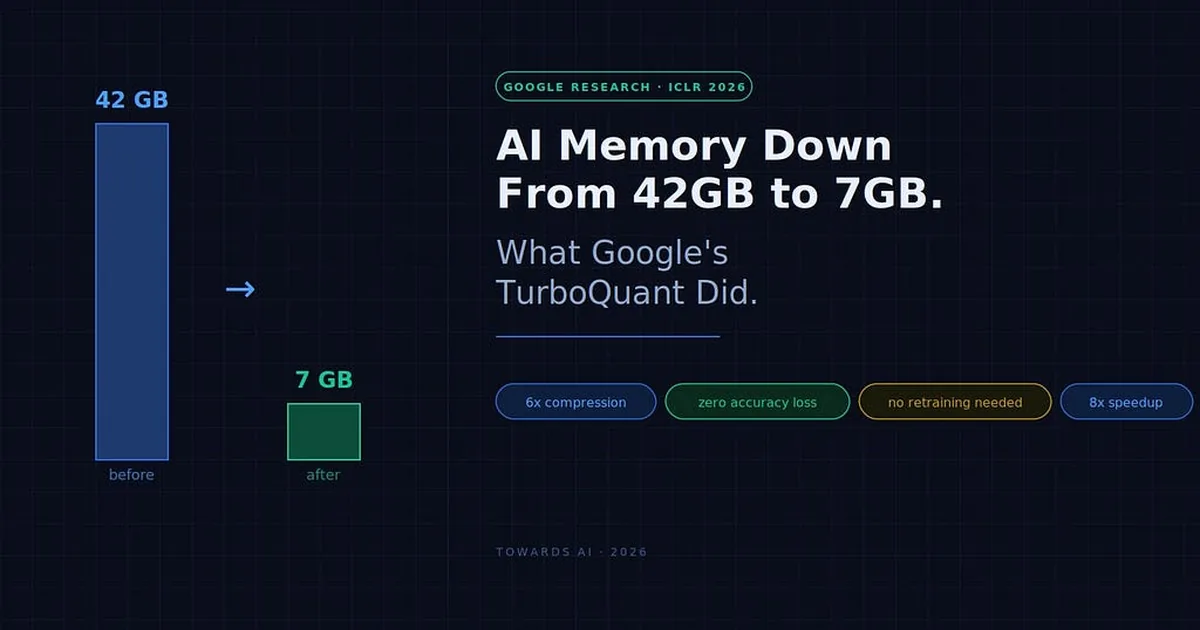
Google 的 TurboQuant 将 LLM 内存使用量减少 6 倍,准确率无损

Google 研究人员开发了一种名为 TurboQuant 的新技术,可显著减少大型语言模型所需的内存。通过采用数据旋转和标量量化的两步流程,TurboQuant 将 KV 缓存压缩至每值 3 位,比标准的 16 位减少了 6 倍,且准确率没有任何损失。这一进步对于自托管 LLM 至关重要,因为 KV 缓存是长上下文窗口的主要成本驱动因素,而 TurboQuant 有望降低基础设施支出并提高性能。 AI

影响 降低 LLM 内存占用,可能降低托管成本并为应用程序启用更长的上下文窗口。

排序理由 在会议上发表的关于 LLM 内存压缩新算法的论文。[lever_c_demoted from research: ic=1 ai=1.0]

在 Towards AI 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
Google 的 TurboQuant 将 LLM 内存使用量减少 6 倍,准确率无损

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
在会议上发表的关于 LLM 内存压缩新算法的论文。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, paper
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
156 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Towards AI TIER_1 English(EN) · Yashraj Behera ·

    AI 内存从 42GB 降至 7GB。谷歌的 TurboQuant 究竟做了什么。

    <h4><strong>Google’s TurboQuant compresses LLM memory by 6x with zero accuracy loss. Here’s what that actually means for your infrastructure bill — and what to do about it today.</strong></h4><figure><img alt="" src="https://cdn-images-1.medium.com/max/1024/1*rmeqHlUvSl3UyE5Hk1Fq…