PulseAugur
中
实时 04:05:18
English(EN) Döner Bench round 2: Quant compare

Döner Bench 基准测试在 Reddit 上对比量化 AI 模型

Reddit 用户在 r/LocalLLaMA 论坛上对 Döner Bench 基准测试进行了第二轮比较,重点关注同一模型不同量化级别的表现。该用户测试了 Qwen 3.6 和 Gemma 4 等模型,评估它们生成特定 HTML 文件(描绘旋转的土耳其烤肉)的能力。虽然更高量化级别的模型通常表现更好,但即使是较低量化级别的模型也通过从多次运行中选择最佳主观结果来进行评估,用户指出较低质量版本“细腻度”和“美味度”有所下降。 AI

影响 为特定创意任务中量化模型的性能下降提供了见解。

排序理由 用户进行的量化 AI 模型基准测试比较。[lever_c_demoted from research: ic=1 ai=1.0]

在 r/LocalLLaMA 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
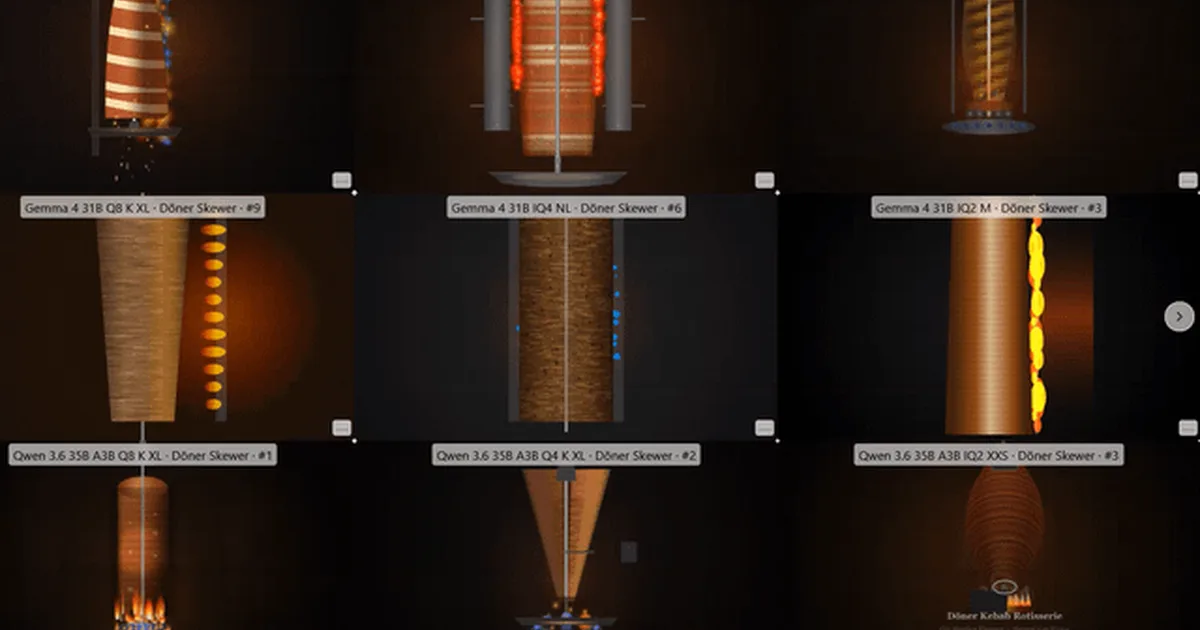
Döner Bench 基准测试在 Reddit 上对比量化 AI 模型

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
用户进行的量化 AI 模型基准测试比较。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
113 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. r/LocalLLaMA TIER_1 English(EN) · /u/Excellent_Jelly2788 ·

    Döner Bench 第二轮:Quant 比较

    <table> <tr><td> <a href="https://www.reddit.com/r/LocalLLaMA/comments/1uqs7ws/döner_bench_round_2_quant_compare/"> <img alt="Döner Bench round 2: Quant compare" src="https://external-preview.redd.it/aHNib2Q5bHAyMGNoMWRXry_MhLp2kjsX77lmEripEO1sa2FDlEIMcX_wFDBT.png?width=640&amp;c…