PulseAugur
中
实时 05:43:43
English(EN) Choosing the Right Web Scraping Tool in 2026 Different web scraping projects require different approaches, from enterprise-scale data collection and AI pipeline

AI管道和企业数据收集的网络抓取工具对比

此信息图比较了2026年适用于不同项目需求的各种网络抓取工具。它涵盖了企业级数据收集、AI管道、浏览器自动化、无代码工作流和合规性,评估了Bright Data、Firecrawl、Scrapy、Playwright、Octoparse、Scrape.do和Zyte等工具。 AI

影响 提供了支持AI管道和AI应用数据收集的工具的见解。

排序理由 该项目讨论了网络抓取工具的比较,属于“工具”类别。

在 Mastodon — sigmoid.social 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
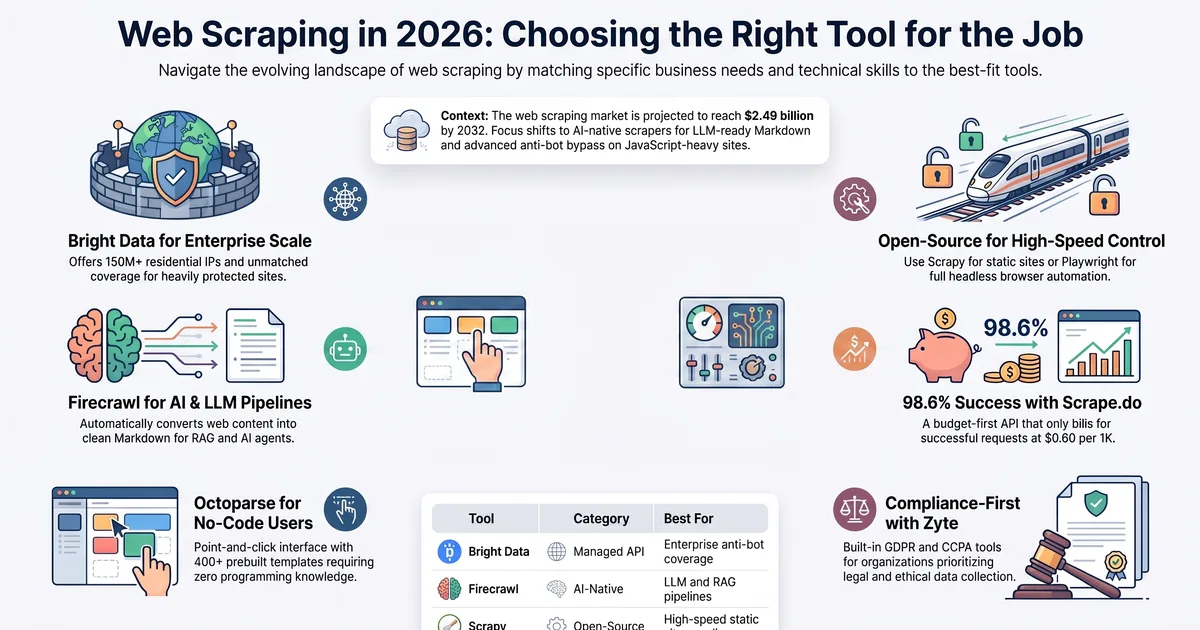
AI管道和企业数据收集的网络抓取工具对比

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该项目讨论了网络抓取工具的比较,属于“工具”类别。
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
product, infra, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
103 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. Mastodon — sigmoid.social TIER_1 English(EN) · [email protected] ·

    2026年选择合适的网络抓取工具 不同的网络抓取项目需要不同的方法,从企业级数据收集和AI管道

    Choosing the Right Web Scraping Tool in 2026 Different web scraping projects require different approaches, from enterprise-scale data collection and AI pipelines to browser automation, no-code workflows, and compliance. This infographic compares Bright Data, Firecrawl, Scrapy, Pl…