PulseAugur
中
实时 09:49:58
中文(ZH) 自变量发布跨模态具身动作分词器 X-Tokenizer,多模态对齐能力提升 13.5%,长程任务性能提升 8.25%

Self-Variable Robotics unveils X-Tokenizer for embodied AI action segmentation

Zibianliang (Self-Variable) Robotics has introduced X-Tokenizer, a novel cross-modal embodied action tokenizer designed to improve the semantic understanding between visual-language models (VLMs) and robot action experts. Unlike previous methods that focused solely on minimizing reconstruction error, X-Tokenizer utilizes a novel Semantic Residual Quantization (SRQ) architecture. This approach separates coarse-grained action intent from fine-grained geometric corrections, incorporating cross-modal supervision signals to align action tokens with visual and language semantics. AI

影响 This new action tokenizer could improve the performance and robustness of embodied AI systems, particularly in long-range tasks and noisy environments.

排序理由 The item describes a new technical approach and architecture for action tokenization in embodied AI, supported by experimental results and benchmark comparisons. [lever_c_demoted from research: ic=1 ai=1.0]

在 雷峰网 (Leiphone) 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
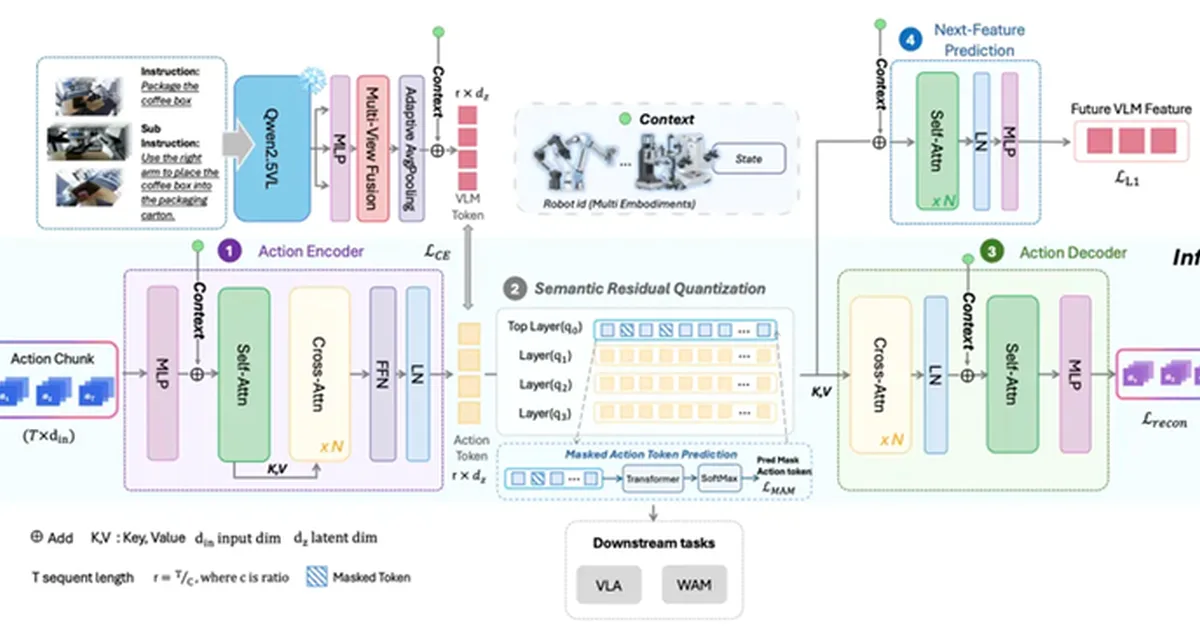
Self-Variable Robotics unveils X-Tokenizer for embodied AI action segmentation

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The item describes a new technical approach and architecture for action tokenization in embodied AI, supported by experimental results and benchmark comparisons. [lever_c_demoted from research: ic=…
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
model release, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
94 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. 雷峰网 (Leiphone) TIER_1 中文(ZH) ·

    Independent variable发布跨模态具身动作分词器X-Tokenizer,多模态对齐能力提升13.5%,长程任务表现提升8.25%

    <p><strong>自变量机器人发布跨模态具身动作分词器 X-Tokenizer</strong>,将 VLA 中的动作离散化从单一的“压缩-重建”问题,重新定义为“多模态推理与动作之间的语义接口学习”问题。</p><p>动作分词器决定了拆分出的动作 Token 是否具有语义,是否能加速预训练模型的收敛,从而最终影响了 VLA 模型输出连续动作的性能。这是自变量机器人的最新发现。</p><p>具身智能的 VLA 模型(视觉-语言-动作模型)是将预训练的 VLM 模型(视觉语言模型)与动作专家(Action Expert)连接起来,前者接收图像和语言指令…