PulseAugur
中
实时 10:04:20
English(EN) We heard your feedback. You want to go faster.

Fireworks AI推出GLM 5.2 Fast以提高推理速度 · 跟踪2个来源

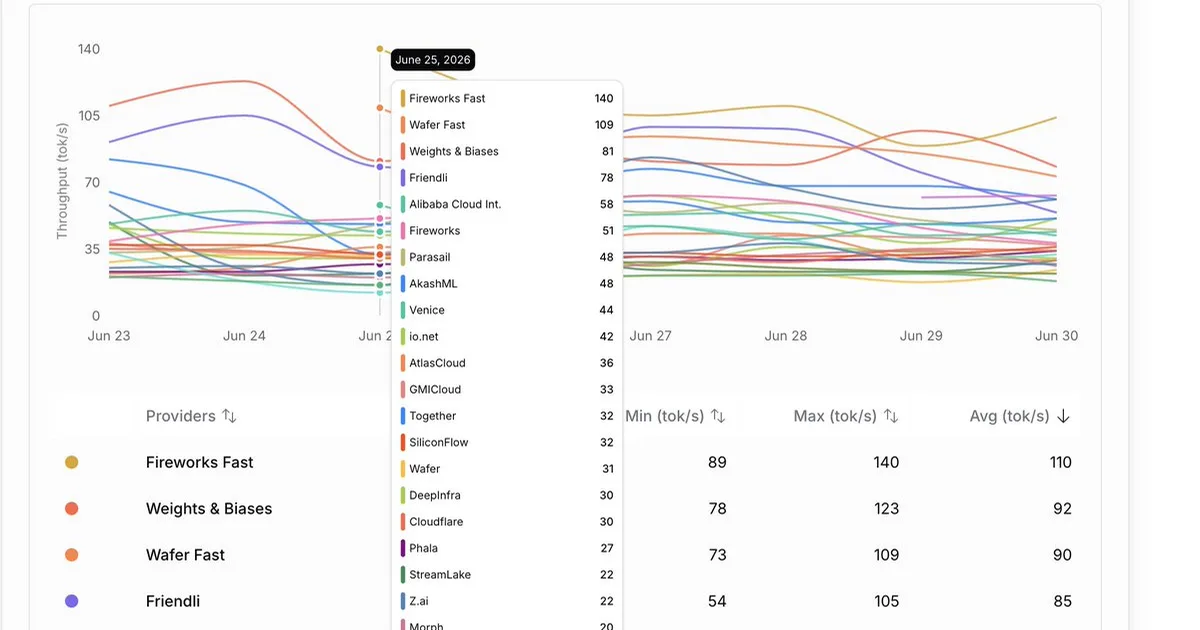
Fireworks AI发布了GLM 5.2模型的更快版本,名为GLM 5.2 Fast。新版本在保持标准GLM 5.2相同质量的同时,实现了显著更高的推理速度,最高可达每秒140个token。该公司还强调了用于实现更高性能的定制部署选项,指出在Artificial Analysis上速度可达每秒446个token。 AI

影响 提高LLM的推理速度,可能降低成本并改善实时应用程序性能。

排序理由 前沿AI实验室的模型发布。[lever_c_demoted from frontier_release: ic=2 ai=1.0]

在 X — Fireworks (inference infra) 阅读 →

AI 生成摘要 · Google Gemini · 来自 2 个来源。 我们如何撰写摘要 →
Fireworks AI推出GLM 5.2 Fast以提高推理速度 · 跟踪2个来源

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Significant
前沿AI实验室的模型发布。[lever_c_demoted from frontier_release: ic=2 ai=1.0]
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
model release, infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
100 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [2]

  1. X — Fireworks (inference infra) TIER_1 English(EN) · FireworksAI_HQ ·

    如需更高速度,请联系定制部署!

    For even higher speeds, reach out for a custom deployment! We’ve hit 446 tok/s on Artificial Analysis. Learn more → https://t.co/rpFJ2dIZvX

  2. X — Fireworks (inference infra) TIER_1 English(EN) · FireworksAI_HQ ·

    我们听取了您的反馈。您希望更快。

    We heard your feedback. You want to go faster. Introducing GLM 5.2 Fast The same model and quality as GLM 5.2 standard, now at 140 tok/s Flip one model ID → accounts/fireworks/routers/glm-5p2-fast https://t.co/jaYWA4lPi0