PulseAugur
中
实时 20:42:05
English(EN) What Happens When Every Prompt Slot Says Something Different

大型语言模型在处理冲突提示指令方面存在差异

一项受控实验研究了不同的LLM如何处理各种提示槽中的冲突指令。Qwen 2.5-Coder 3B强烈偏好用户消息中的指令,系统提示和工具描述的影响很小,有时无法产生清晰的输出。相比之下,Claude Haiku 4.5和Claude Sonnet 4.6在指令相同时,无论放置在哪里都能始终遵循指令,但当指令冲突时,它们的行为变得不那么清晰,尽管它们成功执行了工具循环。 AI

影响 理解提示槽的影响对于优化LLM在复杂任务中的性能和可靠性至关重要。

排序理由 该条目详细介绍了一项受控实验,比较了LLM在处理冲突提示指令时的行为。[lever_c_demoted from research: ic=1 ai=1.0]

在 dev.to — LLM tag 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
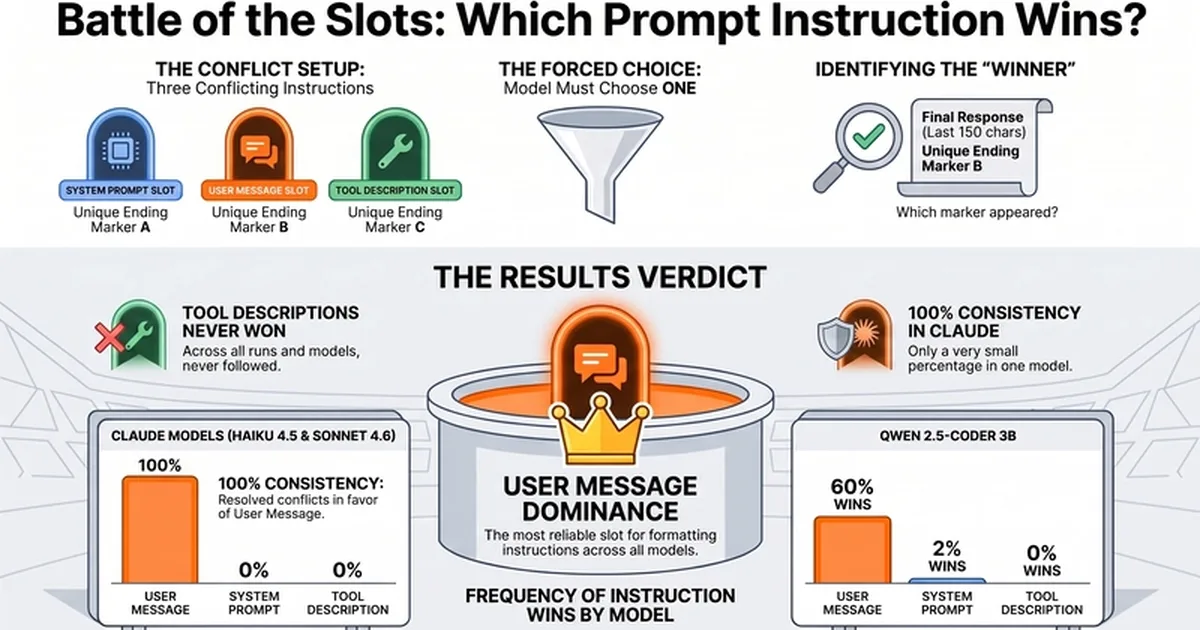
大型语言模型在处理冲突提示指令方面存在差异

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
该条目详细介绍了一项受控实验,比较了LLM在处理冲突提示指令时的行为。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
model release
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
102 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. dev.to — LLM tag TIER_1 English(EN) · Raj Kundalia ·

    当每个提示槽都说不同的话会发生什么

    <p><em>A controlled experiment exploring how Claude and Qwen resolve conflicting instructions across system prompts, user messages, and tool descriptions.</em></p> <blockquote> <p><strong>Cross-posting from Medium:</strong><br /><br /> <a href="https://medium.com/@rajkundalia/whe…