PulseAugur
中
实时 23:01:58
English(EN) How to Run Reliable Local LLM Agents on an RTX 3090: A Benchmark (5 Models, Priced in Watts)

本地LLM代理基准测试:框架在RTX 3090上表现优于模型

一项基准研究在RTX 3090 GPU上评估了五个本地LLM模型,重点关注它们在不同编排框架下的性能。研究发现,框架的选择,特别是支持原生工具调用(如LangGraph)的框架,显著影响模型的有效性,其中一个模型在使用合适的代理时,成功率从0%提高到93%。研究还强调了工具遵循的重要性,并测量了每项正确任务的电力成本,确定Qwen3-Coder是本地代理任务的高效模型。 AI

影响 强调了代理编排在释放本地应用LLM潜力中的关键作用。

排序理由 基准研究,比较LLM模型和编排框架。

在 dev.to — LLM tag 阅读 →

AI 生成摘要 · Google Gemini · 来自 2 个来源。 我们如何撰写摘要 →
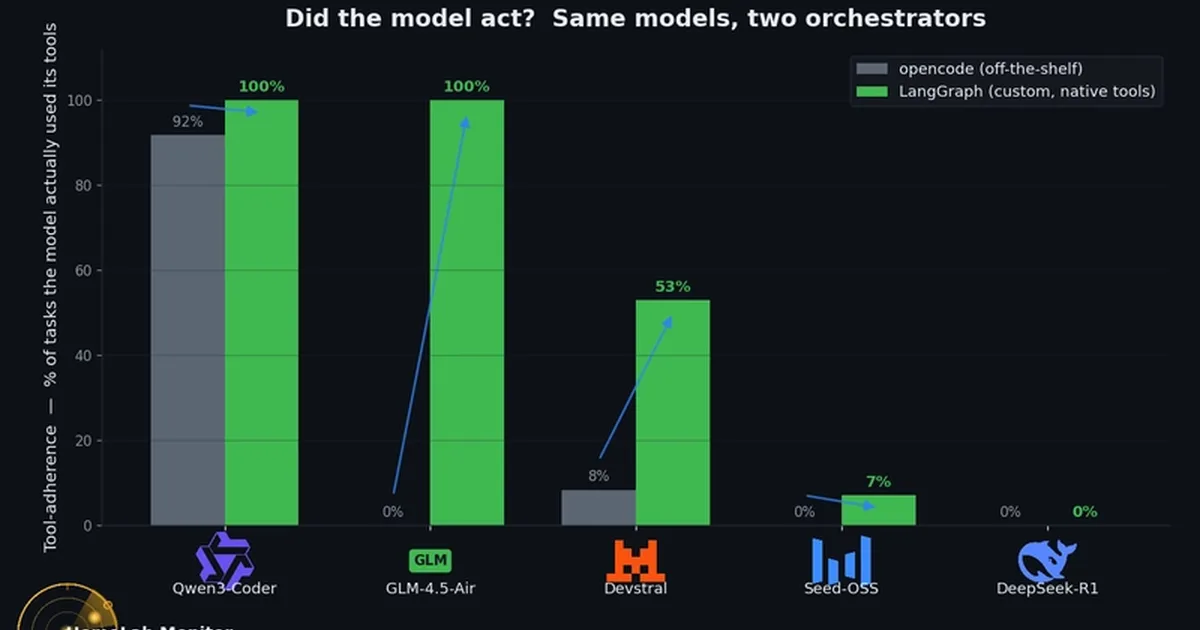
本地LLM代理基准测试:框架在RTX 3090上表现优于模型

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
基准研究,比较LLM模型和编排框架。
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
117 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [2]

  1. Mastodon — fosstodon.org TIER_1 English(EN) · [email protected] ·

    如何在RTX 3090上运行可靠的本地LLM代理:基准测试(5个模型,按功耗计价)我给GLM-4.5-Air(106B,开放权重)通过ope的12项编码任务

    How to Run Reliable Local LLM Agents on an RTX 3090: A Benchmark (5 Models, Priced in Watts) I gave GLM-4.5-Air (106B, open weights) 12 coding tasks through opencode on my RTX 3090. It scored 0% ... #llm #homelab #opensource #ai Origin | Interest | Match

  2. dev.to — LLM tag TIER_1 English(EN) · Arsen Apostolov ·

    如何在RTX 3090上运行可靠的本地LLM代理:一个基准测试(5个模型,以瓦特计价)

    <p>I gave <strong>GLM-4.5-Air</strong> (106B, open weights) 12 coding tasks through <a href="https://opencode.ai" rel="noopener noreferrer">opencode</a> on my RTX 3090. It scored <strong>0%</strong> — never edited a single file.</p> <p>Same model, same GPU, same tasks, but driven…