PulseAugur
中
实时 22:17:49
English(EN) A 4B Model Just Beat a 397B Baseline - By Changing How Training Data Was Made

40亿参数模型通过更智能的数据生成超越3970亿参数基线模型

Meta FAIR开发的一种名为Autodata的新方法表明,一个参数量显著更小的40亿模型在特定任务上可以超越一个参数量大得多的3970亿模型。这种改进并非通过架构更改实现,而是通过优化数据生成过程。Autodata使用一个带有多个子代理的协调器代理来创建精确校准目标模型学习能力的训练数据,确保难度平衡,从而促进有效的梯度下降。 AI

影响 表明优化训练数据生成可以带来显著的性能提升,可能减少对超大规模模型的需求。

排序理由 详细介绍LLM新型数据生成方法的 ist 研究论文。[lever_c_demoted from research: ic=1 ai=1.0]

在 dev.to — LLM tag 阅读 →

AI 生成摘要 · Google Gemini · 来自 1 个来源。 我们如何撰写摘要 →
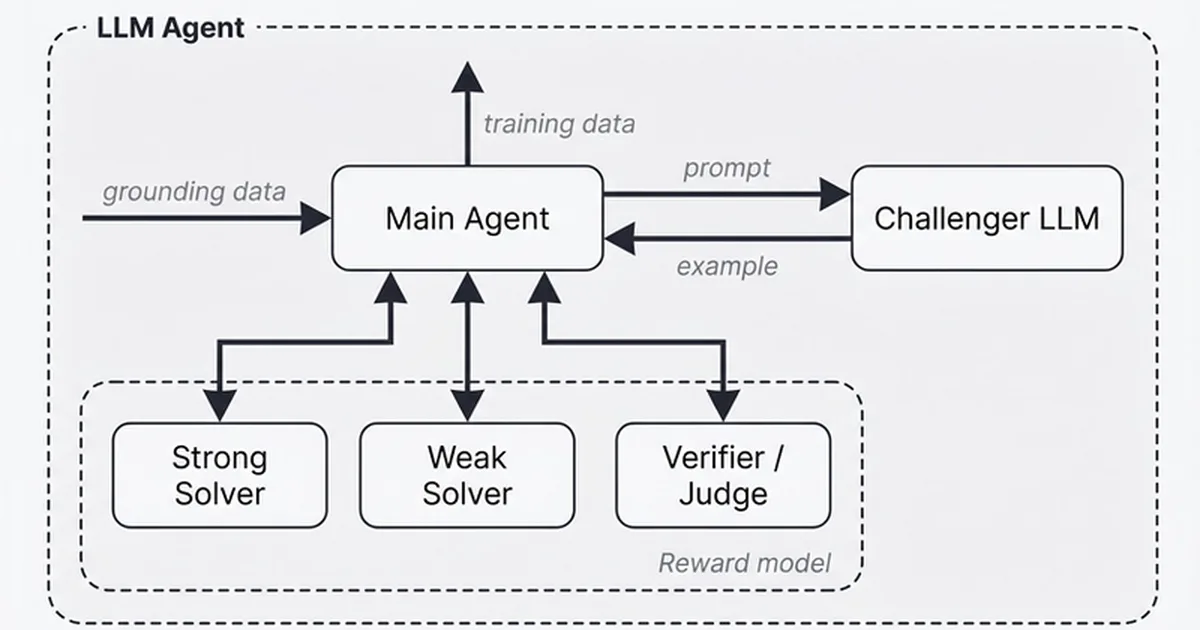
40亿参数模型通过更智能的数据生成超越3970亿参数基线模型

本文如何被排名

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
详细介绍LLM新型数据生成方法的 ist 研究论文。[lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
model release, infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
102 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

完整方法见我们的编辑标准。

报道来源 [1]

  1. dev.to — LLM tag TIER_1 English(EN) · dang phan ·

    一个40亿参数模型通过改变训练数据生成方式击败了3970亿参数基线

    <p>Meta FAIR just published a result that's hard to ignore: a 4B parameter model, after being trained on data generated by <strong>Autodata</strong>, outperformed their own 397B model on PRBench-Legal - without any architectural changes.</p> <p>The only variable: how the training…