PulseAugur
EN
LIVE 14:38:37

llama.cpp flag boosts Qwen 35B model speed by 2.8x on RTX 4070

A technical guide demonstrates how to achieve a 2.8x speedup when running the Qwen3.5-35B-A3B model on an RTX 4070 GPU with 12GB of VRAM. The key to this performance increase lies in using the `llama.cpp` framework with specific flags: `-ngl 99` to offload all model layers to the GPU and `--cpu-moe` to keep the Mixture of Experts (MoE) layers on the CPU. This strategy is particularly effective for MoE models, where only a fraction of experts are active per token, making it inefficient to load all experts onto the GPU when VRAM is limited. The guide also provides a sweep of different offload configurations to help users determine the optimal settings for various VRAM tiers. AI

IMPACT Optimizing LLM inference speed on consumer hardware, making larger models more accessible.

RANK_REASON Technical guide on optimizing a specific model's performance using particular software flags.

Read on dev.to — LLM tag →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
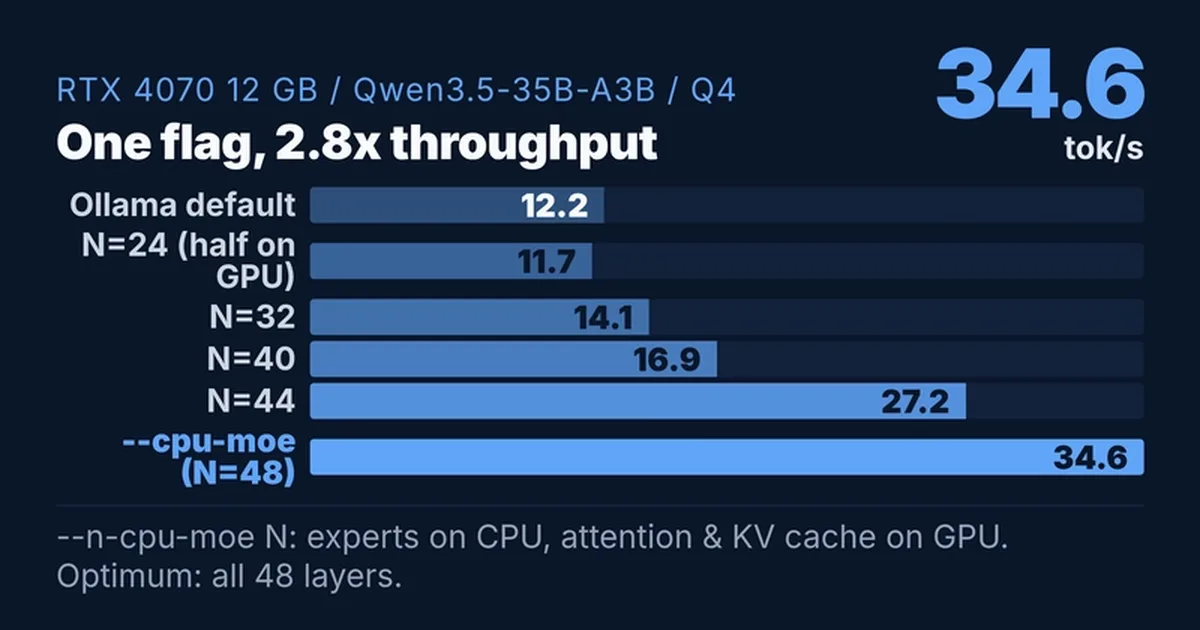
llama.cpp flag boosts Qwen 35B model speed by 2.8x on RTX 4070

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
Technical guide on optimizing a specific model's performance using particular software flags.
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
87 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. dev.to — LLM tag TIER_1 English(EN) · Ken Imoto ·

    RTX 4070 + Qwen 35B: 2.8x Speedup From One llama.cpp Flag (--cpu-moe)

    <p>The Ollama defaults gave me <strong>12.2 tok/s</strong> on Qwen3.5-35B-A3B against an RTX 4070 (12 GB). I switched to <code>llama.cpp</code> with two flags and got <strong>34.6 tok/s</strong>. 2.8x.</p> <p>The two flags were <code>-ngl 99</code> (offload all layers to GPU) and…