PulseAugur
EN
LIVE 11:40:19

QLoRA: A Memory-Efficient Fine-Tuning Technique Explained

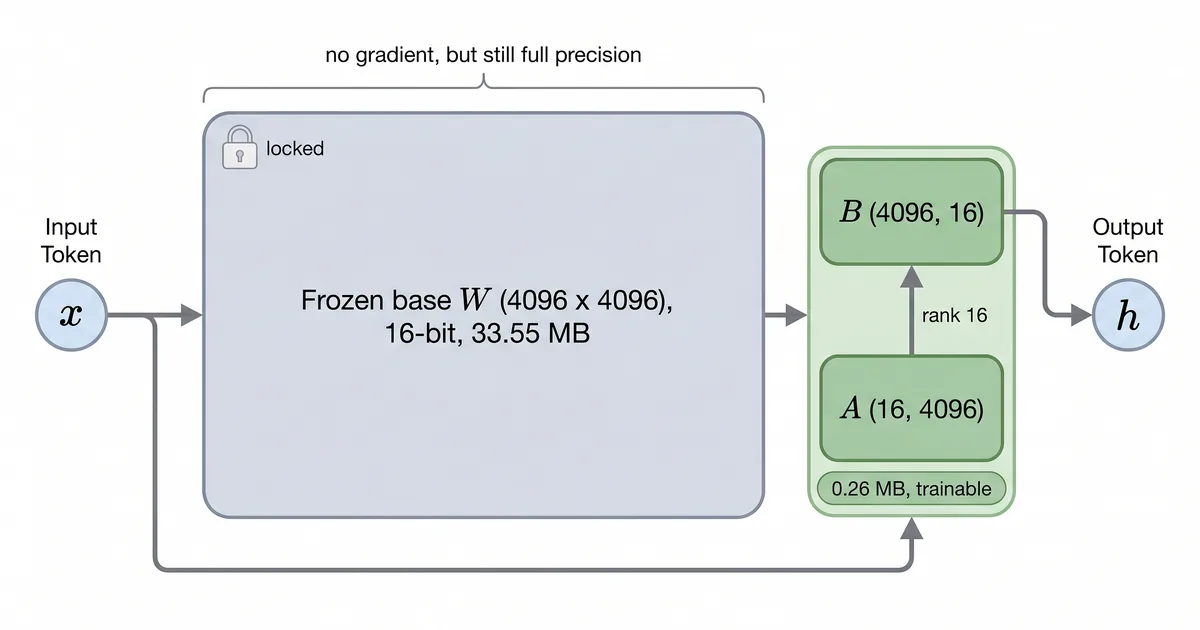
QLoRA, or Quantized Low-Rank Adaptation, is a technique that allows for the fine-tuning of large language models using significantly less memory. This method involves quantizing the model weights to 4-bit precision, effectively reducing their size by three-quarters while maintaining 16-bit precision for the adaptation parameters. This approach enables the fine-tuning of models with up to 65 billion parameters on a single GPU. AI

IMPACT Enables fine-tuning of large language models on consumer hardware, democratizing access to advanced AI customization.

RANK_REASON The item explains a specific research technique (QLoRA) for fine-tuning large language models. [lever_c_demoted from research: ic=1 ai=1.0]

Read on Medium — fine-tuning tag →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
QLoRA: A Memory-Efficient Fine-Tuning Technique Explained

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The item explains a specific research technique (QLoRA) for fine-tuning large language models. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
127 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. Medium — fine-tuning tag TIER_1 English(EN) · Vizuara AI ·

    What exactly is QLoRA (Quantized Low-Rank Adaptation)?

    <div class="medium-feed-item"><p class="medium-feed-image"><a href="https://vizuara.medium.com/what-exactly-is-qlora-quantized-low-rank-adaptation-d19218b3ff2e?source=rss------fine_tuning-5"><img src="https://cdn-images-1.medium.com/max/2600/1*8RRDisu17TmYPVfEfn2hIw.png" width="2…