PulseAugur
EN
LIVE 15:17:08

Continuous batching boosts LLM inference efficiency by optimizing GPU usage

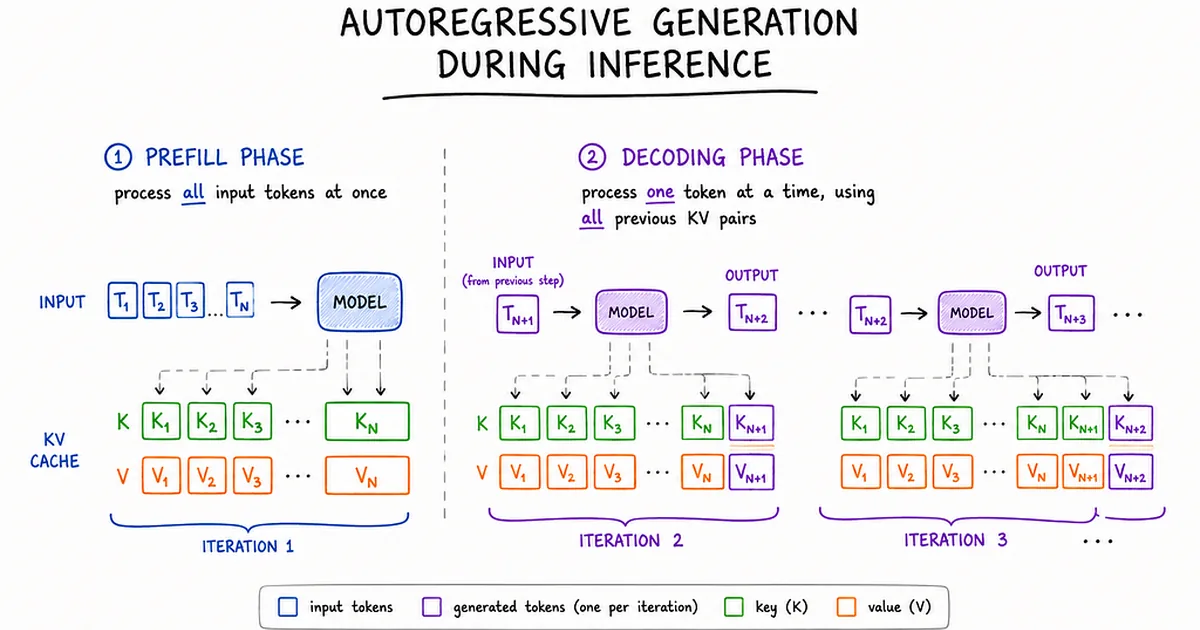
Continuous batching is an optimization technique designed to improve GPU utilization during large language model (LLM) inference. Traditional static batching methods suffer from the 'straggler problem,' where the slowest request in a batch dictates the processing time for all, leading to significant GPU idle time. Continuous batching addresses this by dynamically re-evaluating and adjusting the batch at each iteration, allowing finished requests to be immediately replaced by new ones from the queue. This iterative scheduling ensures that GPU resources are continuously utilized, dramatically increasing throughput and efficiency compared to static batching. AI

IMPACT Enhances LLM serving efficiency, potentially lowering inference costs and improving user experience by reducing latency.

RANK_REASON The item discusses a technical optimization for LLM inference, which is a research topic in AI infrastructure. [lever_c_demoted from research: ic=1 ai=1.0]

Read on Towards AI →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
Continuous batching boosts LLM inference efficiency by optimizing GPU usage

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The item discusses a technical optimization for LLM inference, which is a research topic in AI infrastructure. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
99 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. Towards AI TIER_1 English(EN) · Vedanti ·

    Continuous Batching: How to Keep Your GPU Actually Busy

    <p>I was going over my LLM inference notes from Carnegie Mellon University today and I thought this is one of the important topics I should write about. So here we go 🙂</p><p>If you’ve been following along, we’ve talked about the KV cache and speculative decoding. This one is abo…