PulseAugur
EN
LIVE 14:34:02

Transformers Explained: Self-Attention, Parallel Processing, and LLM Architecture

Transformers, a neural network architecture, revolutionized AI by processing tokens in parallel rather than sequentially like Recurrent Neural Networks (RNNs). This parallel processing, enabled by the self-attention mechanism, allows each token to directly compare itself with all other tokens in a sequence. Self-attention uses Query, Key, and Value vectors to determine how much attention each token should pay to others, creating context-aware embeddings. This approach, often enhanced with multi-head attention and positional encoding, handles long-range dependencies more effectively and scales better on hardware like graphics processing units. AI

IMPACT Explains the fundamental architecture enabling modern LLMs, highlighting the shift from sequential to parallel processing via self-attention.

RANK_REASON The cluster explains a core AI architecture (Transformers) and its key mechanism (self-attention) in detail, suitable for an educational or research context.

Read on dev.to — LLM tag →

AI-generated summary · Google Gemini · from 2 sources. How we write summaries →
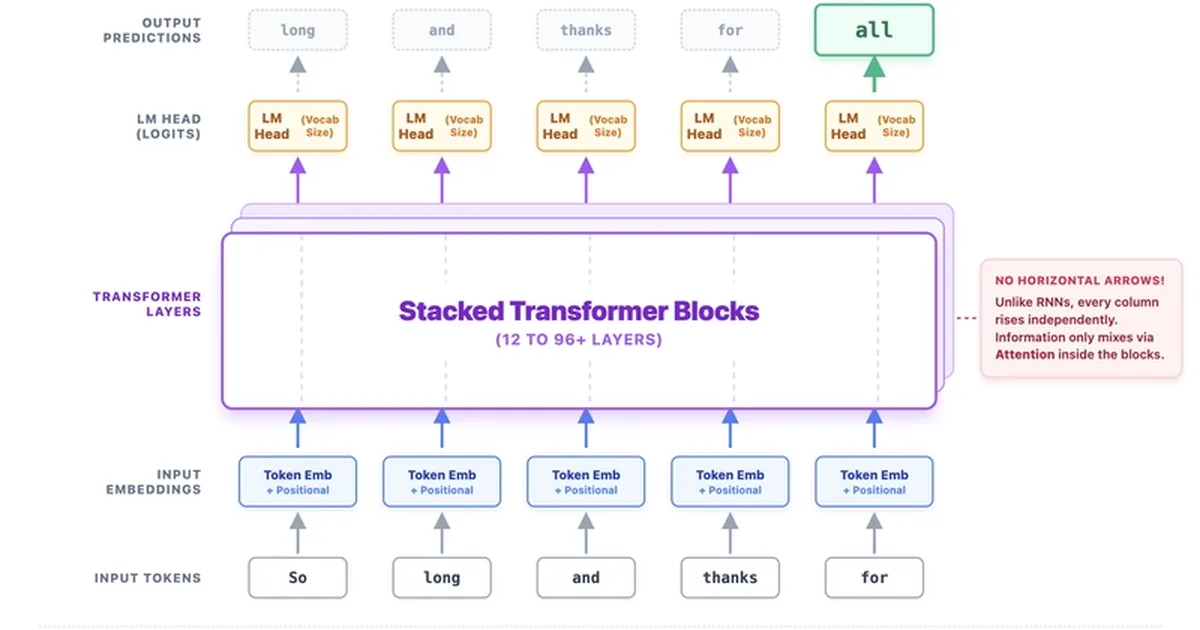
Transformers Explained: Self-Attention, Parallel Processing, and LLM Architecture

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
The cluster explains a core AI architecture (Transformers) and its key mechanism (self-attention) in detail, suitable for an educational or research context.
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
paper, infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
102 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [2]

  1. dev.to — LLM tag TIER_1 English(EN) · Akash ·

    How Transformers Actually Work: Self-Attention, Step by Step

    <h2> Building Context: Query, Key, Value, and the Transformer Block </h2> <p>The last two posts ended on the same cliffhanger: RNNs carry context through a single thread of hidden state that frays on long sequences and forces everything through one bottleneck vector. The fix, I k…

  2. dev.to — LLM tag TIER_1 English(EN) · zeromathai ·

    How Transformers Work — From Self-Attention to Modern LLM Architecture

    <p>Transformers changed AI because they stopped reading sequences one token at a time.</p> <p>Instead of moving step by step like an RNN, a Transformer compares tokens directly.</p> <p>That one design shift made modern LLMs possible.</p> <h2> Core Idea </h2> <p>A Transformer is a…