PulseAugur
EN
LIVE 23:28:23

AI models struggle to reliably verbalize internal reasoning

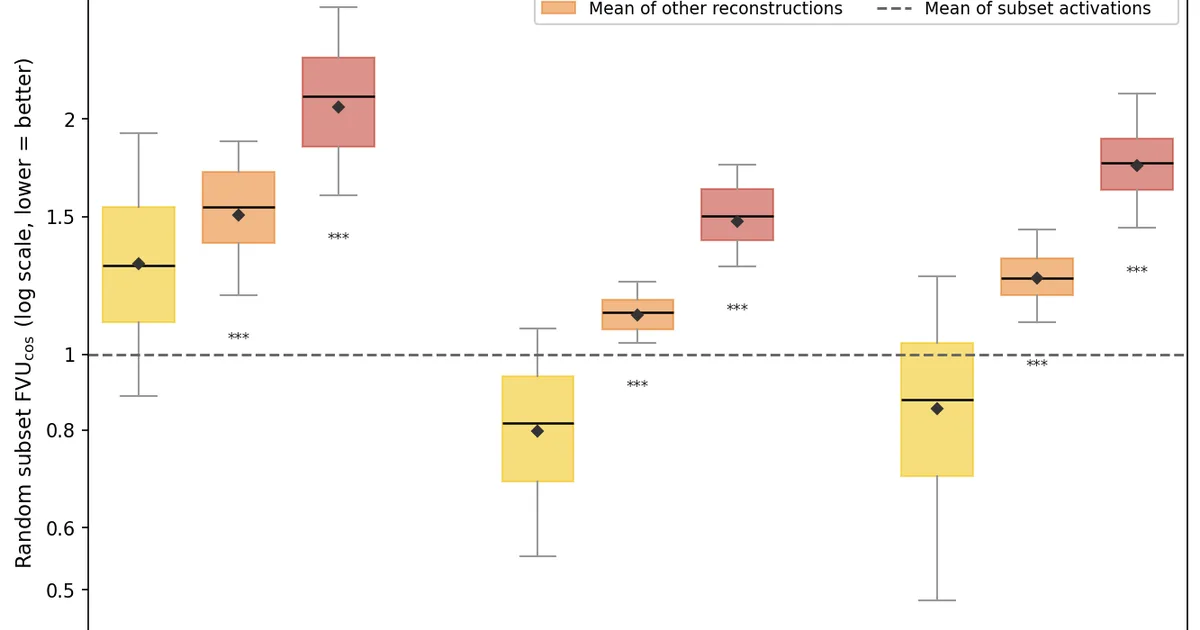
Researchers have evaluated activation verbalizers (AVs) to determine if they can reliably surface a target model's internal reasoning process during a single forward pass, particularly for math problems. The study applied this evaluation to open-weight natural language autoencoders (NLAs) for models like Qwen2.5, Gemma, and Llama 3.3. Initial findings suggest that these NLAs are not yet proficient enough at reconstruction to consistently track subtle differences in opaque reasoning, with some models performing worse than a simple baseline. AI

IMPACT New research suggests current methods for verbalizing AI model reasoning are unreliable, potentially hindering efforts to monitor complex internal thought processes.

RANK_REASON The cluster describes a research paper evaluating a new method for understanding AI model reasoning. [lever_c_demoted from research: ic=1 ai=1.0]

Read on Alignment Forum →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
AI models struggle to reliably verbalize internal reasoning

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The cluster describes a research paper evaluating a new method for understanding AI model reasoning. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, safety
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
113 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. Alignment Forum TIER_1 English(EN) · oakhu ·

    Can activation verbalizers surface an internal chain of thought?

    <p><i><span>We introduce an evaluation for activation verbalizers: can they surface a target model's reasoning as it solves a math problem in a single forward pass? For open-weight NLAs, the answer seems to be: "possibly, but definitely not reliably".</span></i></p><p><span>Lots …