PulseAugur
EN
LIVE 20:07:34

Alibaba's Qwen unveils FlashQLA for high-performance linear attention kernels

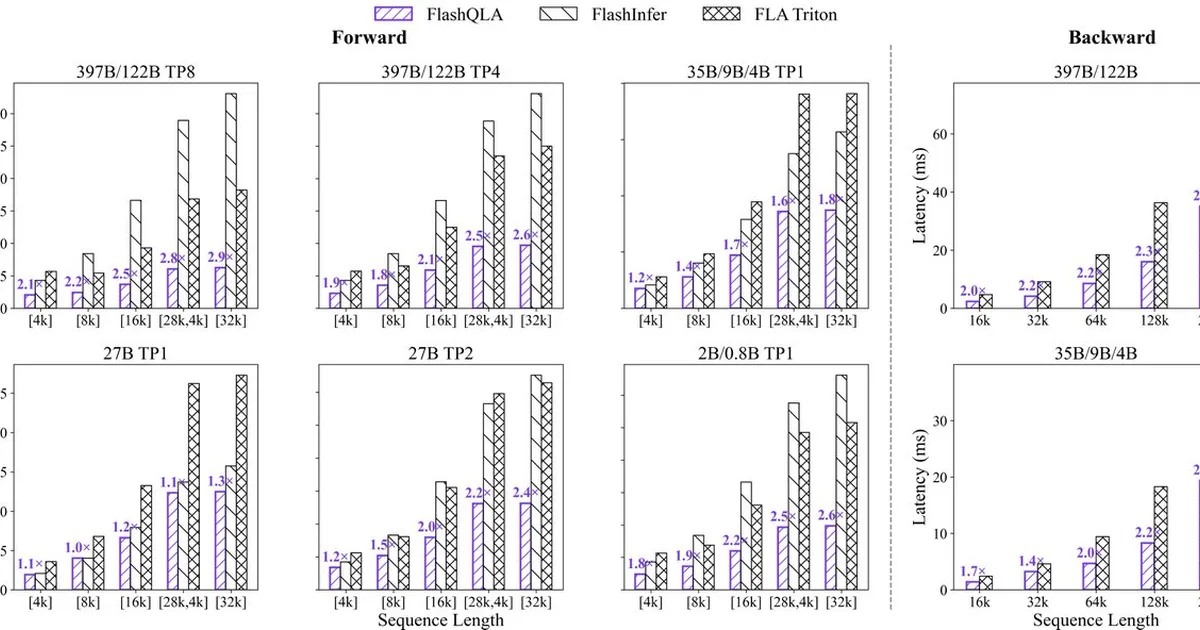
Alibaba's Qwen team has released FlashQLA, a new set of high-performance linear attention kernels developed using TileLang. These kernels are designed to improve the efficiency of attention mechanisms in large language models. The team also shared benchmark results for their Qwen models, showcasing performance across various configurations. AI

IMPACT Introduces optimized kernels that could improve LLM inference speed and efficiency.

RANK_REASON Release of new high-performance kernels and benchmark results for an existing model family.

Read on X — Qwen (Alibaba) →

AI-generated summary · Google Gemini · from 3 sources. How we write summaries →
Alibaba's Qwen unveils FlashQLA for high-performance linear attention kernels

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
Release of new high-performance kernels and benchmark results for an existing model family.
Source corroboration
3 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
model release, infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
162 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [3]

  1. X — Qwen (Alibaba) TIER_1 English(EN) · Alibaba_Qwen ·

    Forward and backward benchmark results across common configurations. https://t.co/IHMCZRw9AW

    Forward and backward benchmark results across common configurations. https://t.co/IHMCZRw9AW

  2. X — Qwen (Alibaba) TIER_1 English(EN) · Alibaba_Qwen ·

    🚀 Introducing FlashQLA: high-performance linear attention kernels built on TileLang.

    🚀 Introducing FlashQLA: high-performance linear attention kernels built on TileLang. ⚡ 2–3× forward speedup. 2× backward speedup. 💻 Purpose-built for agentic AI on your personal devices. 💡Key insights: 1. Gate-driven automatic intra-card CP. 2. Hardware-friendly algebraic https…

  3. X — Qwen (Alibaba) TIER_1 English(EN) · Alibaba_Qwen ·

    🚀 Introducing FlashQLA: high-performance linear attention kernels built on TileLang.

    🚀 Introducing FlashQLA: high-performance linear attention kernels built on TileLang. ⚡ 2–3× forward speedup. 2× backward speedup. 💻 Purpose-built for agentic AI on your personal devices. 💡Key insights: 1. Gate-driven automatic intra-card CP. 2. Hardware-friendly algebraic https…