PulseAugur
EN
LIVE 05:06:53

RLHF updates LLM weights differently than SFT, research finds

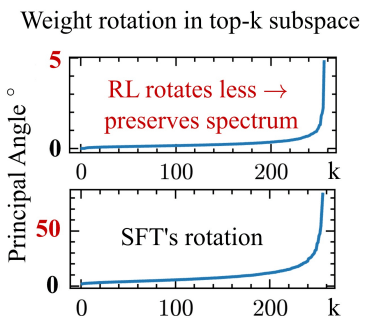
New research suggests that Reinforcement Learning from Human Feedback (RLHF) updates LLM weights differently than pre-training or supervised fine-tuning. These RLHF updates are more sparse and tend to rotate the model's principal subspaces less, indicating a qualitative difference in how they modify the model's behavior. The findings imply that RLHF may primarily elicit existing capabilities rather than create new ones, and can also lead to less degradation of performance on unrelated tasks compared to supervised fine-tuning. AI

IMPACT Suggests RLHF may primarily elicit existing capabilities rather than create new ones, impacting how models are trained and evaluated.

RANK_REASON The cluster consists of a blog post summarizing and analyzing several academic papers on Reinforcement Learning from Human Feedback (RLHF) in LLMs. [lever_c_demoted from research: ic=1 ai=1.0]

Read on LessWrong (AI tag) →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
RLHF updates LLM weights differently than SFT, research finds

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The cluster consists of a blog post summarizing and analyzing several academic papers on Reinforcement Learning from Human Feedback (RLHF) in LLMs. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, model release
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
133 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · CarolusRenniusVitellius ·

    Some Interesting Papers on RLVR

    <p>This post was produced as part of MATS 9.1 under the mentorship of Richard Ngo. It is not part of my main research project, but the ideas have been an important conceptual anchor to me. Epistemically, treat this as watercooler talk. Please feel free to share additional or cont…