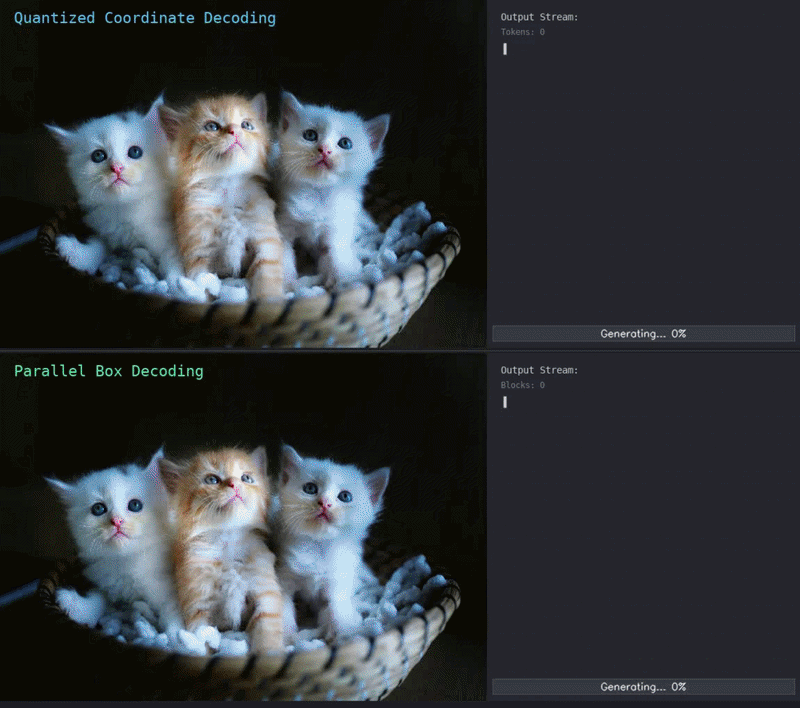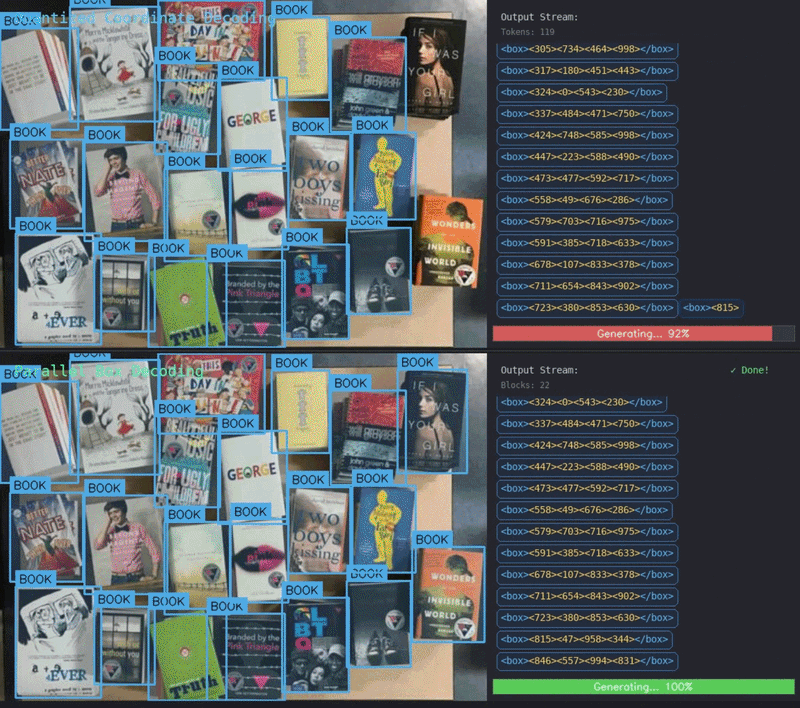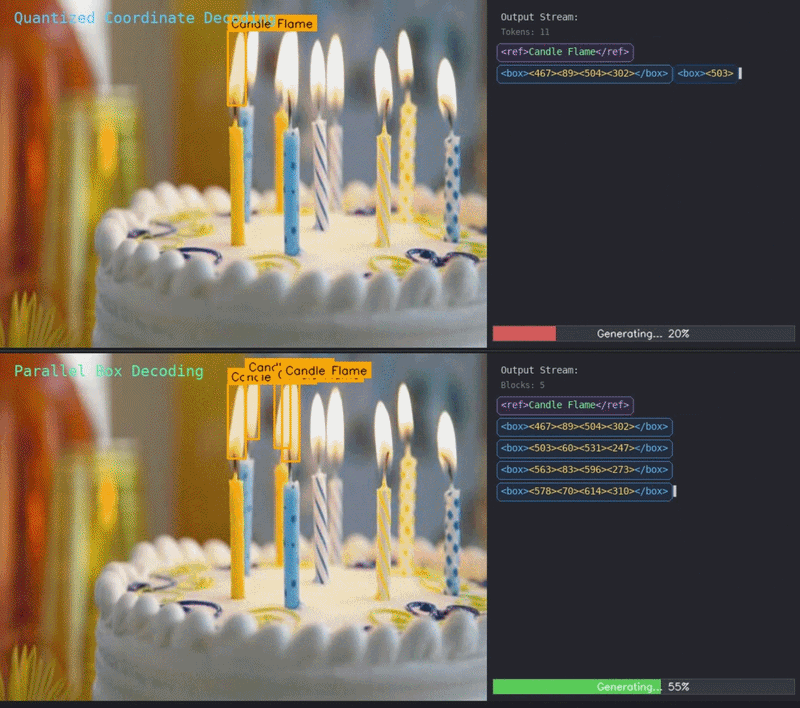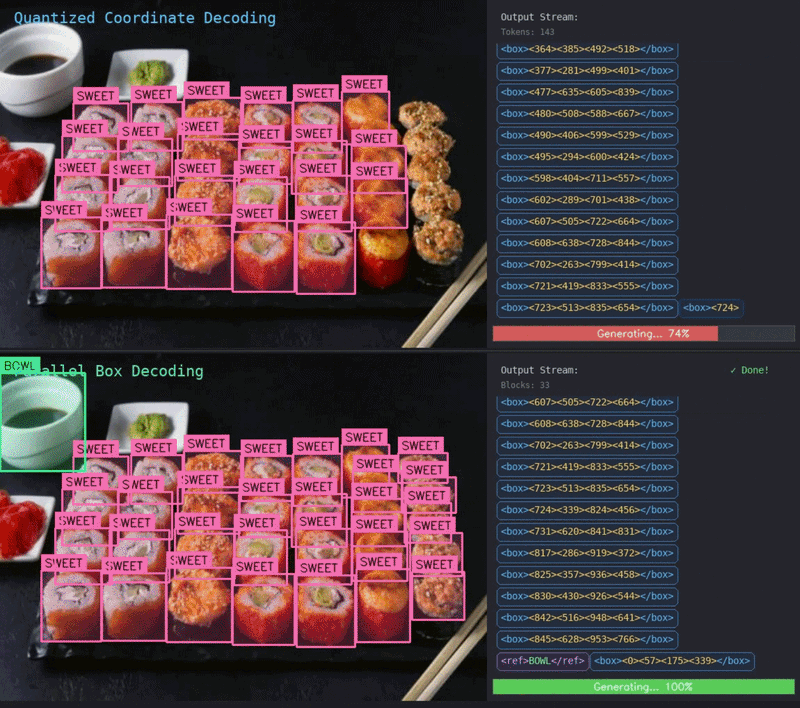
NVIDIA has introduced LocateAnything, a new model designed for visual grounding tasks. This model utilizes Parallel Box Decoding to transform visual grounding into a fundamental agent capability. The development aims to enhance how AI agents interact with and understand visual information. AI
IMPACT Enhances AI agent capabilities by providing a more robust method for visual grounding.
RANK_REASON The cluster describes a new model release from a major tech company, which falls under research or product release. [lever_c_demoted from research: ic=1 ai=1.0]
AI-generated summary · Google Gemini · from 1 sources. How we write summaries →