PulseAugur
EN
LIVE 13:50:00
中文(ZH) DAM-VLA——手臂与夹爪解耦,三星研究院的动态动作VLA刷新机器人操控SOTA | ICRA 2026

Samsung's DAM-VLA decouples robot arm and gripper actions for SOTA manipulation

Researchers have introduced DAM-VLA, a novel Vision-Language-Action (VLA) model designed to enhance robot manipulation by decoupling arm movements from gripper actions. This approach addresses the limitations of existing models that use a single action framework for all tasks, which struggles with the distinct requirements of large-scale arm movements and precise gripper operations. DAM-VLA utilizes a dual-scale weighting mechanism and dynamic action routing to improve efficiency and accuracy, achieving state-of-the-art results on pick-and-place and furniture assembly tasks. AI

IMPACT Introduces a new VLA architecture that improves robot manipulation accuracy and generalization, potentially accelerating progress in embodied AI.

RANK_REASON This is a research paper detailing a new model architecture for robot manipulation.

Read on 雷峰网 (Leiphone) →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
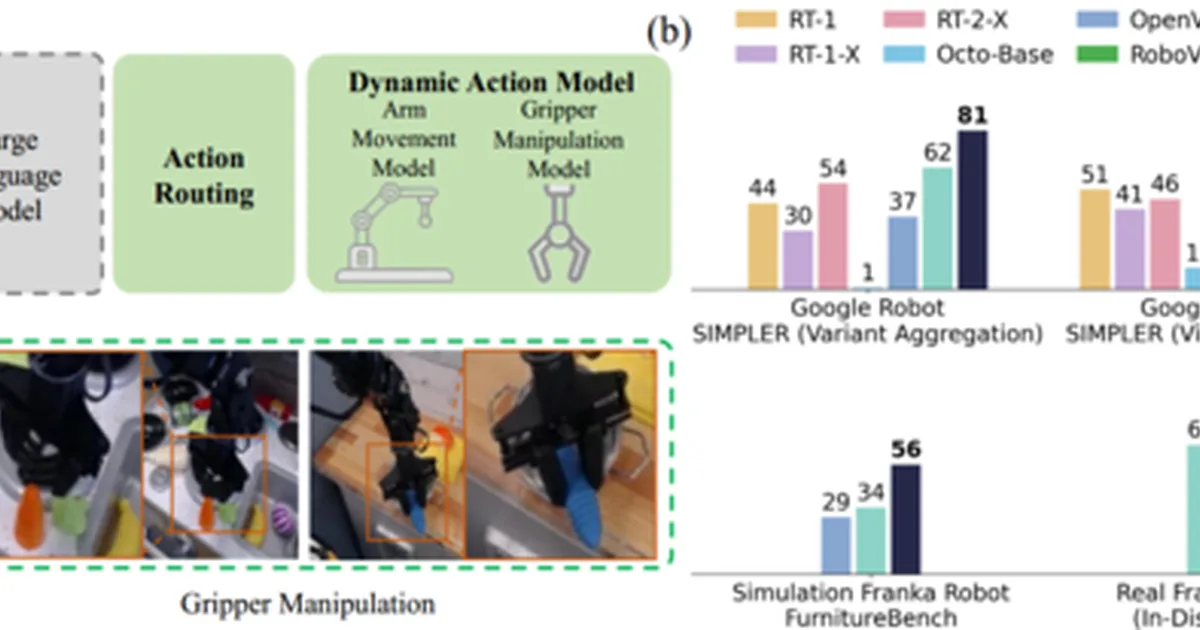
Samsung's DAM-VLA decouples robot arm and gripper actions for SOTA manipulation

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
This is a research paper detailing a new model architecture for robot manipulation.
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, model release
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
174 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. 雷峰网 (Leiphone) TIER_1 中文(ZH) ·

    DAM-VLA -- Decoupling Arms and Grippers, Samsung Research's Dynamic Action VLA Refreshes Robot Manipulation SOTA | ICRA 2026

    <h2>一、背景&nbsp;</h2><p>视觉-语言-动作(VLA)模型正成为机器人智能化的核心架构,但现有主流方法(如OpenVLA、π0、CogACT)存在一个根本性缺陷:用同一个动作模型统一处理所有类型的动作。这种「一刀切」的设计在面对机器人操控任务时暴露出两大内在矛盾。</p><p>从任务特性来看,机器人操控存在两种本质不同的动作类型:手臂大幅度运动(粗动作)需要全局场景理解、路径约束宽松;夹爪精细操作(精细动作)需要局部精细聚焦、精确抓取姿态、容错率极低。这两种动作在路径约束、视觉注意力和数据分布上有本质差异,用同一个模型兼顾「粗定位」与「精…