PulseAugur
EN
LIVE 23:06:33

Perplexity boosts search accuracy with query-aware context compression

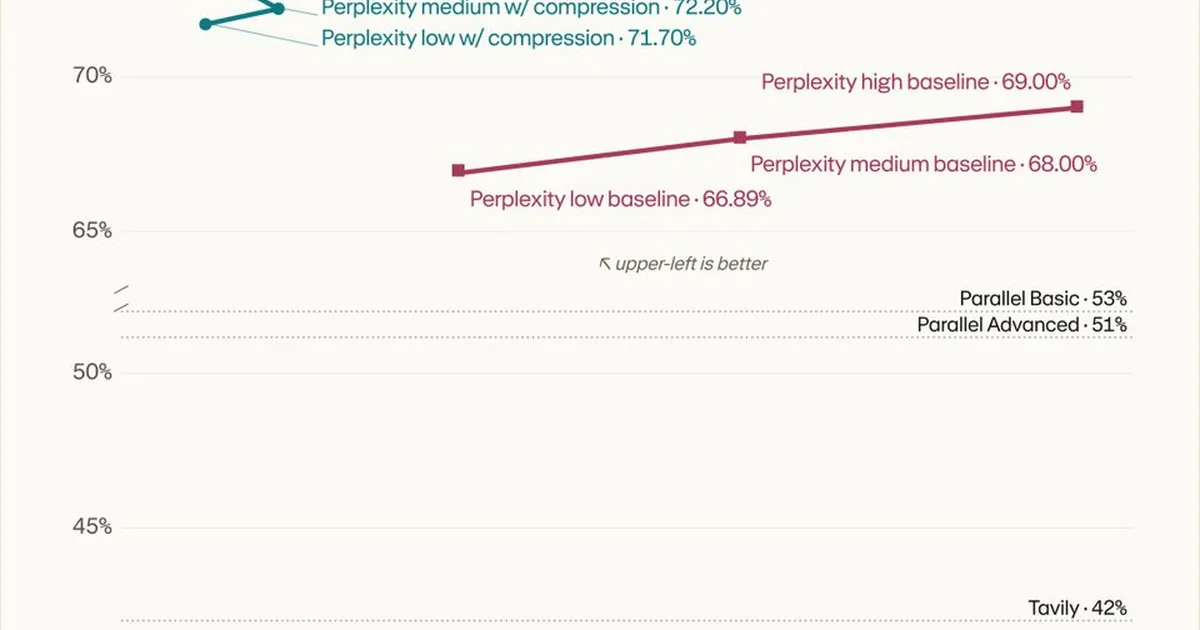
Perplexity has developed a new method for Retrieval-Augmented Generation (RAG) that prioritizes query-aware context compression. This approach significantly reduces the amount of text processed by cutting context tokens by up to 70%, while simultaneously improving answer quality and reducing noise. The company claims this leads to a 63% increase in vital content per snippet and maintains frontier-level performance with a 50x compression ratio on SimpleQA. AI

IMPACT Perplexity's new RAG technique could lead to more efficient and accurate AI-powered search experiences.

RANK_REASON This is a product improvement and research announcement from Perplexity, not a core frontier model release.

Read on X — Perplexity →

AI-generated summary · Google Gemini · from 3 sources. How we write summaries →
Perplexity boosts search accuracy with query-aware context compression

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
This is a product improvement and research announcement from Perplexity, not a core frontier model release.
Source corroboration
3 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
product, paper
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
151 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [3]

  1. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    Context compression isn't new in RAG.

    Context compression isn't new in RAG. Our contribution is making it query-aware, citation-preserving, and fast enough for orchestration. Read the full research blog: https://t.co/KsT98idyks

  2. X — Perplexity TIER_1 Français(FR) · perplexity_ai ·

    Less noise = more signal. Vital content per snippet is up 63%.

    Less noise = more signal. Vital content per snippet is up 63%. Ads, navigation, metadata, and unhelpful content are culled before handoff to the answer model. On SimpleQA, we achieve a 50x compression ratio at frontier-level performance. https://t.co/3JHZheqcW9

  3. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    We've productionized query-aware compression for faster, cleaner, more-accurate search.

    We've productionized query-aware compression for faster, cleaner, more-accurate search. Better context is better than more context. Our system cuts context tokens up to 70% while improving answer quality. https://t.co/gmVr3oZRl9