PulseAugur
EN
LIVE 15:00:32

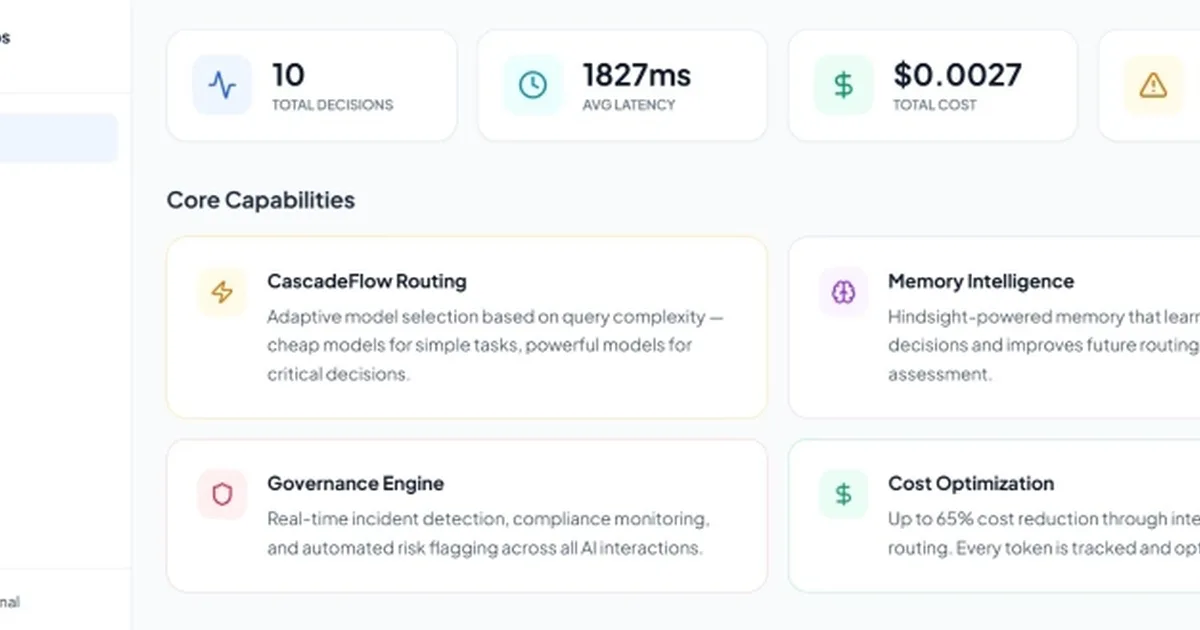
SentinelOps AI cuts LLM costs 65% with query routing

SentinelOps AI implemented a routing layer called CascadeFlow to optimize LLM inference costs. This system directs queries to different models based on complexity, sending simple lookups to a cheaper, faster 8B parameter model and complex operational or compliance questions to a more powerful 70B parameter model. This tiered approach reduced their AI inference bill by 65%, though initial misclassification rates required adjustments like keyword pre-checks and confidence thresholds to maintain accuracy for critical queries. AI

IMPACT Optimizing LLM inference costs through tiered routing can significantly reduce operational expenses for AI-powered applications.

RANK_REASON The article describes the implementation of a new feature/system within an existing product to improve efficiency and reduce costs.

Read on dev.to — LLM tag →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
SentinelOps AI cuts LLM costs 65% with query routing

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The article describes the implementation of a new feature/system within an existing product to improve efficiency and reduce costs.
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
139 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. dev.to — LLM tag TIER_1 English(EN) · Karthik S ·

    Our AI Inference Bill Dropped 65% After We Stopped Treating Every Query the Same

    <ul> <li> Every query hitting our AI layer was going straight to the most powerful model we had. A user asking "what does HIPAA Section 164.312 say?" got the same compute budget as one asking "should we shut down the payment processor during this active incident?" That was expens…