PulseAugur
EN
LIVE 11:57:00

vLLM production guide details key config decisions for performance

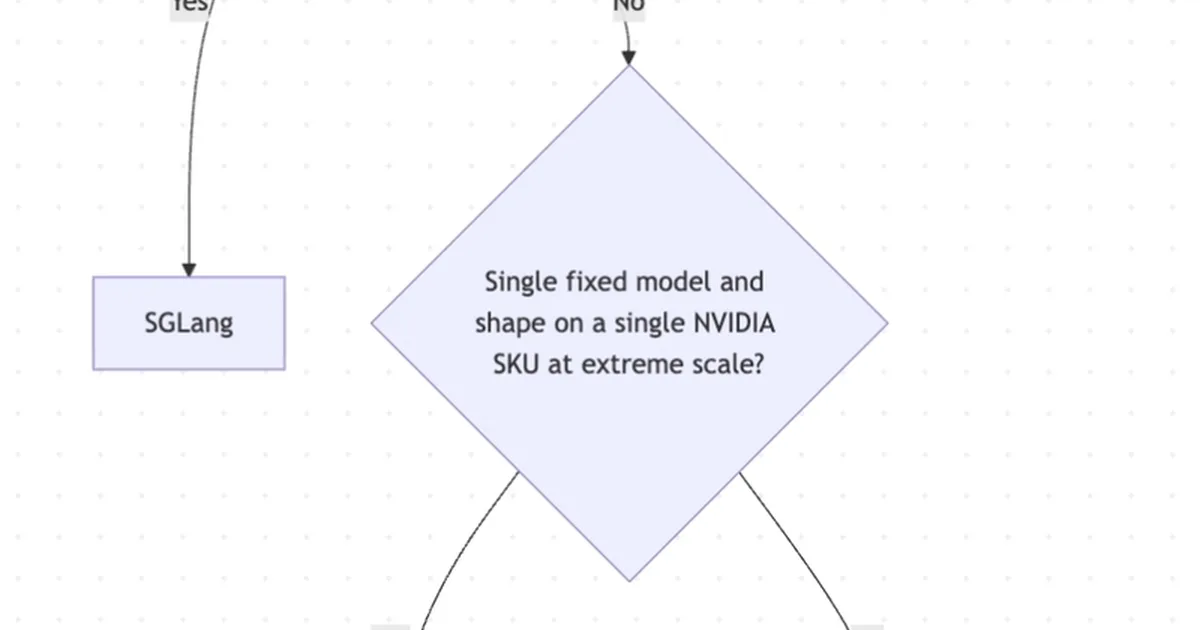
This article provides a guide for optimizing vLLM deployments, focusing on three critical configuration decisions that impact performance and cost. It details how static KV cache allocation can lead to GPU out-of-memory errors and emphasizes the importance of selecting the right serving framework, managing memory budgets for KV cache versus model weights, and configuring batching strategies like chunked prefill and prefix caching. The guide also outlines common failure modes and offers architectural insights for effective vLLM operation. AI

IMPACT Provides crucial operational insights for efficiently deploying and managing large language models using vLLM.

RANK_REASON Article provides operational guidance and configuration details for an existing AI serving framework.

Read on dev.to — LLM tag →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
vLLM production guide details key config decisions for performance

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
Article provides operational guidance and configuration details for an existing AI serving framework.
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
141 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. dev.to — LLM tag TIER_1 English(EN) · Damaso Sanoja ·

    vLLM in Production: Ranked Configuration Decisions, Failure Modes, and the Architecture That Makes Them Work

    <p>Production <a href="https://github.com/vllm-project/vllm" rel="noopener noreferrer">vLLM</a> deployments live or die on three configuration decisions, and getting any of them wrong shows up early: <a href="https://docs.vllm.ai/en/latest/configuration/conserving_memory/" rel="n…