PulseAugur
EN
LIVE 08:52:47

Guide to benchmarking LLM prompts and managing them with PromptMan

This tutorial explains how to build a custom scoring framework in Python to objectively benchmark prompt variants for large language models, moving beyond subjective evaluations. It details setting up a development environment, defining clear evaluation criteria, and using tools like the OpenAI client library and pytest. The second article discusses the challenges engineering teams face with managing and versioning prompts as application logic, highlighting PromptMan as a robust, open-source, on-premise solution with a REST API-first design for secure and scalable prompt management. AI

IMPACT Provides practical guidance for developers on systematically evaluating and managing LLM prompts, crucial for production-level AI applications.

RANK_REASON The cluster contains a tutorial on building a benchmarking framework for LLM prompts and a review of prompt management tools, which falls under research and tooling.

Read on dev.to — LLM tag →

AI-generated summary · Google Gemini · from 2 sources. How we write summaries →
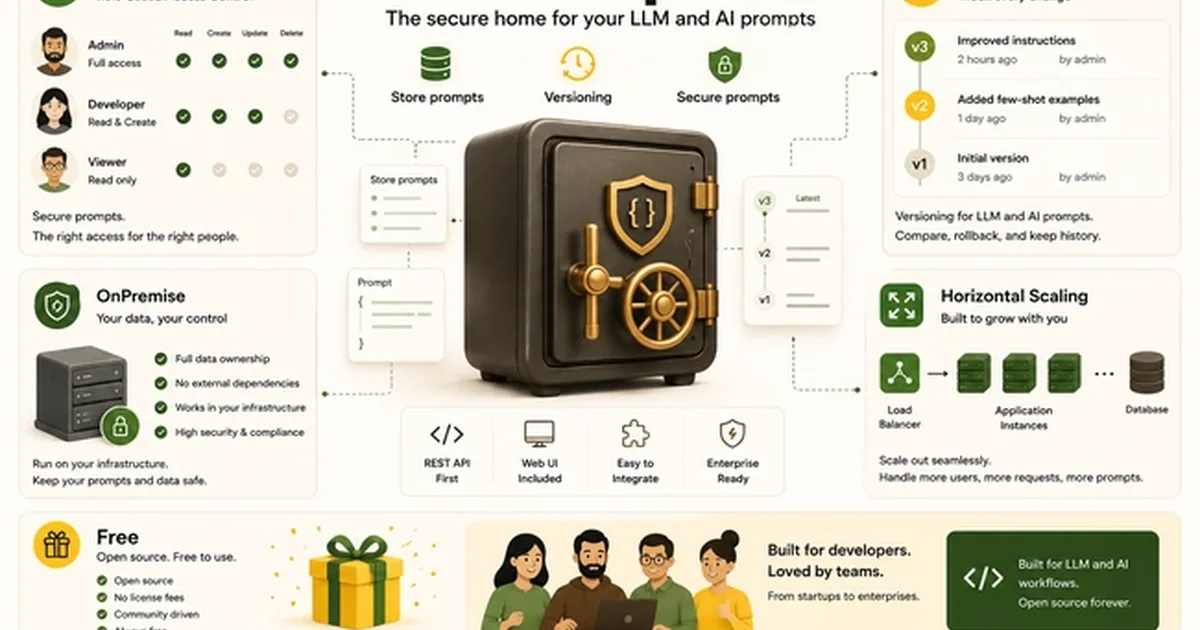
Guide to benchmarking LLM prompts and managing them with PromptMan

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
The cluster contains a tutorial on building a benchmarking framework for LLM prompts and a review of prompt management tools, which falls under research and tooling.
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
product, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
142 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [2]

  1. dev.to — LLM tag TIER_1 English(EN) · chinaabin ·

    Benchmark Prompt Variants: Build Scoring Framework

    <h1> Benchmarking Prompt Variants: Building a Scoring Framework from Scratch </h1> <h2> What You'll Learn </h2> <p>In this tutorial, you will learn how to systematically evaluate and compare different prompt variants for Large Language Models (LLMs). You will build a custom scori…

  2. dev.to — LLM tag TIER_1 English(EN) · Alexander Ivanov ·

    Prompt Versioning and Prompt Management for Engineering Teams

    <p><a class="article-body-image-wrapper" href="https://media2.dev.to/dynamic/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2Fmd8olqppa9apkixzhcgf.png"><img alt="Picture about Prompts in g…