PulseAugur
EN
LIVE 11:30:36

Free Kaggle GPU setup enables 35B multimodal LLM API

A developer has created a method to run a 35 billion parameter multimodal LLM on free Kaggle GPUs, overcoming the typical limitations of such platforms. The solution involves using Qwen3.6-35B-A3B quantized to 4-bit, hosted on Kaggle's T4 GPUs for up to 12 hours per session. It leverages llama.cpp for inference and an OpenAI-compatible API, with Cloudflare Quick Tunnel providing a stable public URL that supports token streaming, unlike other free tunneling services. AI

IMPACT Enables developers to run powerful LLMs on free cloud GPUs, bypassing costly hardware or API fees.

RANK_REASON The cluster describes a technical setup and guide for running an existing open-source LLM on a free platform, rather than a new model release or significant industry event.

Read on dev.to — LLM tag →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
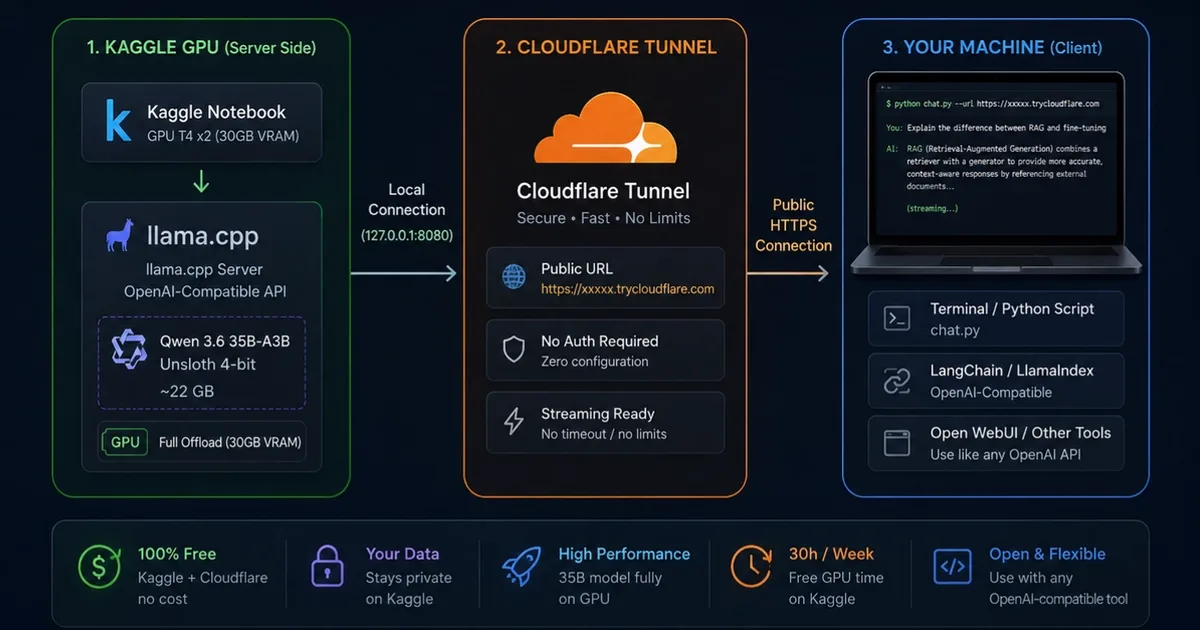
Free Kaggle GPU setup enables 35B multimodal LLM API

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The cluster describes a technical setup and guide for running an existing open-source LLM on a free platform, rather than a new model release or significant industry event.
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
130 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. dev.to — LLM tag TIER_1 English(EN) · Tahsine ·

    Free 35B Multimodal LLM Server on Kaggle GPU — Accessible from Any OpenAI-Compatible Client

    <h2> The Problem </h2> <p>Running a large language model locally is expensive. A GPU with enough VRAM to run a 35B model costs several thousand dollars. Cloud APIs are convenient, but you pay per token, your data goes through someone else's servers, and you have no flexibility ov…