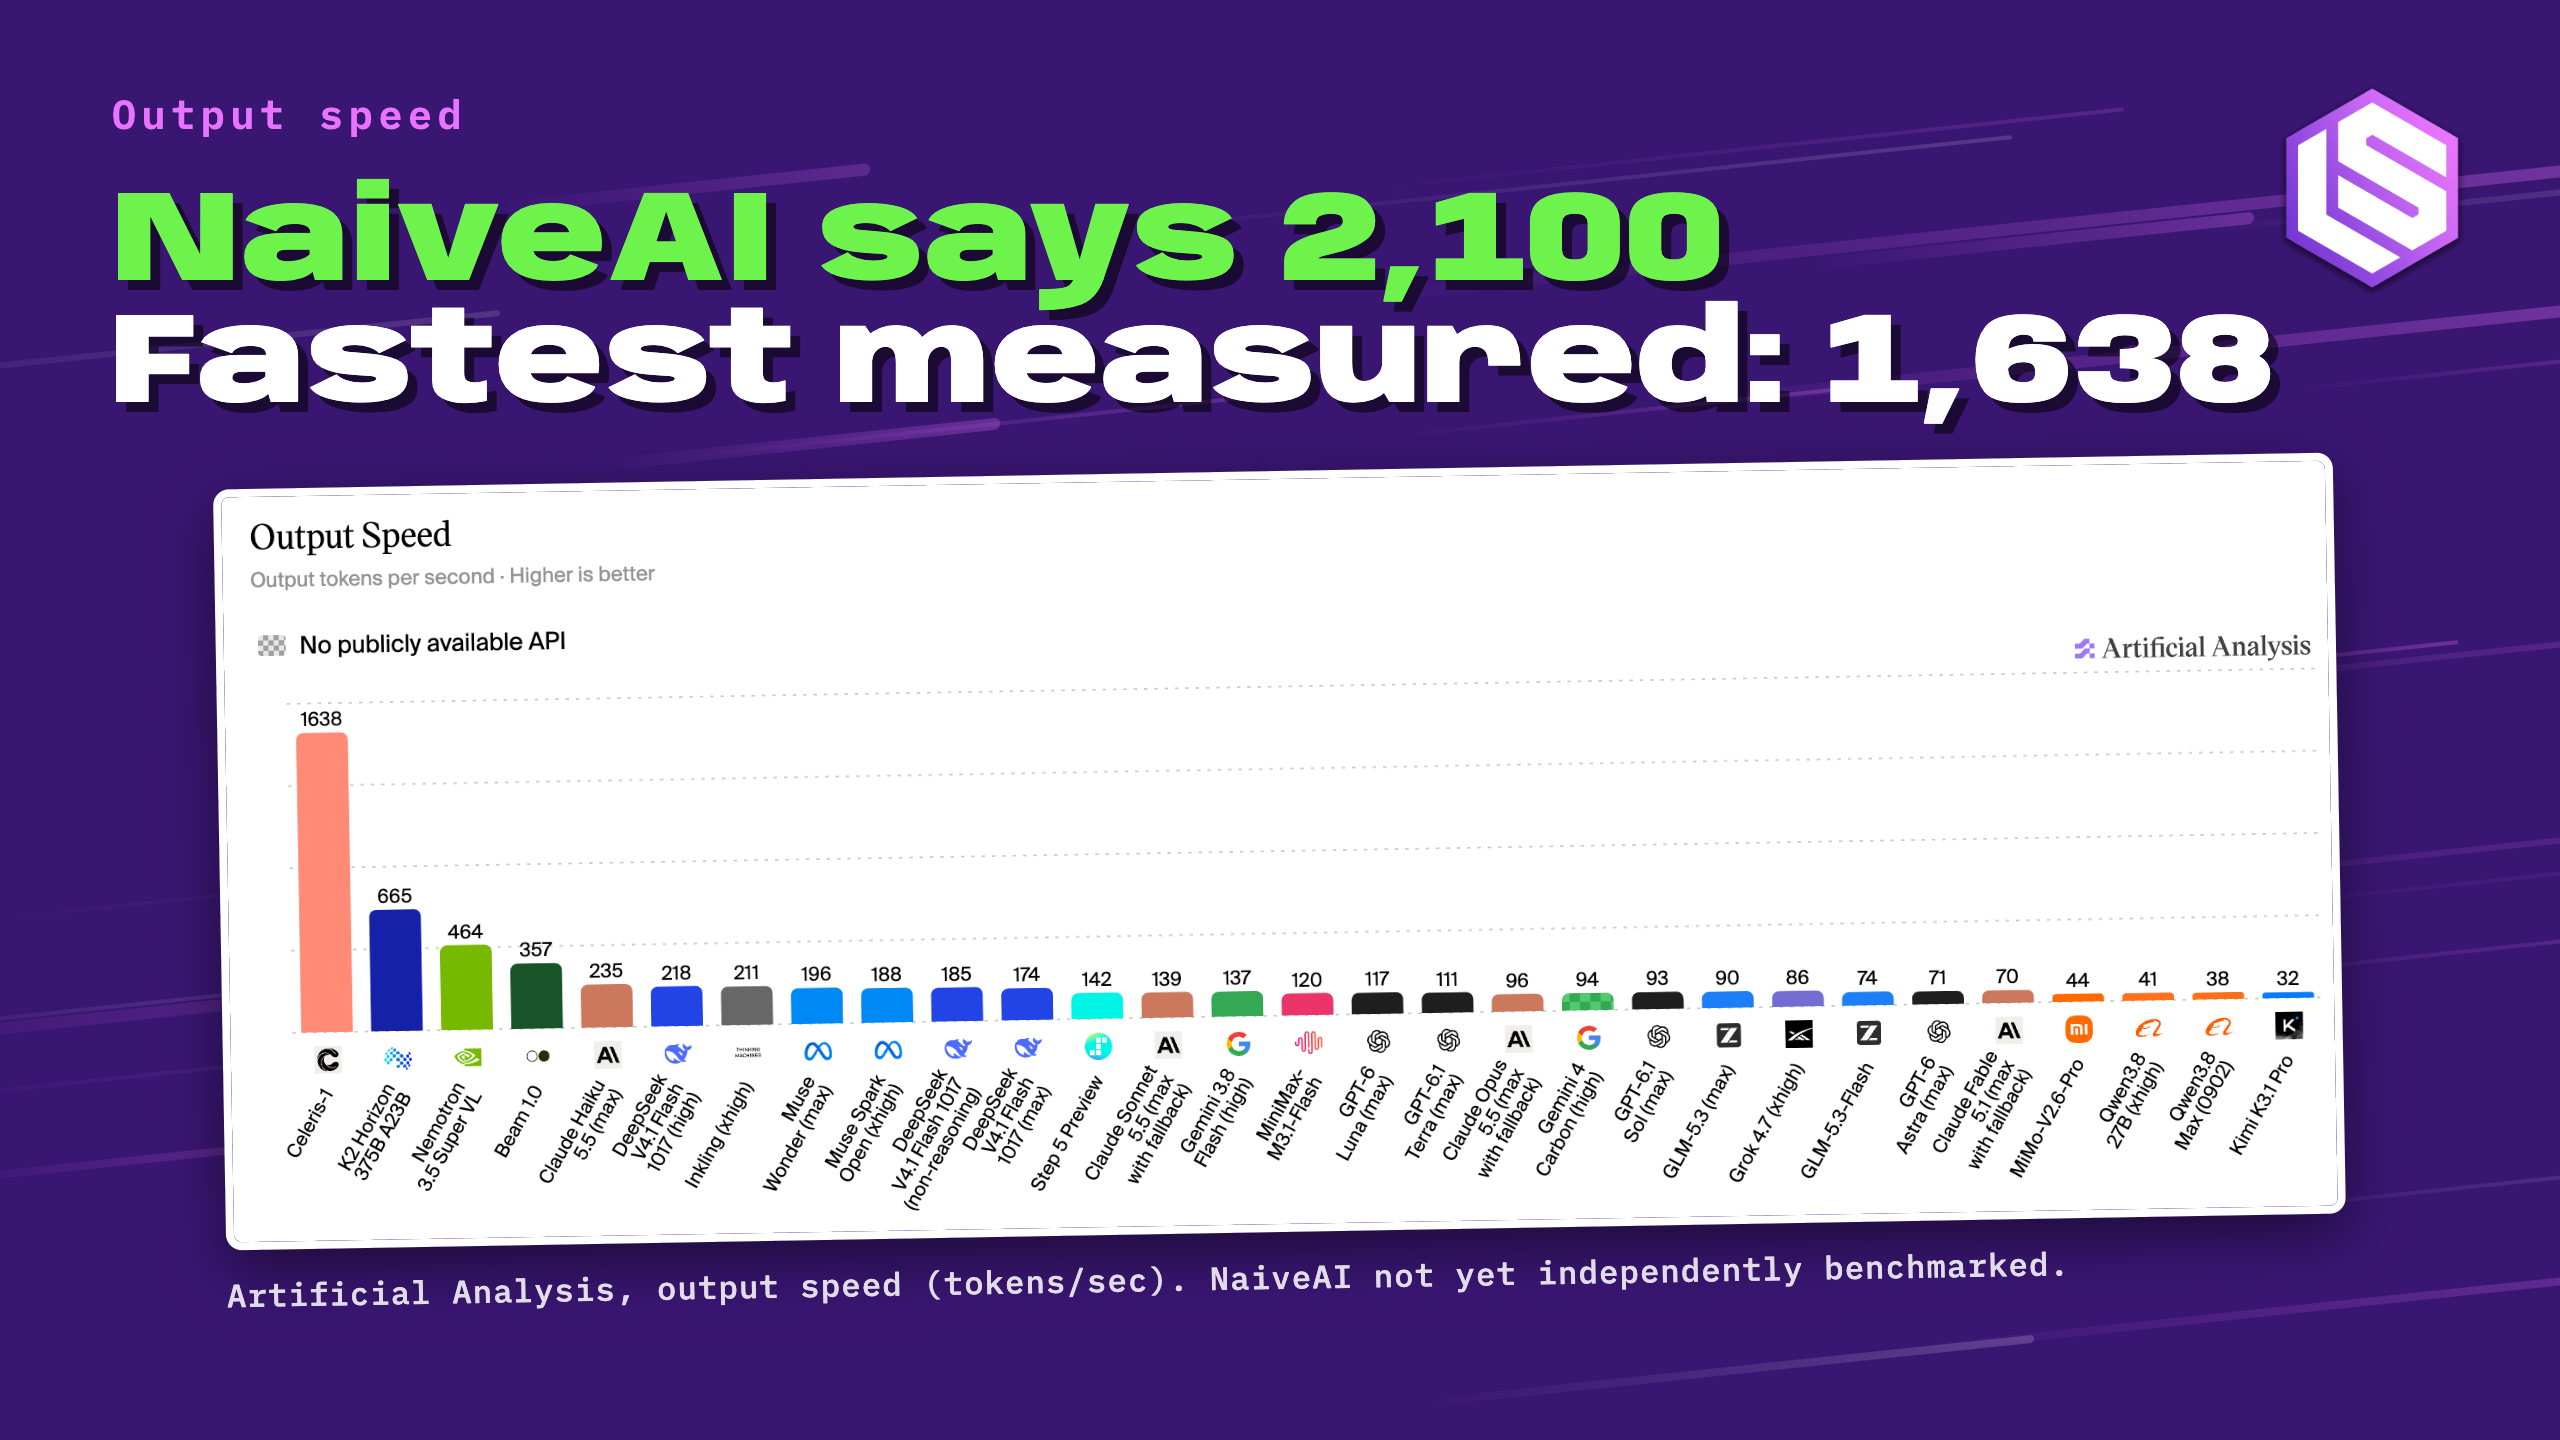
NaiveAI has released Naive-N0.5-Flash, an open-weights AI model designed for coding tasks and optimized for speed, promising up to 2,100 tokens per second. This model is an evolution of Xiaomi's MiMo-V2.5, further trained by NaiveAI with DeepSeek Sparse Attention layers and its NaiveRT inference engine. While Naive-N0.5-Flash demonstrates faster overall response times, it may take longer for complex reasoning tasks compared to models like DeepSeek V4.1 Flash 1017 and GLM-5.3-Flash, though its performance on the NL2Repo-Bench is superior. AI
IMPACT This model's focus on speed could accelerate AI research and development workflows by enabling faster iteration and experimentation.
RANK_REASON New open-weights model release from a company focused on AI development. [lever_c_demoted from frontier_release: ic=1 ai=1.0]
- Artificial Analysis
- DeepSeek
- General Language Model
- MiMo-V2.5
- MiMo-V2-Flash
- NaiveAI
- Naive-N0.5-Flash
- NaiveRT
- NL2Repo-Bench
- OpenRouter
- Xiaomi
AI-generated summary · Google Gemini · from 1 sources. How we write summaries →