PulseAugur
EN
LIVE 15:00:05

Llama 70B evaluations show context matters more than adversarial training

A new analysis using AuditBench and Natural Language Autoencoders (NLA) on Llama 70B Instruct fine-tunes reveals that evaluation methods are more sensitive to sampling techniques than adversarial training. The study found that "strong evidence" evaluation formats, which provide more context, are more robust to adversarial attacks like Knowledge-Targeted Optimization (KTO) and Supervised Fine-Tuning (SFT) compared to single-turn evaluations. Specifically, certain behaviors like reward wireheading and contextual optimism were only surfaced in the more robust "strong evidence" evaluations, indicating limitations in simpler testing methods. AI

IMPACT Highlights the limitations of current LLM evaluation methods and suggests "strong evidence" formats are more reliable for detecting nuanced behaviors.

RANK_REASON The cluster details a research paper analyzing LLM evaluation methods and their robustness to adversarial training. [lever_c_demoted from research: ic=1 ai=1.0]

Read on LessWrong (AI tag) →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
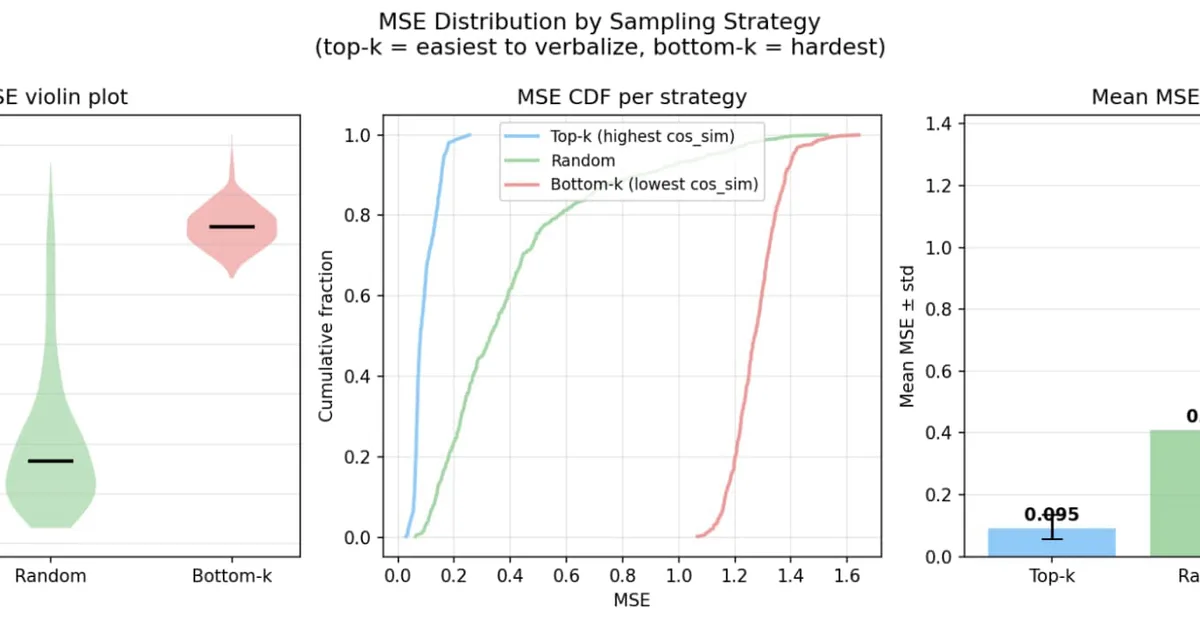
Llama 70B evaluations show context matters more than adversarial training

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The cluster details a research paper analyzing LLM evaluation methods and their robustness to adversarial training. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, safety
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
145 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · Realmbird ·

    NLA Verbalizations on AuditBench: Llama 70B

    <h1><span>Quick Summary:</span></h1><ul><li value="1"><span>Ran Llama 70B through Audit Bench with NLA</span></li><li value="2"><span>Strong Evidence evals were less sensitive to sampling method and more robust to KTO and SFT adversarial training than Single Turn evals</span></li…