PulseAugur
EN
LIVE 06:40:17

New method simplifies language model interpretability

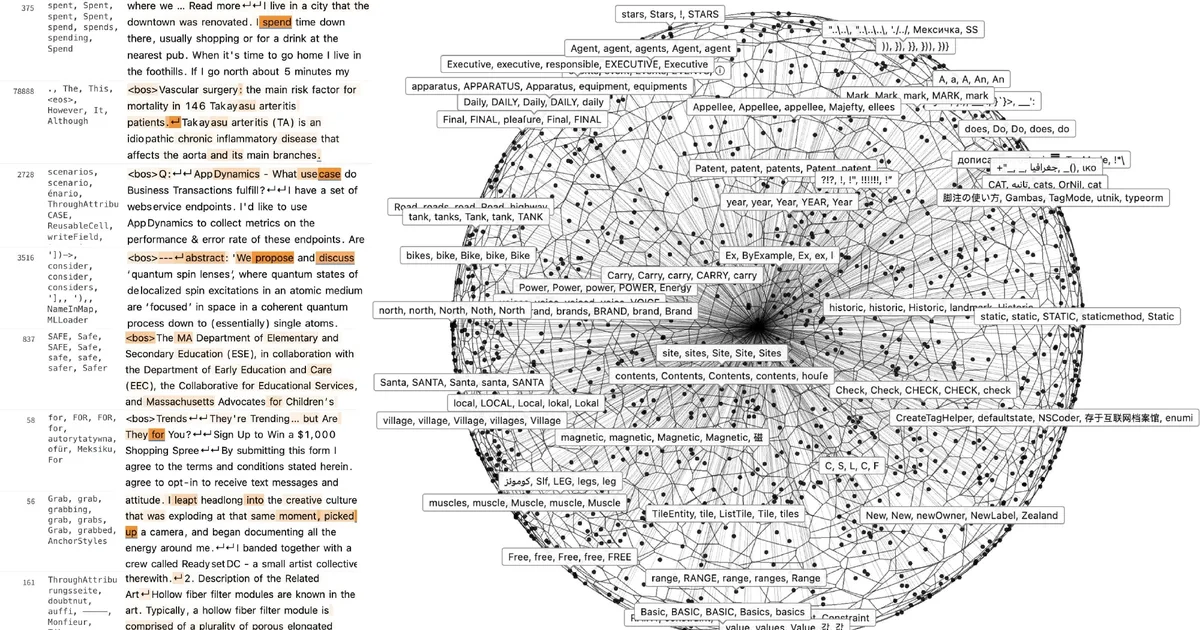
Researchers have introduced Exemplar Partitioning (EP), a new method for mechanistic interpretability in language models that offers a more streamlined approach than existing dictionary-learning techniques like sparse autoencoders. EP focuses on identifying interpretable structures within activation space by partitioning it based on observed exemplars, without the reconstruction and sparsity losses inherent in SAEs. This method achieves competitive performance on benchmarks, such as the AxBench latent concept-detection benchmark, with significantly reduced computational cost compared to SAEs. AI

IMPACT Offers a computationally cheaper alternative for understanding internal model representations, potentially accelerating interpretability research.

RANK_REASON The cluster describes a new research paper introducing a novel method for mechanistic interpretability in language models. [lever_c_demoted from research: ic=1 ai=1.0]

Read on LessWrong (AI tag) →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
New method simplifies language model interpretability

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The cluster describes a new research paper introducing a novel method for mechanistic interpretability in language models. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
146 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · Jessica Rumbelow ·

    An Introduction to Exemplar Partitioning for Mechanistic Interpretability

    <p><span>Most of what we currently call "feature discovery" in language models is wrapped up in dictionary-learning methods like </span><a href="https://arxiv.org/abs/2309.08600"><span>sparse autoencoders (SAEs)</span></a><span> – which work, and which have been scaled to million…