PulseAugur
EN
LIVE 01:56:15

Evaluate LLMs for under $1 using Qwen2.5-0.5B

This post details a cost-effective method for evaluating large language models, demonstrating that comprehensive benchmarks can be run for under a dollar. The author used a free Google Colab T4 instance to test the Qwen2.5-0.5B model on three distinct tasks: GSM8K for math reasoning, HellaSwag for commonsense, and TruthfulQA-MC2 for truthfulness. The experiment focused on measuring runtime and cost, utilizing the lm-evaluation-harness and making specific adjustments to optimize performance and reduce expenses, such as capping token generation length. AI

IMPACT Demonstrates that rigorous LLM evaluation is accessible and affordable, enabling broader testing and comparison of models.

RANK_REASON The article details a methodology for evaluating LLMs using standard benchmarks, focusing on cost and runtime, which constitutes research into evaluation techniques. [lever_c_demoted from research: ic=1 ai=1.0]

Read on dev.to — LLM tag →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
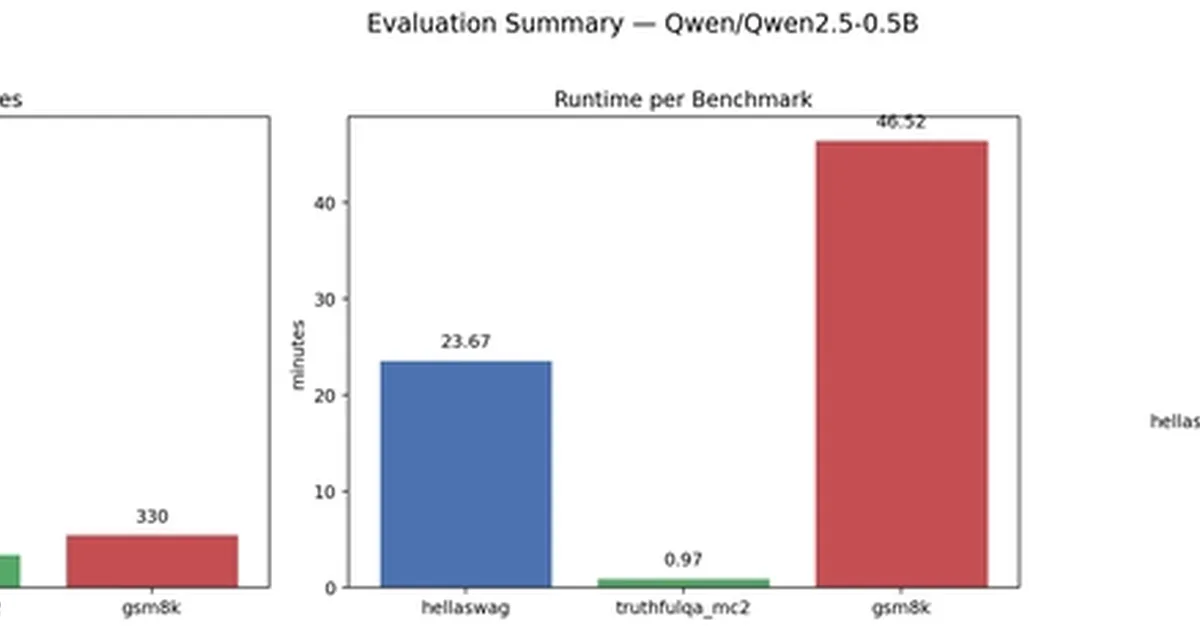
Evaluate LLMs for under $1 using Qwen2.5-0.5B

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The article details a methodology for evaluating LLMs using standard benchmarks, focusing on cost and runtime, which constitutes research into evaluation techniques. [lever_c_demoted from research:…
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
142 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. dev.to — LLM tag TIER_1 English(EN) · Thokozani Buthelezi ·

    Evaluating LLMs for Under a Dollar

    <h2> Why Evals Matter </h2> <p>Training a model is only half the job. Without a systematic way to measure what it can actually do, you are flying blind. The problem is that evaluation is easy to do badly, you can run a benchmark, get a number, and walk away thinking you know some…