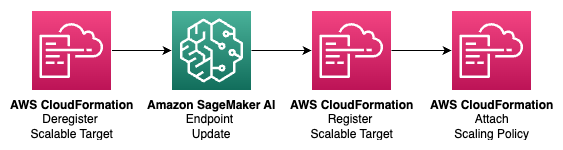
A new approach for auto-scaling Text-to-Speech (TTS) models on Amazon SageMaker AI aims to eliminate guesswork in setting scaling targets. This method, demonstrated with the Kokoro-82M model, replaces arbitrary values with measurements of maximum concurrency per instance before SLO breaches (Q_max) and end-to-end scale-out time (T_total). By deriving scaling thresholds and cooldowns from these metrics, the solution ensures more efficient resource utilization and better adherence to latency service level objectives. AI
IMPACT Improves efficiency and reliability of TTS model deployments on SageMaker, reducing costs and preventing latency issues.
RANK_REASON Blog post detailing a technical solution for optimizing a specific feature (auto-scaling) within an existing AI platform (Amazon SageMaker).
Read on AWS Machine Learning Blog →
- Amazon SageMaker
- AWS
- AWS Cloud Development Kit
- ConcurrentRequestsPerModel
- ISTFTNet
- Kokoro-82M
- Text To Speech
- StyleTTS2
AI-generated summary · Google Gemini · from 5 sources. How we write summaries →