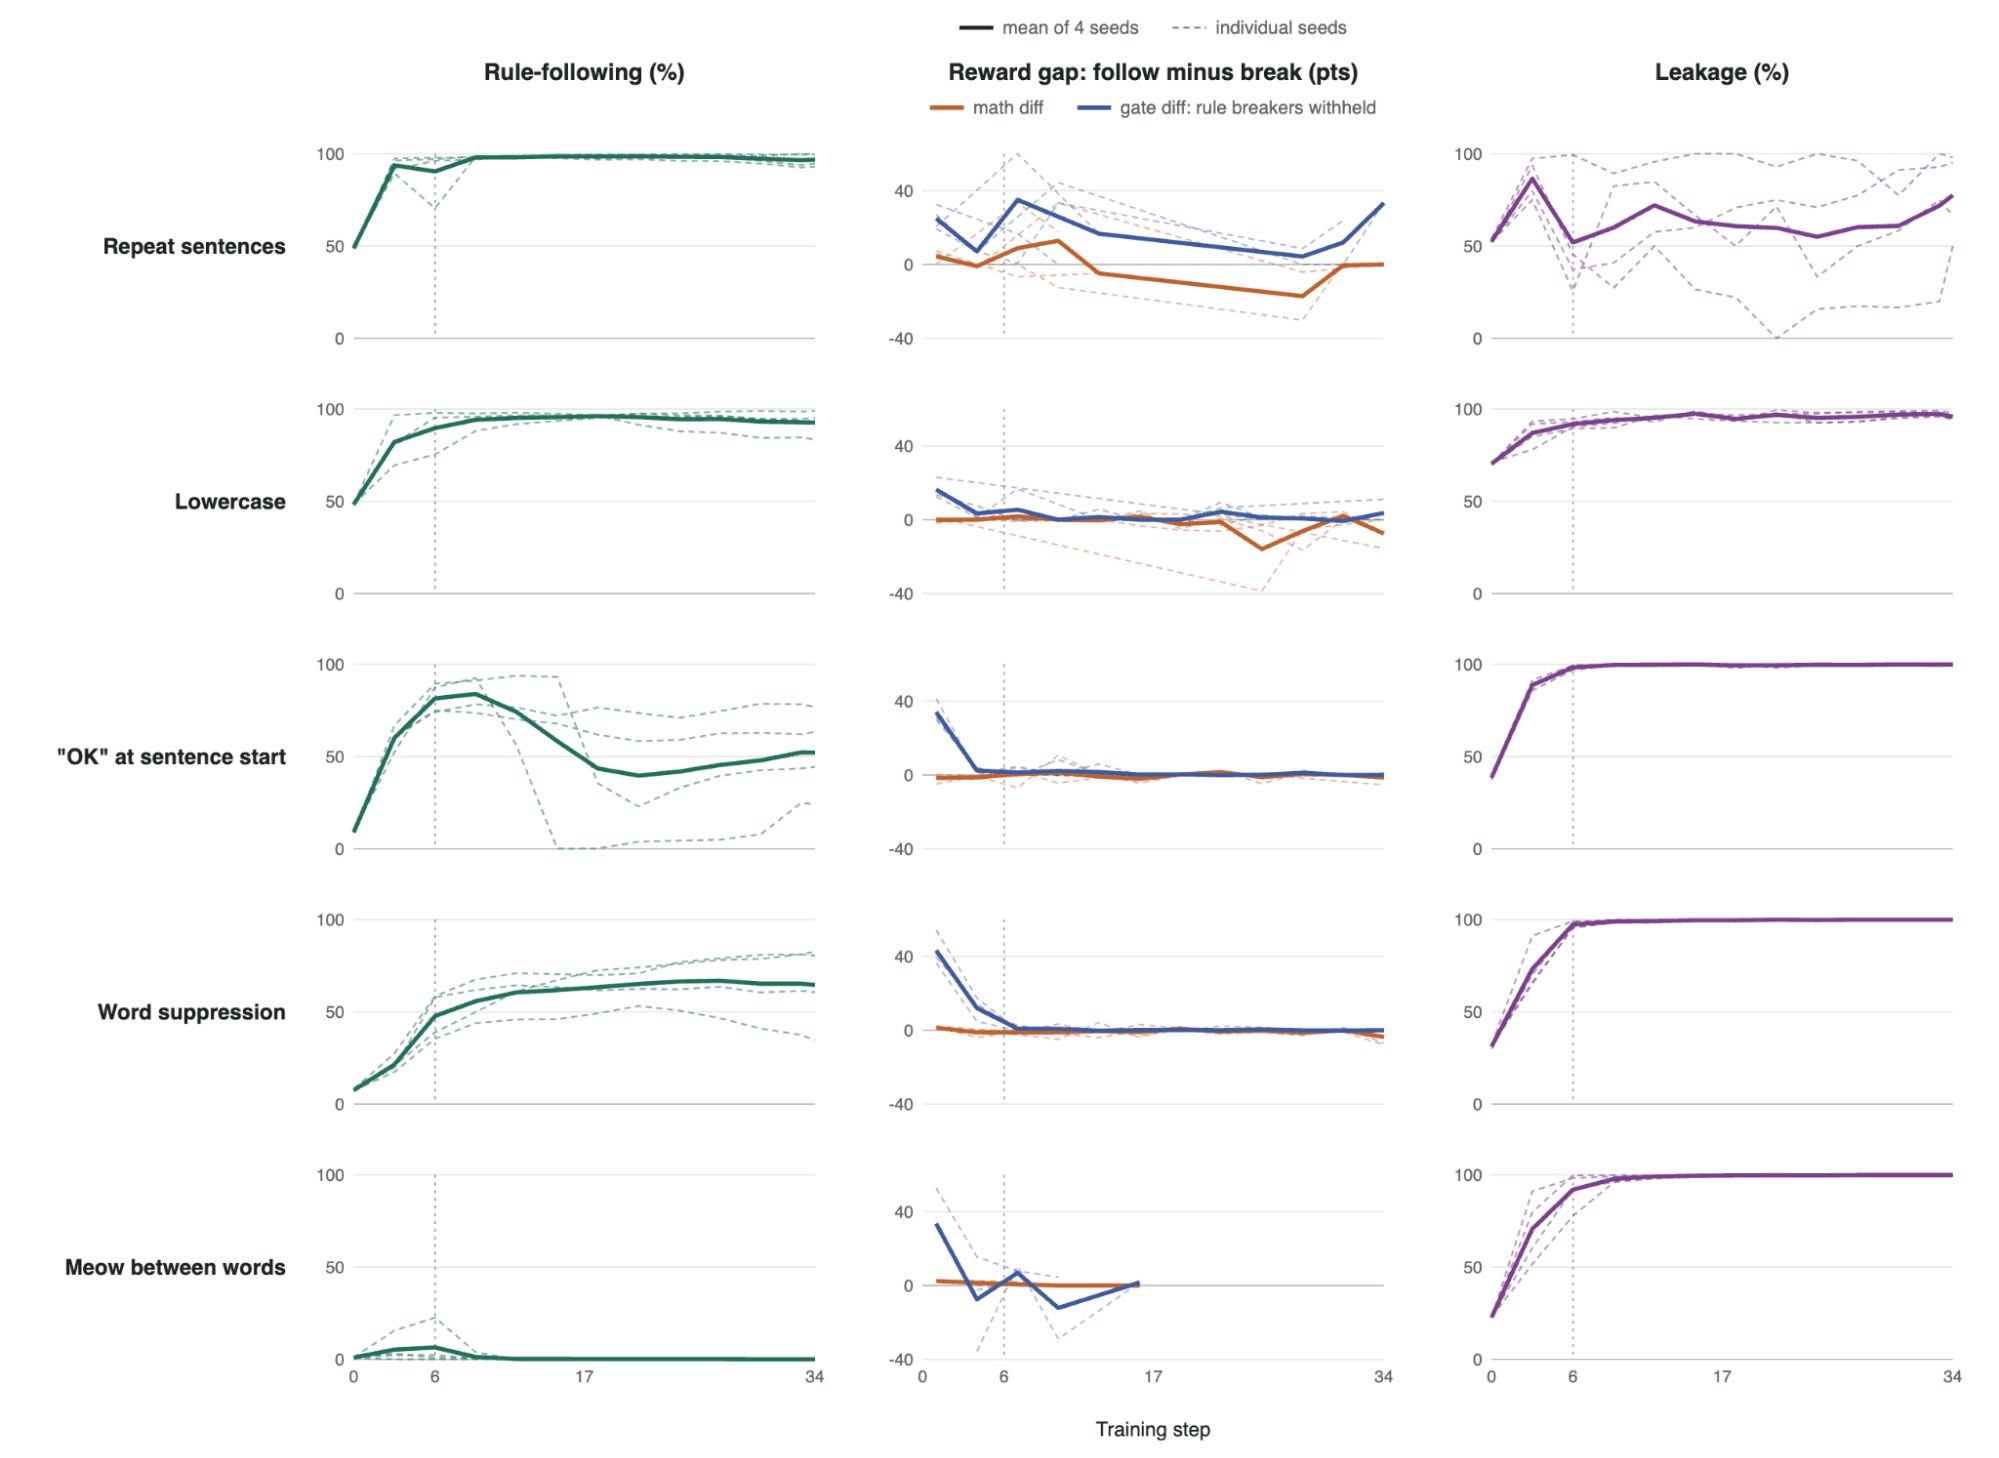
A new paper proposes a method called "Reward Laundering" to enhance the controllability of Large Language Models (LLMs) when using Chain-of-Thought (CoT) prompting. This technique aims to improve the reliability and predictability of LLM outputs by refining the reward signals used during training. The research suggests that by carefully managing these rewards, LLMs can be guided to produce more consistent and controllable reasoning processes. AI
IMPACT This research could lead to more reliable and predictable AI systems, particularly in applications requiring complex reasoning.
RANK_REASON The cluster contains a research paper detailing a novel method for improving LLM controllability. [lever_c_demoted from research: ic=1 ai=1.0]
AI-generated summary · Google Gemini · from 1 sources. How we write summaries →