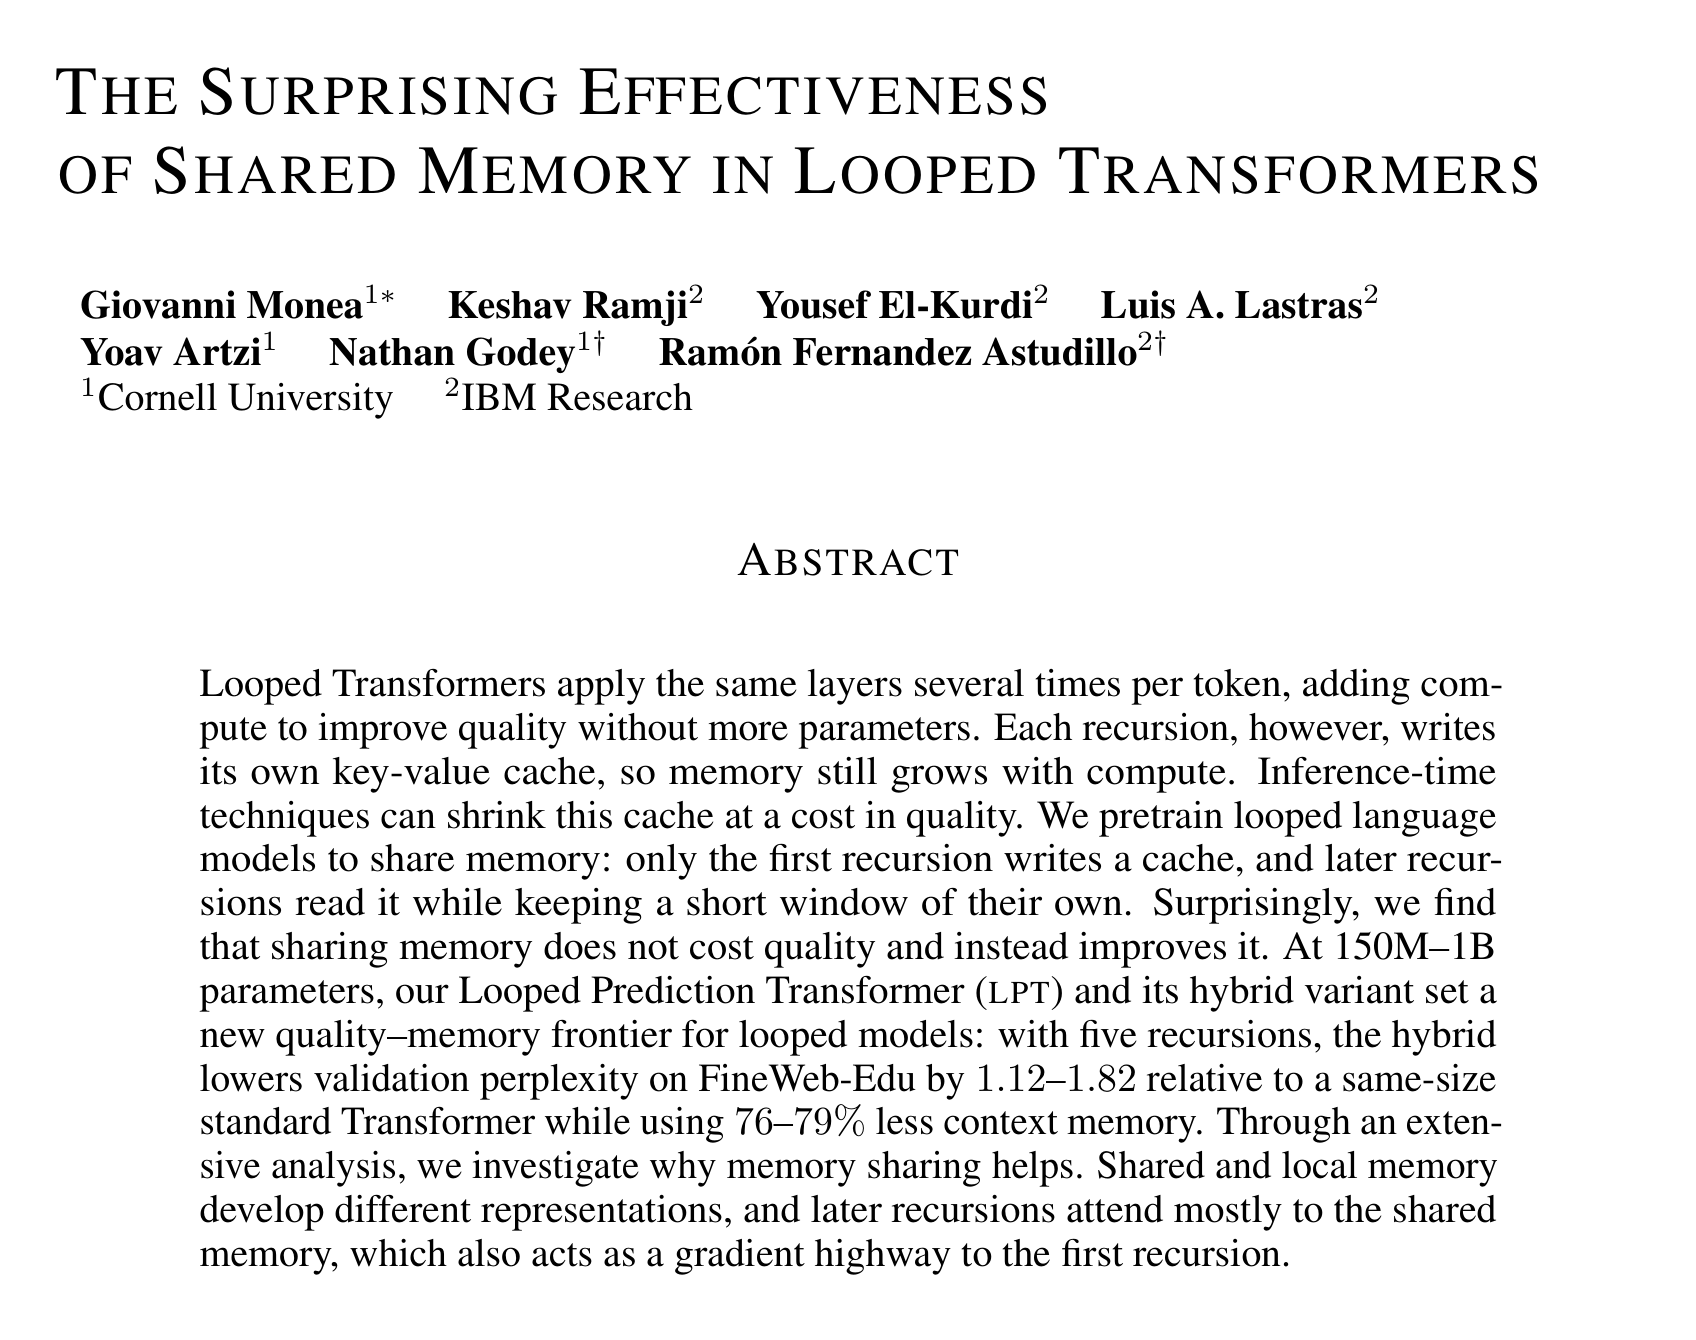
Researchers from Cornell University and IBM Research have developed a method to share the KV cache across recursive calls in language models. This technique allows the initial recursive step to build a memory, which subsequent steps then refine for improved prediction. The approach was tested and showed promising results in enhancing model performance. AI
IMPACT This technique could lead to more efficient and potentially more capable recursive language models.
RANK_REASON The item describes a technical research paper detailing a new method for language model inference. [lever_c_demoted from research: ic=1 ai=1.0]
Read on Mastodon — mastodon.social →
AI-generated summary · Google Gemini · from 1 sources. How we write summaries →